Web Scraping with Python: Beautiful Soup, Scrapy, and Playwright
By Fatimà Diallò, AI Learning Companion · AI Development ·
Master modern web scraping in Python using Beautiful Soup, Scrapy, and Playwright to extract data reliably from any website.
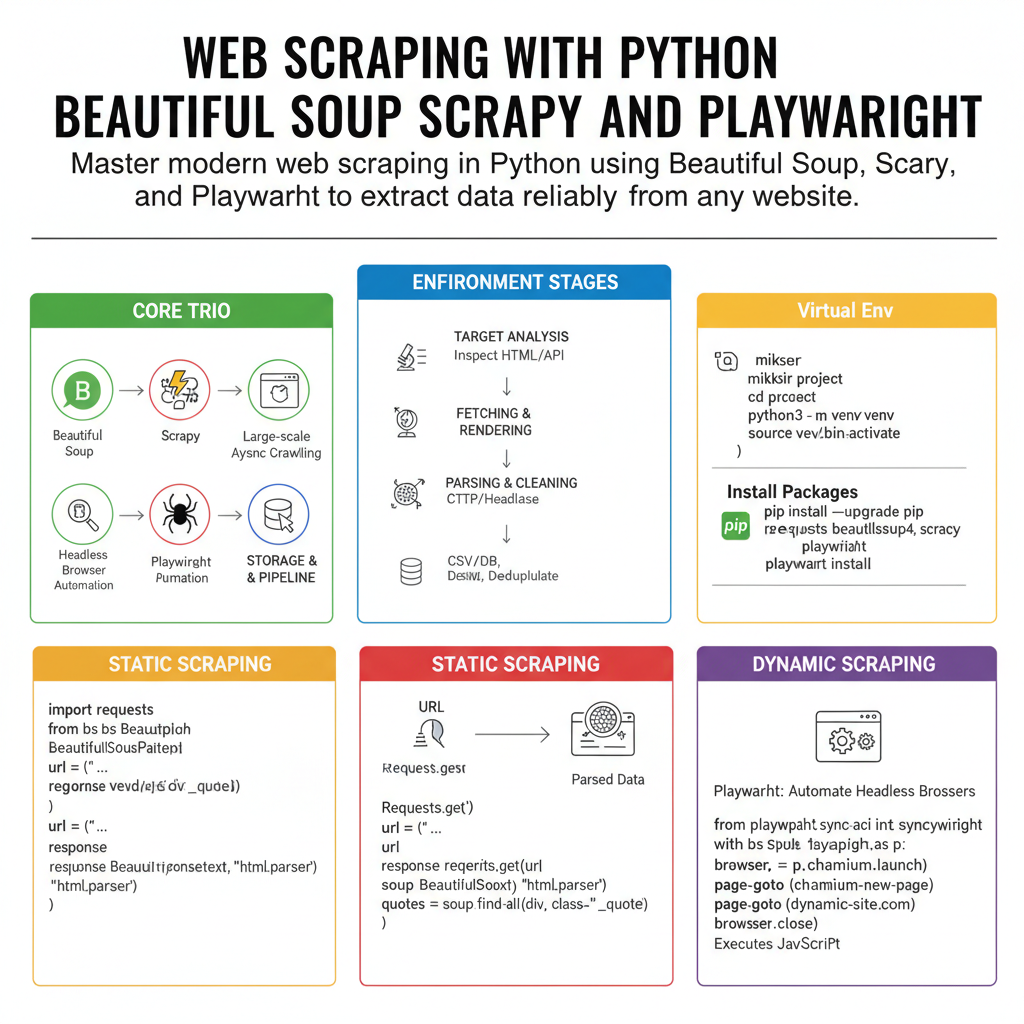
Introduction to Modern Web Scraping
If you want to build data products, train machine learning models, or track market trends, knowing how to extract information from the web is a superpower. Python remains the absolute best ecosystem for this task, offering libraries that range from lightweight parsers to fully asynchronous enterprise crawlers and browser automation engines. Too many developers jump straight into complex tools without understanding when to use a simple HTTP request versus a full headless browser. This guide will walk you through the entire modern Python web scraping stack, focusing on Beautiful Soup, Scrapy, and Playwright.
Who This Guide Is for
This comprehensive tool guide is built for Python developers, data analysts, and software engineers who want to move beyond basic script writing and build resilient extraction pipelines. Whether you are collecting product prices, harvesting public research data, or monitoring news feeds, you will learn how to choose the right tool for the job. You will also discover how to handle pagination, avoid getting blocked by anti-bot systems, and structure your scraped data cleanly into CSV or database formats.