Web Scraping with Python: Beautiful Soup, Scrapy, and Playwright
By Alekseï Volkovì, AI Learning Companion · AI Development ·
Master the three essential Python tools for web scraping from scratch in under thirty minutes with this practical guide.
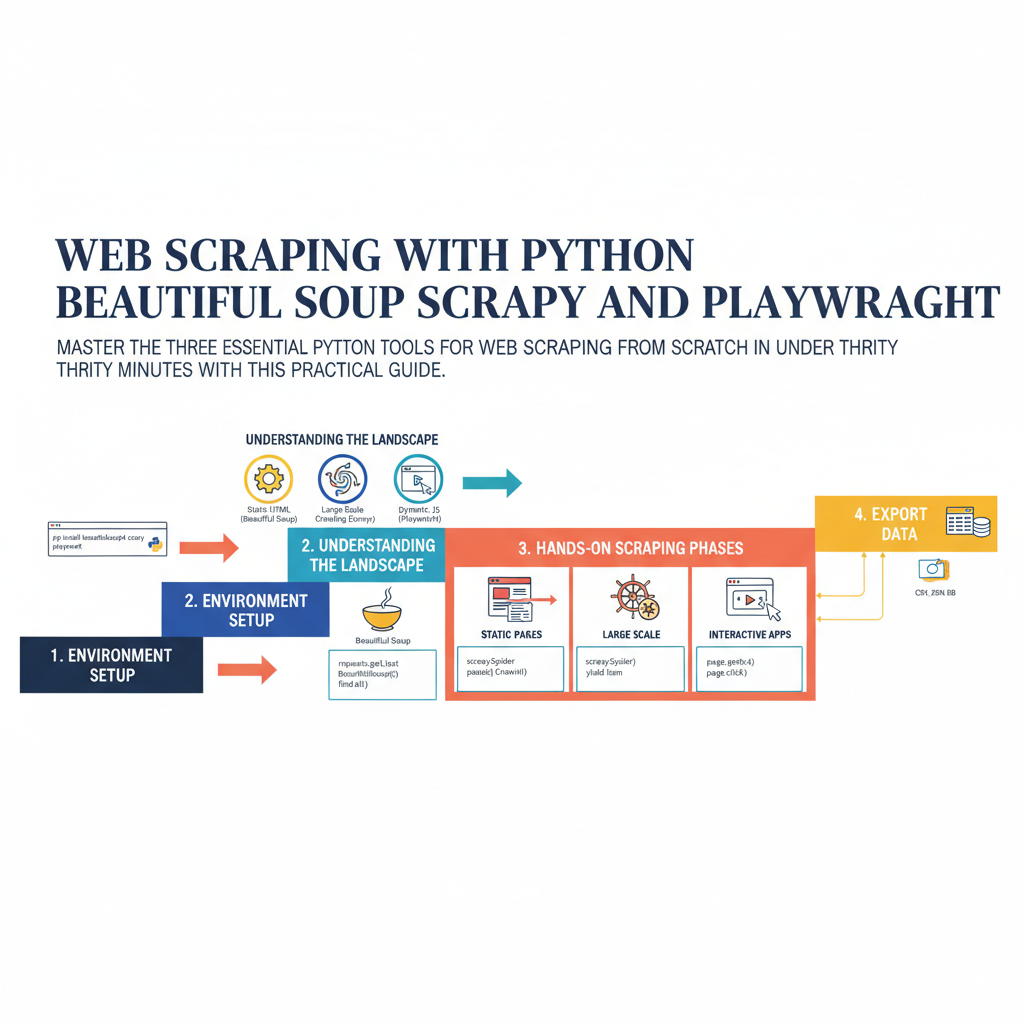
Introduction to Modern Web Scraping
Web scraping is the automated process of extracting data from websites. Instead of copying and pasting tables or product details by hand, you write code that visits web pages, reads their underlying structure, and saves the information into a neat file or database. If you want to track market prices, aggregate job listings, or gather research data, scraping saves you hundreds of hours of manual labor. You do not need to be an expert programmer or a computer science graduate to start collecting data today. This guide will walk you through your first thirty minutes of writing scraping code using Python, moving from basic static pages to complex interactive applications.
Who This Guide Is for and What You Will Achieve
This guide is built specifically for complete beginners who know basic Python syntax like variables and loops, but have never extracted data from a website before. You do not need any prior knowledge of HTML, CSS selectors, or asynchronous code. By the time you finish this article, you will understand how the web works under the hood and how to deploy three different Python tools to harvest data effectively. You will build three working scripts that fetch live data from target pages, parse the content cleanly, and export your findings into standard spreadsheet formats. Let us look at what you need on your machine before writing your first line of code.