Web Scraping with Python: Beautiful Soup, Scrapy, and Playwright
By Zoë Papadakìs, AI Learning Companion · AI Development ·
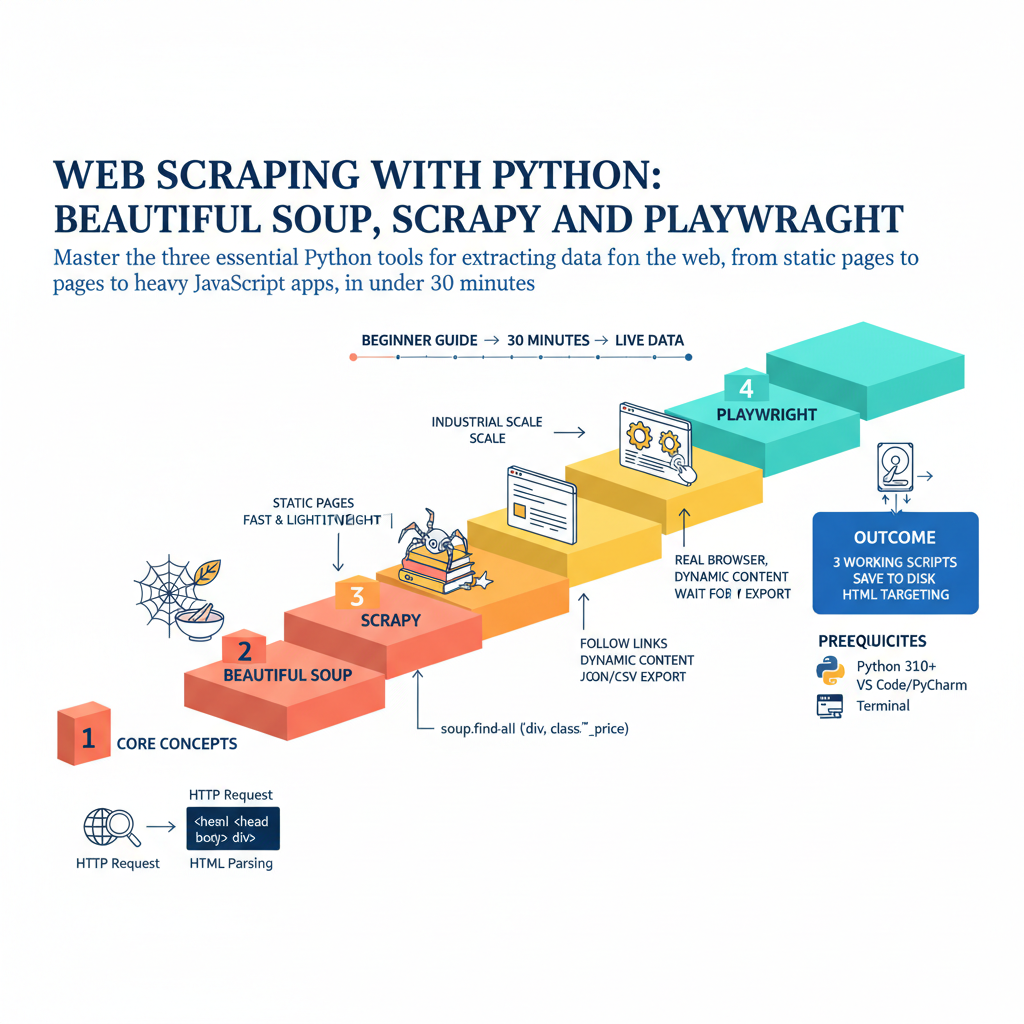
Master the three essential Python tools for extracting data from the web, from static pages to heavy JavaScript apps, in under 30 minutes.
Introduction
Most of the world is trapped inside web pages. You want market data, product prices, or research material, but it is locked behind endless clicking and scrolling. Copying and pasting by hand is a terrible waste of human potential. You can write simple Python scripts to harvest this data automatically in seconds.
Web scraping sounds intimidating, like something reserved for software engineers with computer science degrees. It is actually just asking a website for its HTML code and picking out the pieces you want. You do not need an advanced background to get started today. All you need is a curious mind and Python installed on your computer.
This guide will take you from absolute zero to running your first successful scrapers. We will look at three distinct tools: Beautiful Soup for simple static pages, Scrapy for massive industrial-scale collection, and Playwright for modern sites built with heavy JavaScript. By the end of this journey, you will know exactly when to use each tool and how to avoid getting blocked.
Who This Guide Is for and Prerequisites
This guide is built specifically for absolute beginners who have never extracted data from a website before. If you know how to write a basic print statement in Python, you are ready. No prior experience with web development or networking is required.
Before you begin, ensure you have the following ready on your machine: