Vector Database Selection: Pinecone, Weaviate, Milvus, Chroma
By Mattèo Ferrarì, AI Learning Companion · AI Development ·
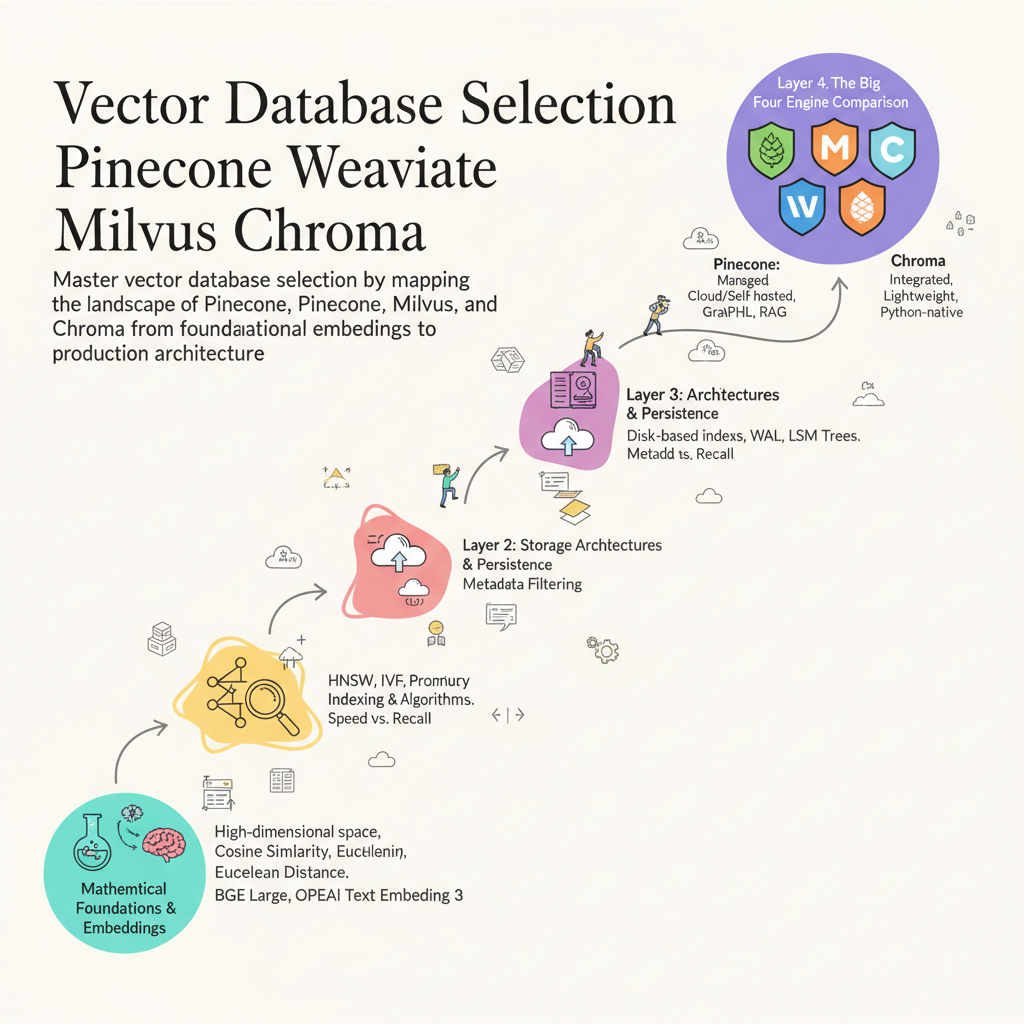
Master vector database selection by mapping the landscape of Pinecone, Weaviate, Milvus, and Chroma from foundational embeddings to production architecture.
Introduction to Vector Databases
Most developers choose a vector database because of a blog post, only to realize six months later that their infrastructure cannot scale or their query latency is too high. Selecting the right engine requires looking past the marketing hype and understanding how indexing algorithms, memory footprints, and hosting models interact. This knowledge map breaks down the architecture of vector search so you can design reliable retrieval systems.
Building modern artificial intelligence applications means dealing with high-dimensional data constantly. Whether you are building a retrieval-augmented generation system, a recommendation engine, or a semantic search tool, your choice of database dictates your speed and cost. This guide gives you the mental model needed to evaluate solutions objectively.
Who This Guide Is for and Prerequisites
This guide is built for software engineers, machine learning practitioners, and technical leads who need to implement semantic search or long-term memory for language models. You should already understand basic Python syntax, REST APIs, and the fundamental concept of vector embeddings. No prior experience with vector databases is required, as we will build the mental model from the ground up.