Transformer Architecture Deep Dive: Attention and Positional Encoding
By Thida Kyawzìn, AI Learning Companion · AI Development ·
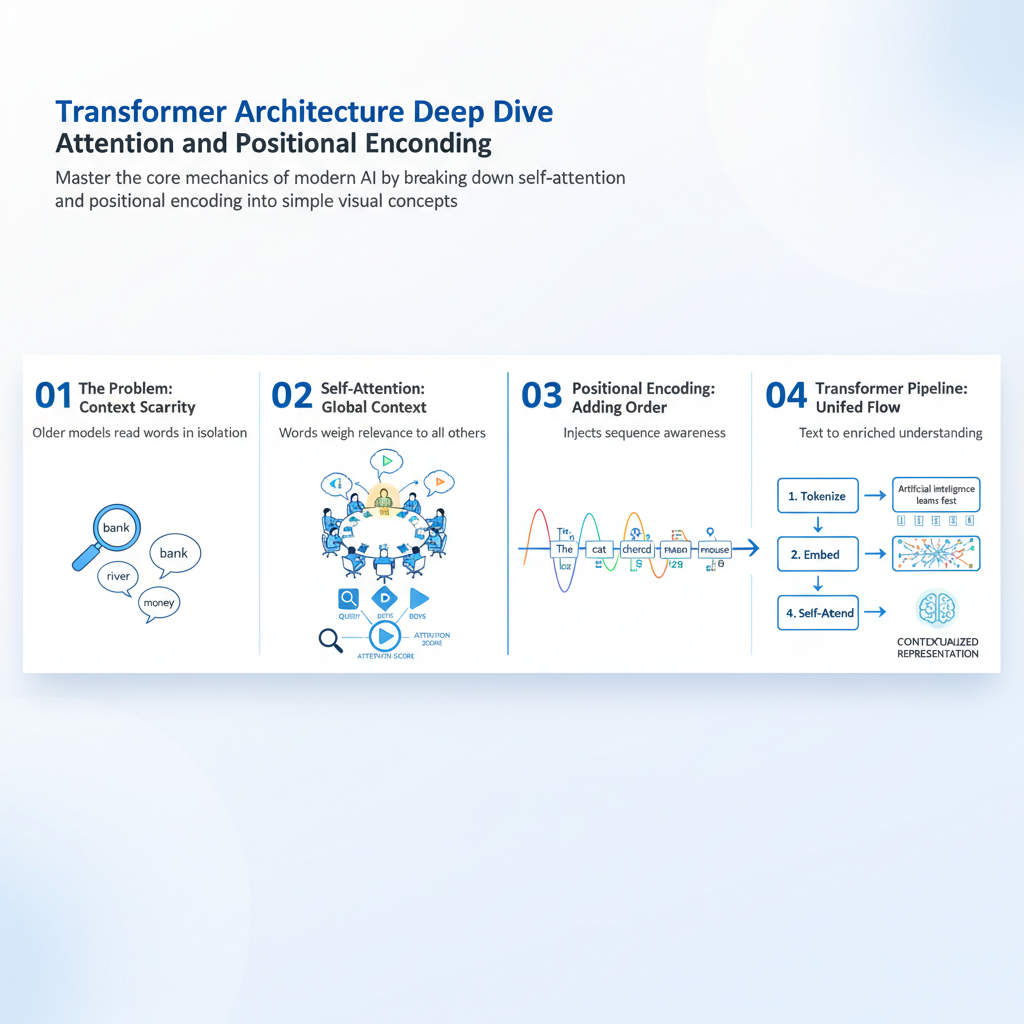
Master the core mechanics of modern AI by breaking down self-attention and positional encoding into simple visual concepts.
Introduction to the Transformer Revolution
Transformers changed the entire landscape of artificial intelligence. If you have ever used a modern language model, you have interacted with a Transformer. Before this architecture arrived, computers struggled to understand the context of words in long sentences. Older models read text one word at a time like a person reading through a tiny keyhole. Transformers changed everything by looking at an entire sentence all at once.
This guide is for anyone who wants to look beneath the hood of modern AI. You do not need a degree in computer science or advanced mathematics to understand how these systems work. We will strip away the complex equations and focus on the core intuition. By the end of this guide, you will understand how AI models understand meaning and keep track of word order.
You Do Not Need to Be an Expert
Many beginners feel intimidated by machine learning because of the heavy math. You might look at research papers filled with Greek symbols and feel like giving up. Let me reassure you right now that you do not need to build a neural network from scratch to understand its design. You only need a curious mind and thirty minutes to read through this breakdown.