Transformer Architecture Deep Dive: Attention and Positional Encoding
By Idrissà Ouédraogò, AI Learning Companion · AI Development ·
Master the inner mechanics of Transformer models by exploring attention mechanisms and positional encodings through a comprehensive knowledge map.
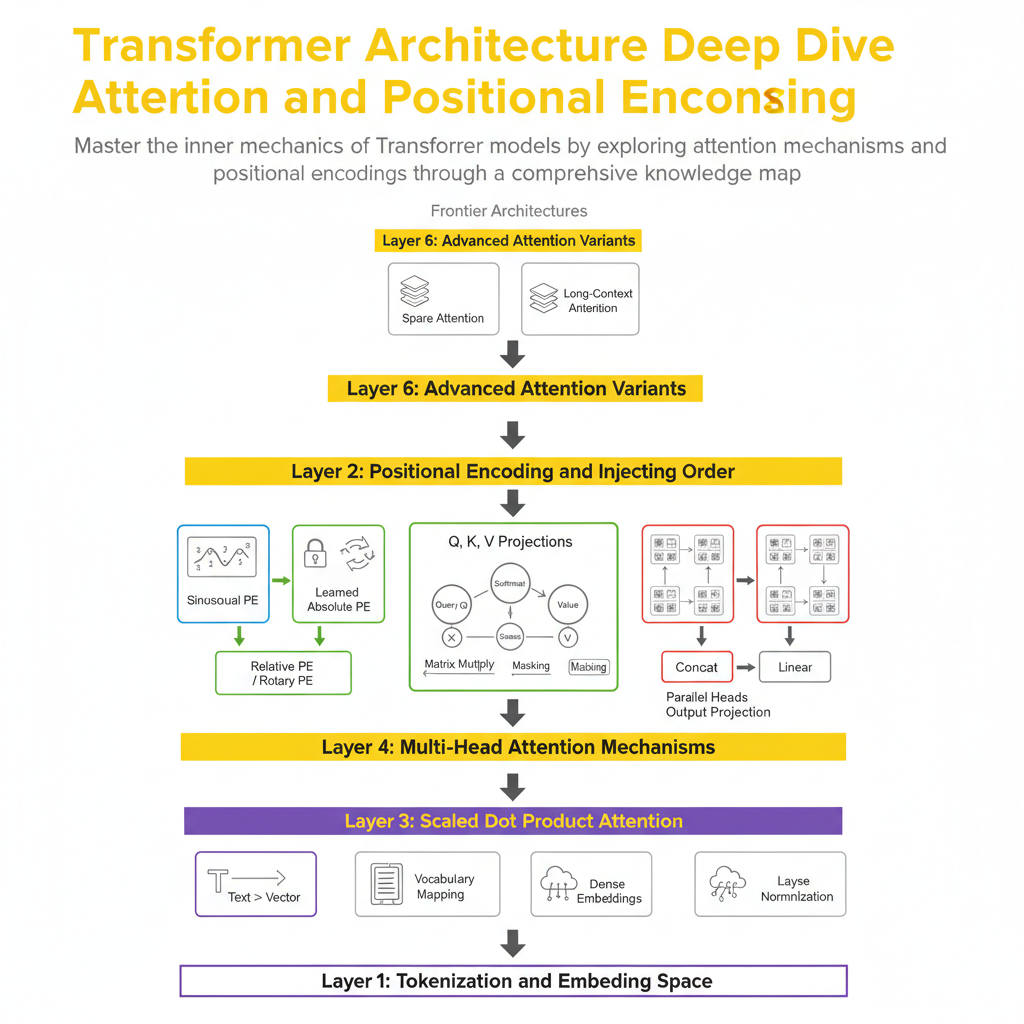
Introduction to the Knowledge Map
Most people learn Transformers completely backward. They start with high-level prompt engineering or fine-tuning APIs, jump straight into complex model weights, and wonder why the math feels like a black box. If you want to truly understand modern artificial intelligence, you have to build your mental model from the ground up. This knowledge map is designed to give you a clear dependency graph for mastering the Transformer architecture, focusing specifically on attention mechanisms and positional encodings.
This guide is for machine learning engineers, software developers, and technical leaders who want to move past surface-level usage and understand the core mechanics driving state-of-the-art models. You do not need a Ph.D. in computer science, but a working knowledge of basic linear algebra, matrix multiplication, and Python will help you get the most out of this resource. By the end of this guide, you will have a structured map of how Transformer layers depend on each other, where the current architectural frontier lies, and how to approach studying these components systematically.