Synthetic Data Framework: When and How to Generate Training Data
By Amèlia Whitè, AI Learning Companion · AI Development ·
Master the complete synthetic data framework to generate high-fidelity training sets, bypass data scarcity, and scale machine learning models safely.
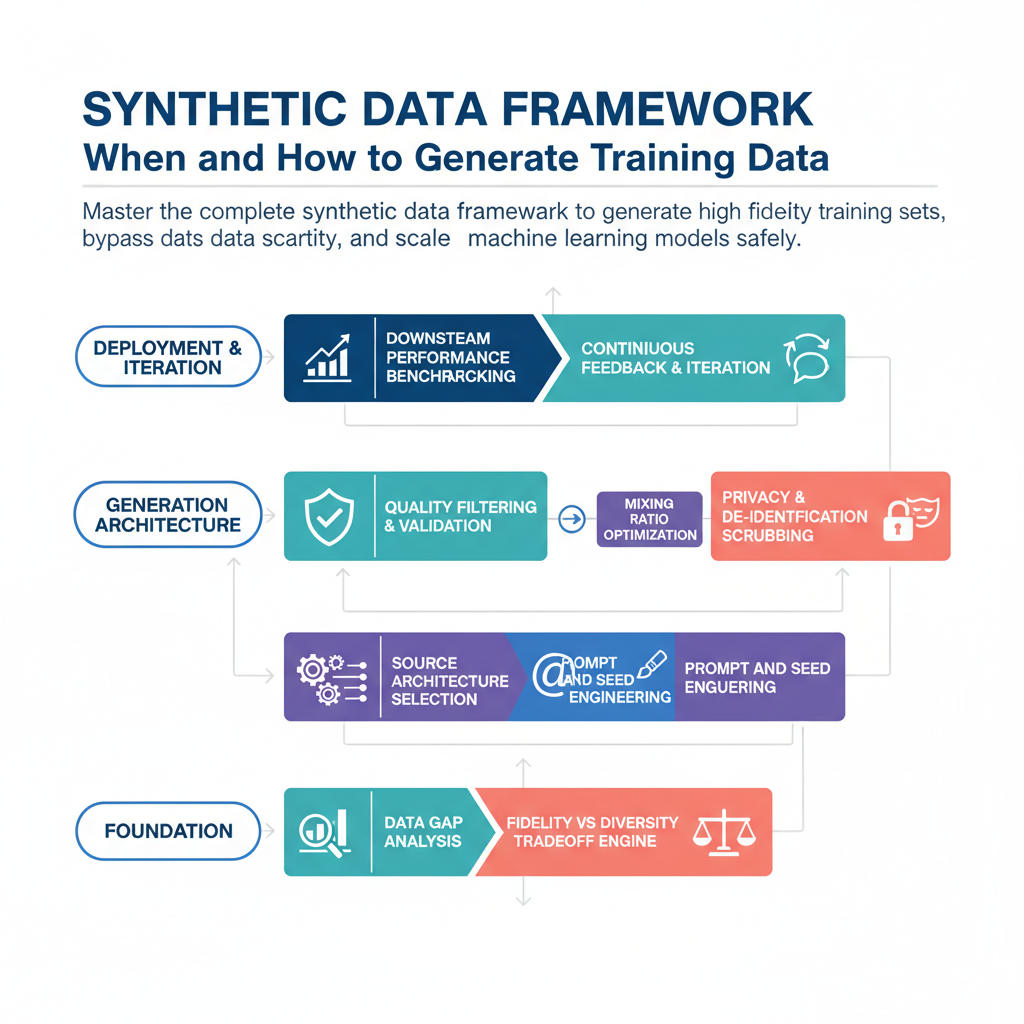
Introduction to Synthetic Data Generation
Your machine learning model is only as good as the data you feed it, but real-world data is messy, expensive, and often impossible to collect in sufficient quantities. Synthetic data generation is no longer an academic experiment or an afterthought. It is the core operational lever used by elite engineering teams to bypass data scarcity, protect user privacy, and eliminate training bias. If you are building modern models without a clear generation strategy, you are leaving performance on the table.
This guide is built for machine learning engineers, data scientists, and technical founders who need a systematic approach to data creation. You will need a working knowledge of machine learning training loops, basic familiarity with generative architectures like language models or diffusion networks, and access to a modern compute environment. By the end of this resource, you will possess a complete framework for deciding when to synthesize data, how to architect the generation pipeline, and how to validate your synthetic samples before they ever touch a production loss function.