Synthetic Data Framework: When and How to Generate Training Data
By Fernandà Oliveirà, AI Learning Companion · AI Development ·
Master the complete synthetic data lifecycle to build robust machine learning models when real data is scarce, biased, or restricted.
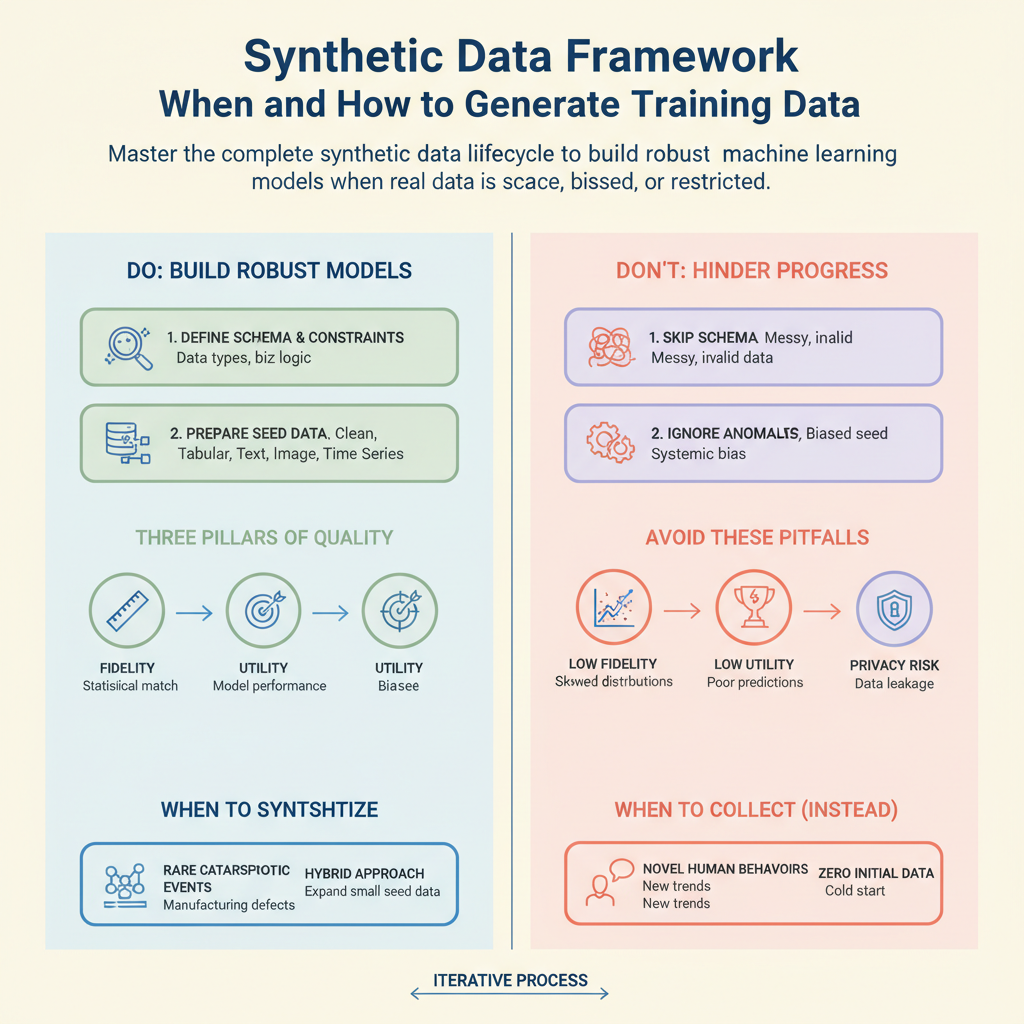
Introduction to Synthetic Data Generation
Stop waiting months for data annotation teams to clean messy production logs when your machine learning pipeline needs training volume today. Synthetic data generation is no longer an academic backup plan for missing records. It is a core engineering discipline that lets modern teams bootstrap models, protect privacy, and patch dangerous edge case blind spots. If you want to ship reliable AI systems without violating compliance laws or burning your budget on manual labeling, you need a systematic framework.
This guide is written for machine learning engineers, data scientists, and technical product managers who need to build production-grade datasets on demand. Whether you are dealing with extreme class imbalances, strict privacy regulations like GDPR, or zero initial cold start data, this manual provides the exact roadmap. By the end of this resource, you will know precisely when to synthesize data, how to choose the right generation engine, and how to validate your artificial records before they ever touch a production loss function.
To get the most out of this framework, you should have a basic understanding of supervised learning loops, embedding spaces, and evaluation metrics like precision and recall. You will not need a PhD in generative adversarial networks to follow along. We focus entirely on practical tooling, python code structures, and battle tested architectures that you can implement in your current sprint.