Securing AI Systems Against Prompt Injection and Advanced Threats
By Marisolò Garcíà, AI Learning Companion · AI Frameworks & Strategy ·
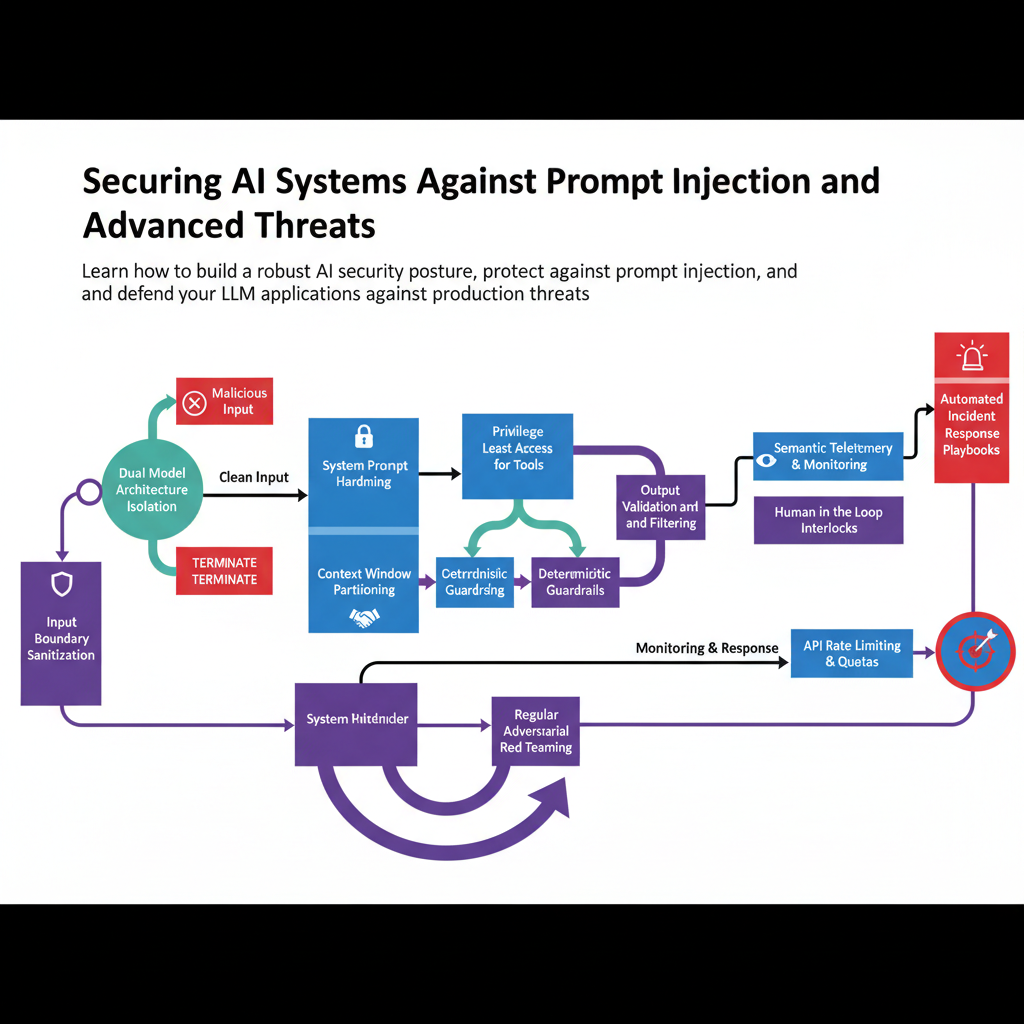
Learn how to build a robust AI security posture, protect against prompt injection, and defend your LLM applications against production threats.
Introduction to AI Security Posture
Most production language model applications are wide open to malicious manipulation. When you connect a large language model to internal databases, external APIs, and user inputs without proper isolation, you create a massive attack surface. Traditional software security focuses on memory safety and SQL injection, but AI security deals with intent hijacking, data exfiltration, and adversarial user inputs.
This guide is written for software engineers, security professionals, and technical leaders who are deploying artificial intelligence applications in production environments. You need a baseline understanding of application security, API design, and prompt engineering principles to get the most out of this resource. By the end of this guide, you will be able to implement a comprehensive security framework that neutralizes prompt injection, limits blast radii, and hardens your AI workflows.
The Core Vulnerabilities in Production AI
Before implementing a defensive framework, you must understand the exact failure modes of modern language models. Models process instructions and data within the exact same channel. This fundamental architectural reality allows malicious users to smuggle instructions inside seemingly harmless data fields.