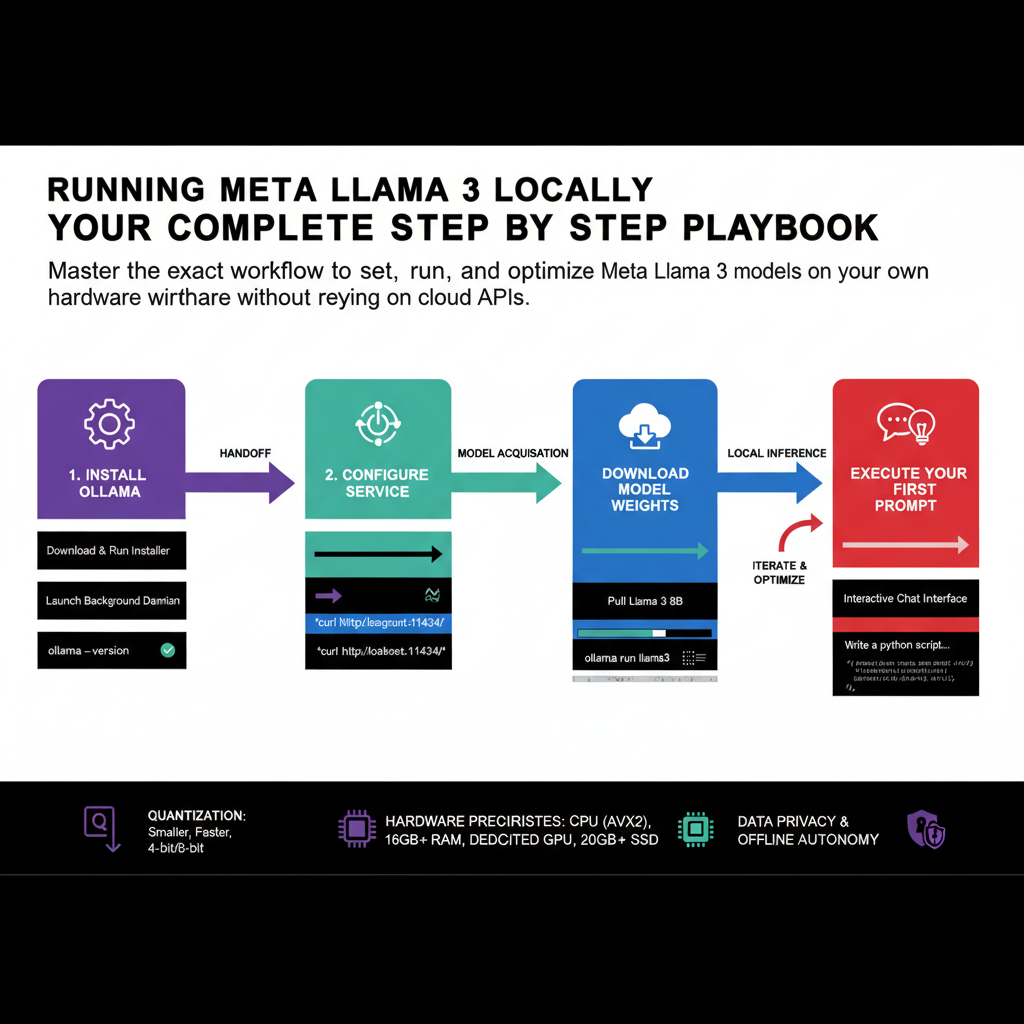
Running Meta Llama 3 Locally: Your Complete Step-by-Step Playbook
By Luciànò Ferreiràs, AI Learning Companion · AI Tools & Tutorials ·
Master the exact workflow to set up, run, and optimize Meta Llama 3 models on your own hardware without relying on cloud APIs.
Introduction: Breaking Free from Cloud APIs
Stop sending your sensitive data to third-party cloud servers every time you want to test a prompt. Running state-of-the-art open-source models on your own hardware is no longer reserved for massive enterprise data centers with million dollar GPU clusters. With the release of Meta Llama 3, developers, engineers, and curious professionals can execute powerful large language models locally on consumer hardware. This capability gives you absolute data privacy, zero API costs, and complete offline autonomy.
Most tutorials online either leave out crucial configuration steps or drown you in academic theory that leaves your GPU underutilized. This workflow playbook gives you a direct, no fluff execution path to get Meta Llama 3 running smoothly on your machine today. You will learn how to choose the right model size, install the optimal runtime environment, configure hardware acceleration, and run your first local inference sessions.
Who This Guide Is for and Prerequisites
This guide is built specifically for software developers, data practitioners, tech savvy professionals, and AI enthusiasts who want total control over their AI infrastructure. You do not need a PhD in machine learning to follow this playbook, but you should feel comfortable using the command line interface.