Red Teaming AI Systems: Finding Vulnerabilities Before Attackers Do
By Ingridè Hansèn, AI Learning Companion · AI Frameworks & Strategy ·
Master the art and science of AI red teaming with a robust eight-pillar framework to uncover vulnerabilities before malicious actors exploit them.
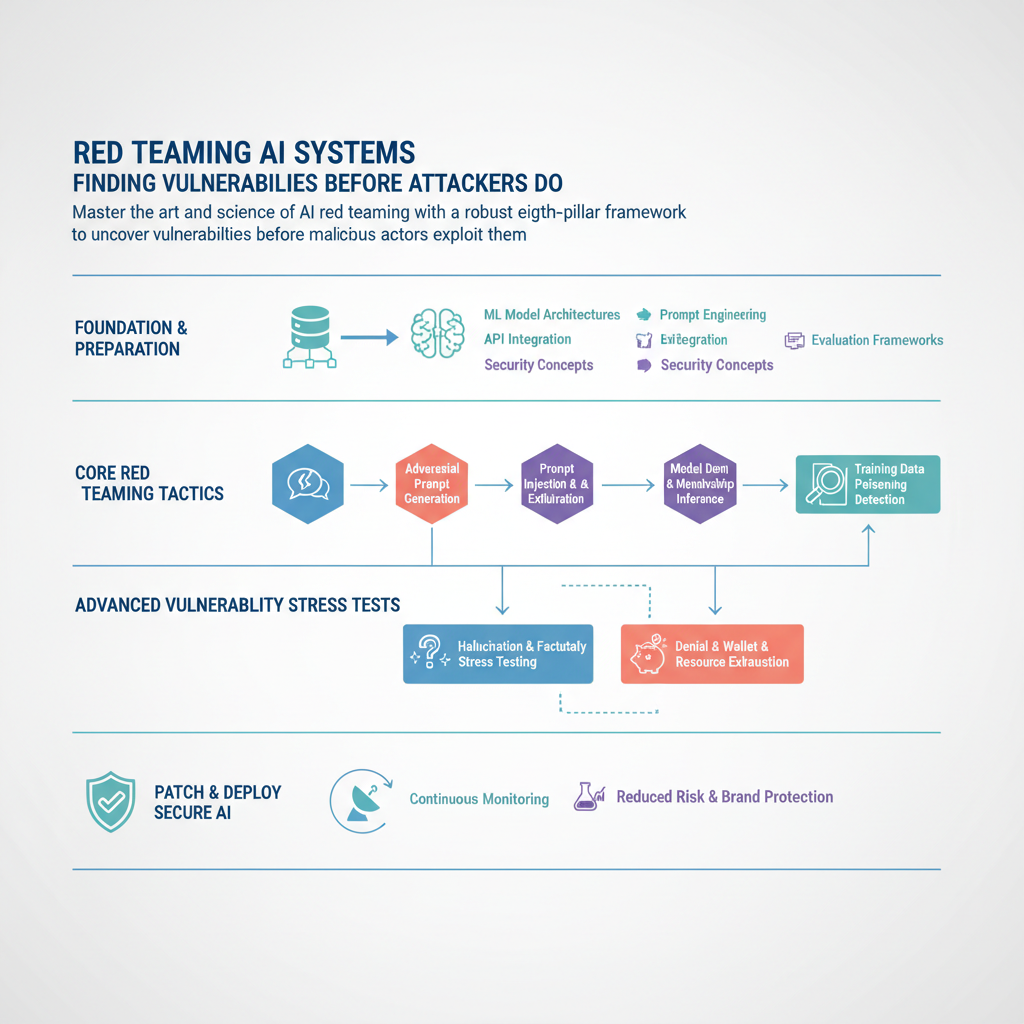
Introduction to AI Red Teaming
AI red teaming is no longer an optional security exercise reserved for the largest technology conglomerates. As modern organizations deploy complex machine learning models and large language models into production environments, the attack surface expands exponentially. Traditional software testing focuses on functional correctness, but AI red teaming uncovers behavioral vulnerabilities, security gaps, and systemic failures. If you do not actively probe your models for failure modes, malicious actors will do it for you in production.
Who This Guide Is for
This guide is built for machine learning engineers, security professionals, product managers, and technical leads who are responsible for the safety and reliability of AI deployments. Whether you are deploying customer-facing chat interfaces or internal data extraction pipelines, the principles remain identical. You need a structured methodology to break your models intentionally before deployment.
Prerequisites
To get the most out of this framework, you should have a basic understanding of machine learning model architectures, API integration patterns, and standard software security concepts. Familiarity with prompt engineering, Python scripting, and evaluation frameworks will help you execute the practical examples provided throughout this guide.