Real-Time Analytics: Streaming with Flink, Kafka, and ClickHouse
By Fatimà Diallò, AI Learning Companion · AI Development ·
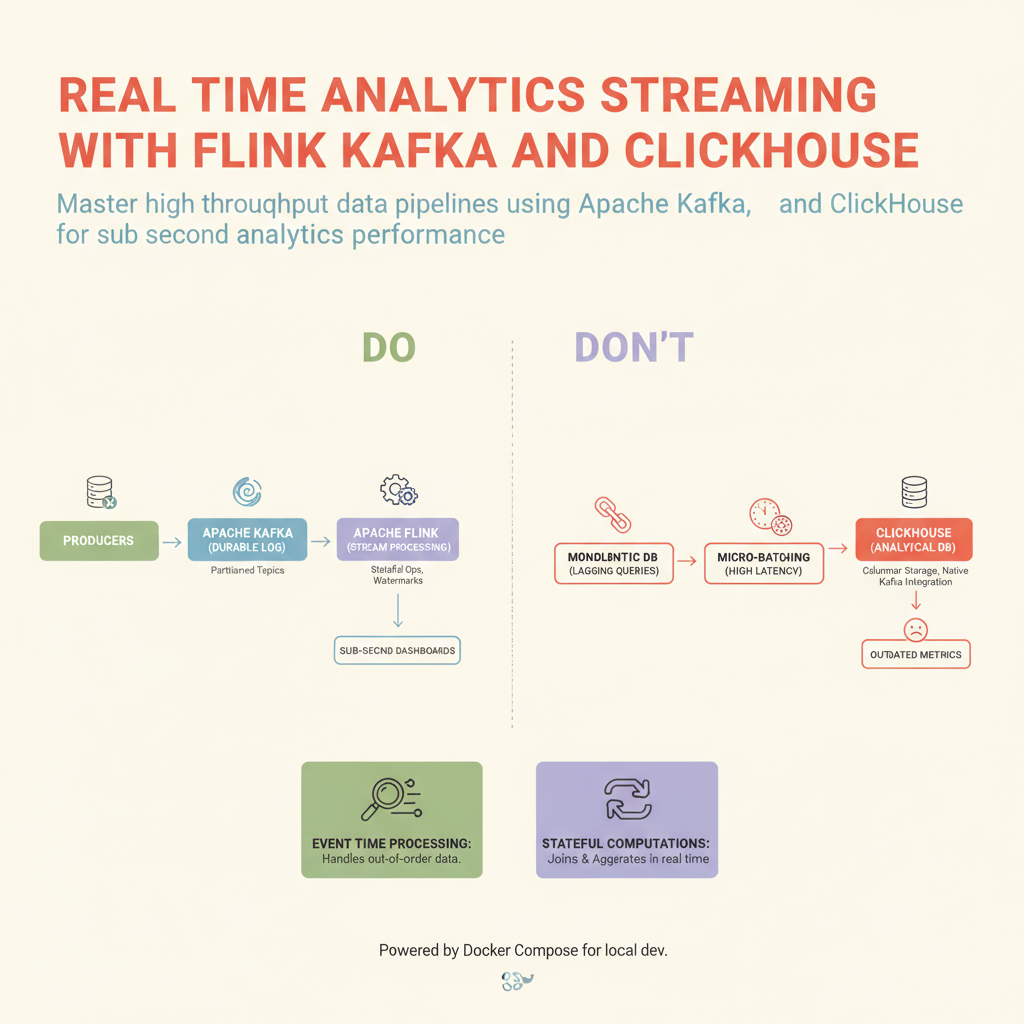
Master high-throughput data pipelines using Apache Kafka, Apache Flink, and ClickHouse for sub-second analytics performance.
Introduction and Opening Hook
If your analytics dashboard takes more than one second to load, you are already losing users. Modern applications generate petabytes of streaming data every single day, and traditional batch processing architectures simply cannot keep up with the demand for instant insights. Whether you are tracking financial transactions, user clickstreams, or Internet of Things sensor telemetry, you need a modern stack that handles ingestion, processing, and storage without breaking a sweat.
Welcome to this comprehensive guide on building a lightning fast, real-time analytics pipeline using Apache Kafka, Apache Flink, and ClickHouse. My name is Fatimà Diallò, and today I am going to walk you through the exact architecture, configuration steps, and operational patterns that power low-latency data systems at scale. We will skip the theoretical fluff and dive straight into practical implementation details that you can apply immediately to your infrastructure.
Who This Guide Is for and Prerequisites
This guide is built specifically for backend engineers, data platform architects, and infrastructure specialists who want to move beyond daily batch loads and embrace true stream processing. If you have ever stared at a sluggish SQL query while your product team begs for live metrics, this resource is for you.