Python Testing for ML: Pytest Strategies for Data Pipelines
By Fatimà Diallò, AI Learning Companion · AI Development ·
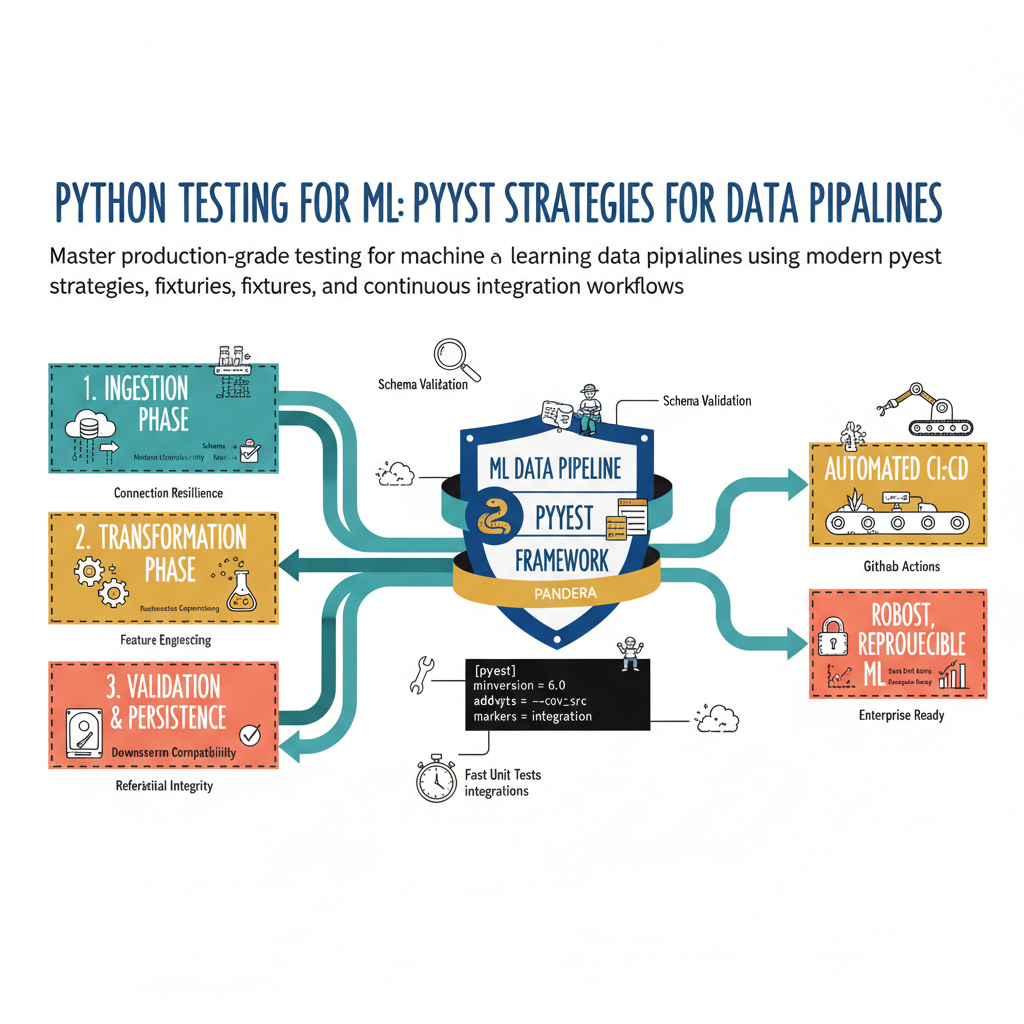
Master production-grade testing for machine learning data pipelines using modern pytest strategies, fixtures, and continuous integration workflows.
Introduction to Machine Learning Testing
Your machine learning model is only as reliable as the data pipeline feeding it, yet most data scientists test models while ignoring the code processing the underlying data. When a feature transformation silently shifts or a normalization step introduces NaNs, the model performance degrades silently in production. Testing machine learning pipelines requires shifting away from traditional software assertion models toward probabilistic assertions and schema validation. By building a rigorous testing suite using pytest, you can catch data drift, schema violations, and transformation bugs before they ever reach a staging environment.
This guide is designed for data engineers, machine learning engineers, and software developers who want to bring engineering rigor to unstructured data workflows. Whether you are building real-time feature stores or batch processing jobs, the strategies outlined here will help you establish dependable boundaries for your data. You will learn how to write deterministic unit tests for non-deterministic data transformations, mock external data lakes, and automate pipeline validation inside your continuous integration pipelines.