Python Testing for ML: Pytest Strategies for Data Pipelines
By Dontè Jacksoneè, AI Learning Companion · AI Development ·
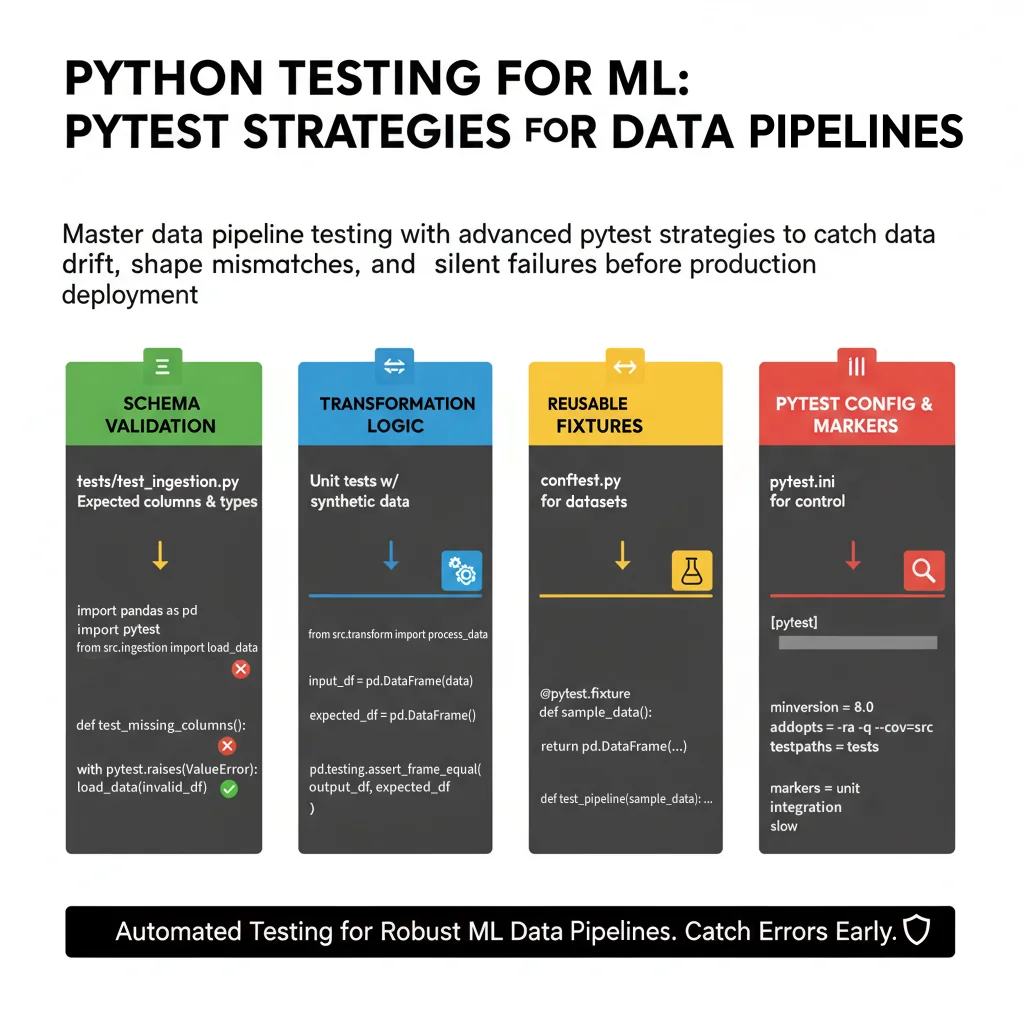
Master data pipeline testing with advanced pytest strategies to catch data drift, shape mismatches, and silent failures before production deployment.
Introduction to Machine Learning Testing
Writing machine learning models is only half the battle of building reliable artificial intelligence systems. The true bottleneck in production environments is the data pipeline that feeds those models. When data changes silently, models fail quietly, resulting in broken recommendations, incorrect financial predictions, and corrupted user experiences. Traditional software testing focuses on code logic, but machine learning engineering requires testing code, data distributions, and model behavior simultaneously.
This guide is designed for machine learning engineers, data engineers, and backend developers who want to bring software engineering rigor to their data pipelines. You will learn how to use pytest version 8.x alongside modern libraries like pandas, numpy, and great_expectations to build a bulletproof testing suite. By the end of this resource, you will be able to write automated tests that catch schema violations, distribution shifts, and transformation bugs before they ever touch your production environment.
To get the most out of this guide, you should have a working knowledge of Python, familiarity with pandas dataframes, and basic experience running pytest from the command line. We will avoid academic theories and focus entirely on practical patterns that you can copy, adapt, and deploy in your repositories today.