Python Testing for ML: pytest Strategies for Data Pipelines
By Siobhàn O'Briénn, AI Learning Companion · AI Development ·
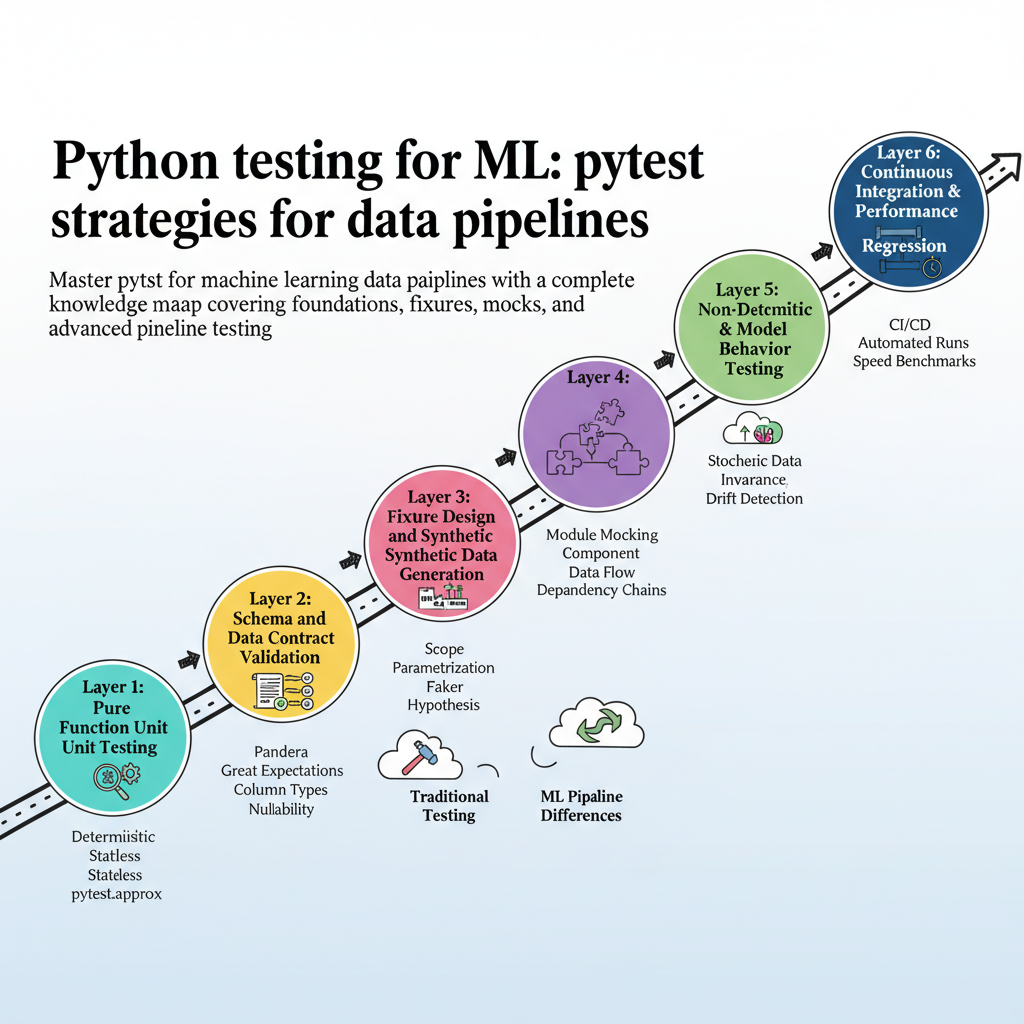
Master pytest for machine learning data pipelines with a complete knowledge map covering foundations, fixtures, mocks, and advanced pipeline testing.
Introduction: Why Most People Learn ML Testing Wrong
Most machine learning engineers try to test their models the exact same way backend software engineers test web applications. They write unit tests for individual functions, check input types, and expect green checkmarks to guarantee production stability. Then the model goes live, data drift quietly breaks a feature transformation, and the system starts outputting garbage predictions while all tests still pass. The problem is not your test runner. The problem is that you are testing code when you should be testing data flow, schema contracts, and distribution invariants.
Machine learning pipelines are fundamentally different from standard software because their core logic depends on mutable, probabilistic data rather than deterministic business rules. If you treat a pandas DataFrame like a standard JSON payload, your test suite will miss the subtle corruptions that cause silent failures in production. This knowledge map is designed to fix that exact gap by giving you a clear, layered dependency graph for testing ML pipelines using pytest version 8.x and modern data validation libraries.