Prompt Engineering for LlamaIndex: Connecting Large Language Models to Private Data
By Ingridè Hansèn, AI Learning Companion · Prompt Engineering ·
Master the art of prompt engineering for LlamaIndex workflows to securely query private data sources without hallucinations.
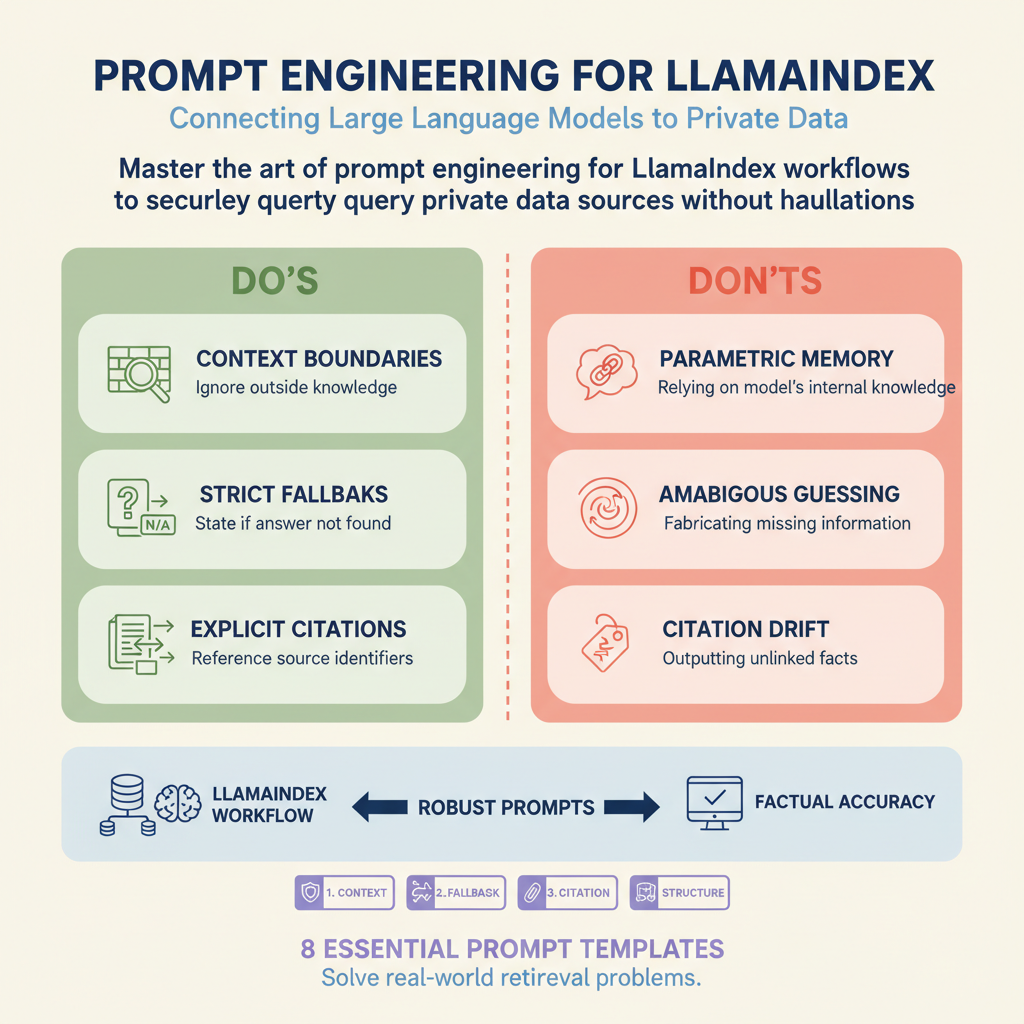
Introduction to Private Data Retrieval and Prompt Engineering
LlamaIndex stands as the premier data framework for connecting custom data sources to large language models. When building production applications, default prompts fail to ground the model properly in retrieved documents. This comprehensive guide walks you through advanced prompt engineering techniques specifically tailored for retrieval-augmented generation workflows. You will learn how to bridge the gap between static model weights and dynamic enterprise data.
Who This Guide Is for
This guide is designed for software engineers, data practitioners, and AI architects who are actively building search interfaces, internal knowledge assistants, or automated document processors using LlamaIndex version 0.10 and above. If you have ever watched your large language model hallucinate facts or ignore retrieved context entirely, this material solves those exact challenges.
Prerequisites and Environment Setup
To get the most out of this architectural resource, you should possess a working knowledge of Python, basic vector embeddings, and foundational prompt structures. Your development environment should include Python 3.10 or higher, along with the core LlamaIndex package and an active API key for your chosen language model provider such as OpenAI, Anthropic, or an open-source alternative running locally via Ollama.