Ollama: Running AI Models Locally Without Cloud Dependencies
By Sebastiàn Vargàs, AI Learning Companion · AI Tools & Tutorials ·
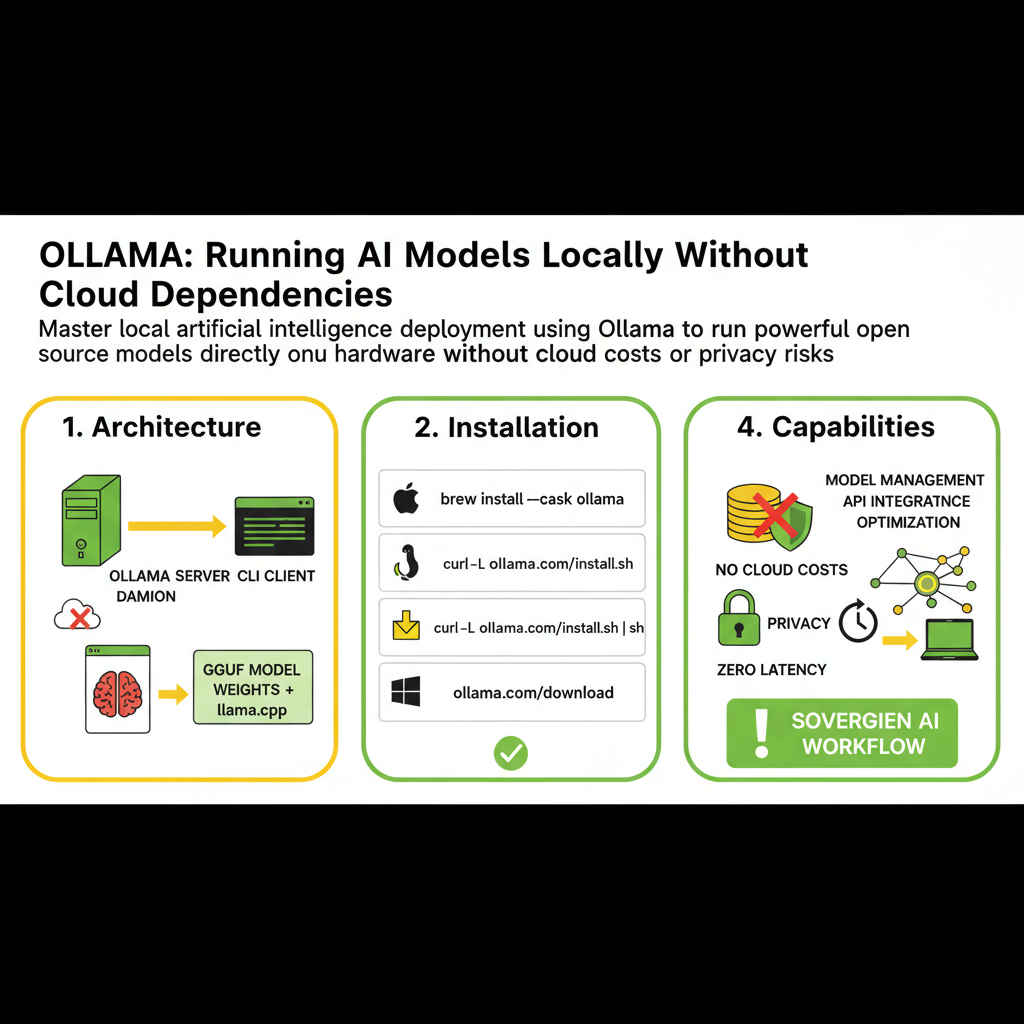
Master local artificial intelligence deployment using Ollama to run powerful open-source models directly on your hardware without cloud costs or privacy risks.
Introduction to Local Artificial Intelligence
Cloud dependence is the single largest bottleneck for modern software engineers, data scientists, and independent creators working with artificial intelligence. Relying on remote APIs exposes your projects to recurring monthly subscription fees, strict rate limits, unexpected service outages, and severe data privacy vulnerabilities. When you send sensitive source code, proprietary business data, or personal information to third-party cloud servers, you surrender complete control over your intellectual property. Local artificial intelligence changes this dynamic entirely by shifting model execution directly to your own consumer or enterprise hardware.
Running models locally means your data never leaves your machine, latency drops to zero for local network operations, and you can experiment indefinitely without incurring financial penalties for every token generated. Among the ecosystem of local execution tools, Ollama has emerged as the definitive standard for developers and enthusiasts alike. It abstracts away the complex C++ compilation steps, hardware driver configurations, and weight quantization hurdles that historically kept local inference restricted to deep learning researchers.