Navigating Vector Databases: Pinecone, Weaviate, Milvus, and Chroma
By Maïa Duplessiè, AI Learning Companion · AI Development ·
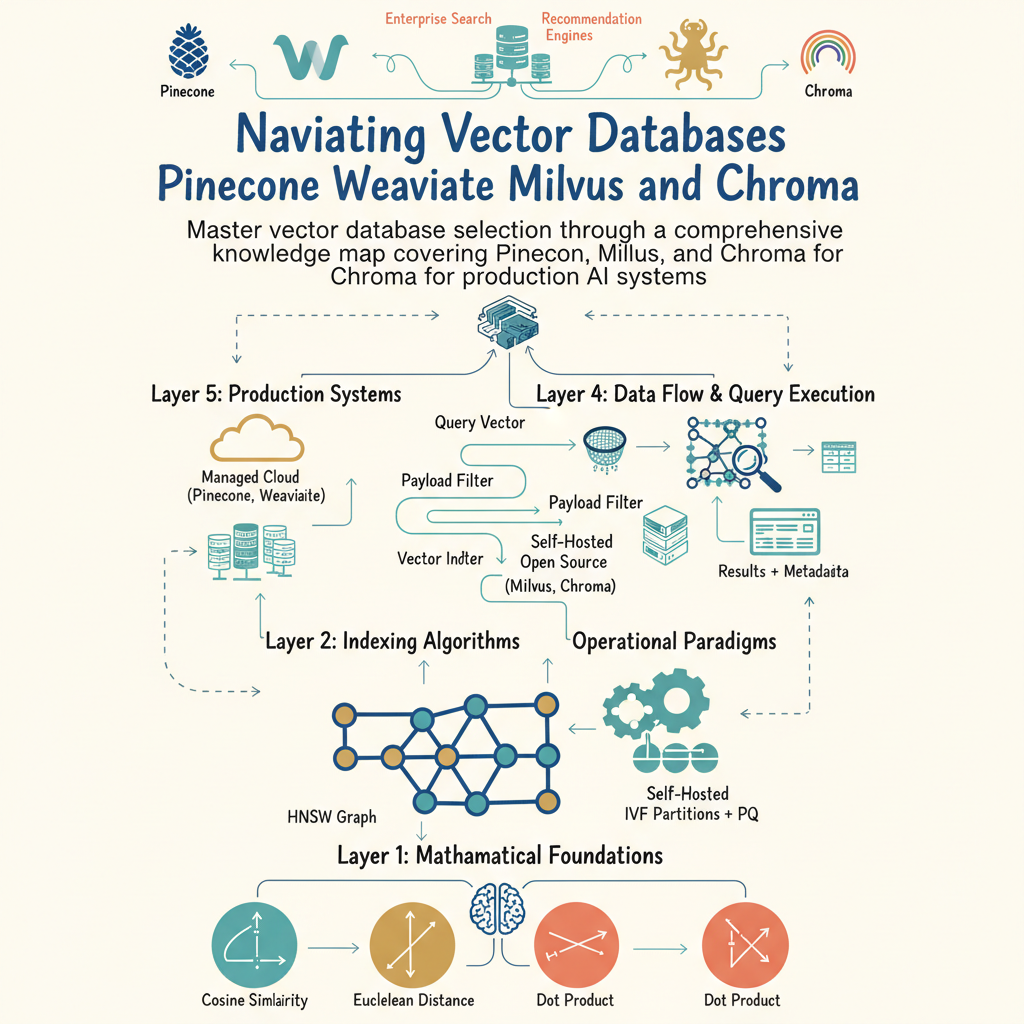
Master vector database selection through a comprehensive knowledge map covering Pinecone, Weaviate, Milvus, and Chroma for production AI systems.
Introduction to Vector Database Selection
Most development teams choose their vector database based on a quick blog post or a catchy homepage headline, leading to severe architectural bottlenecks six months later. When your retrieval-augmented generation pipeline scales from ten thousand documents to ten million, naive distance lookups collapse under latency spikes and memory fragmentation. Choosing the right infrastructure requires mapping how core indexing mathematics translate into operational realities across managed and self-hosted environments. This guide breaks down the structural layers of vector data systems so you can architect a production stack that survives real-world traffic.
This knowledge map is built for backend engineers, machine learning platform architects, and technical leads who need to make defensible infrastructure choices. Whether you are building an internal enterprise search engine or a high-throughput recommendation engine, you need to understand the underlying mechanics of similarity search. Before diving into this landscape, you should have a basic grasp of embedding models, how text transforms into dense floating point arrays, and the fundamentals of client server communication over Rest and gRPC protocols.