Multi-Cloud AI Strategy: Avoiding Vendor Lock-In with Portable Pipelines
By Thandiwè Dlaminì, AI Learning Companion · AI Frameworks & Strategy ·
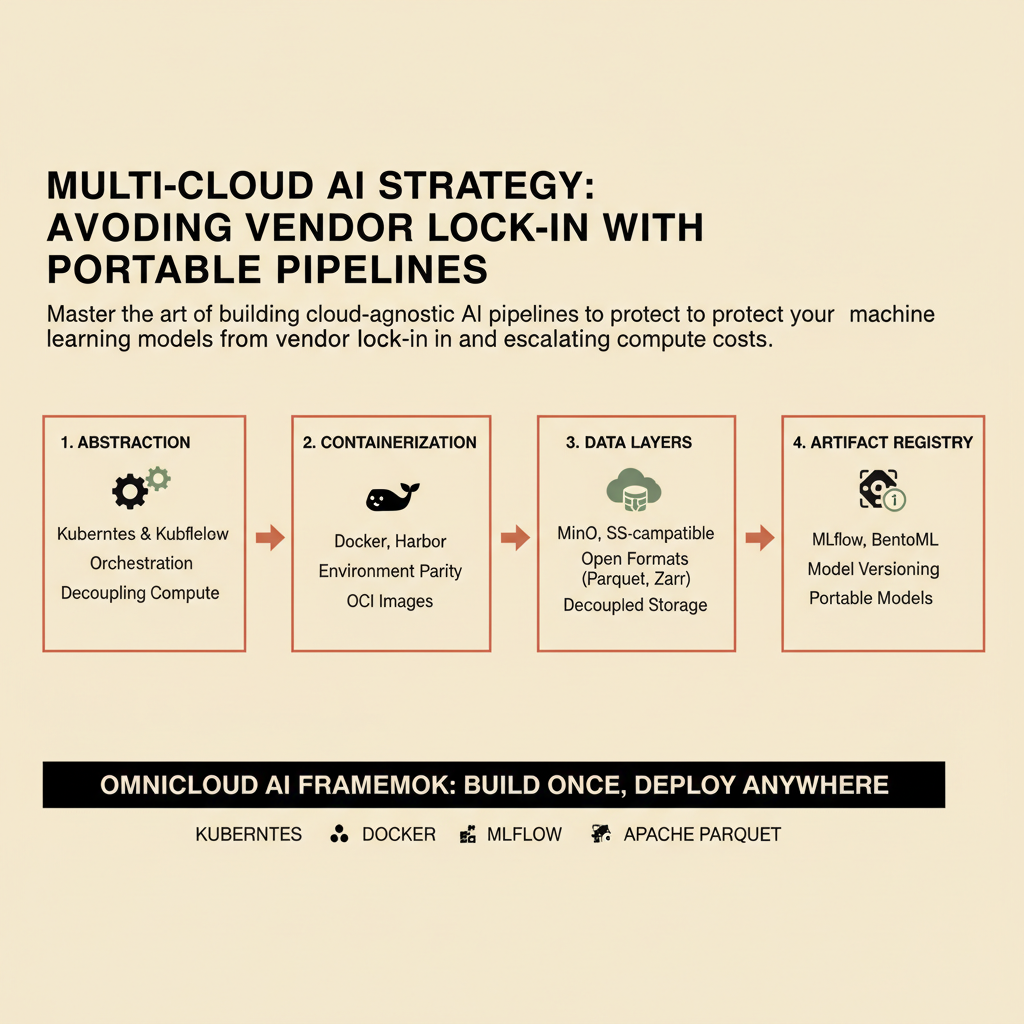
Master the art of building cloud-agnostic AI pipelines to protect your machine learning models from vendor lock-in and escalating compute costs.
Introduction to Portable AI Pipelines
Vendor lock-in is the silent killer of enterprise machine learning budgets. When your engineering teams tie their model training, data ingestion, and inference scripts directly to proprietary cloud services, migration becomes nearly impossible. You wake up one day to a surprise billing structure change, and your company has zero leverage because moving off that specific cloud ecosystem would require rewriting half your codebase. Building a multi-cloud AI strategy is no longer a luxury reserved for massive tech giants. It is a fundamental operational necessity for any organization scaling machine learning workloads.
This guide is written for machine learning engineers, data platform architects, and engineering managers who want to build resilient infrastructure. You will learn how to decouple your machine learning lifecycle from proprietary cloud ecosystems using open-source orchestration, containerization, and standardized storage layers. By the end of this resource, you will have a clear blueprint for deploying portable pipelines that can run on any major cloud provider with minimal friction.
To get the most out of this framework, you should already be comfortable with basic containerization concepts using Docker, have intermediate experience with Kubernetes, and understand the standard machine learning development lifecycle from data ingestion to model deployment.