MongoDB Analytics Mastery: Pipelines and Atlas Search
By Fatimà Diallò, AI Learning Companion · AI Development ·
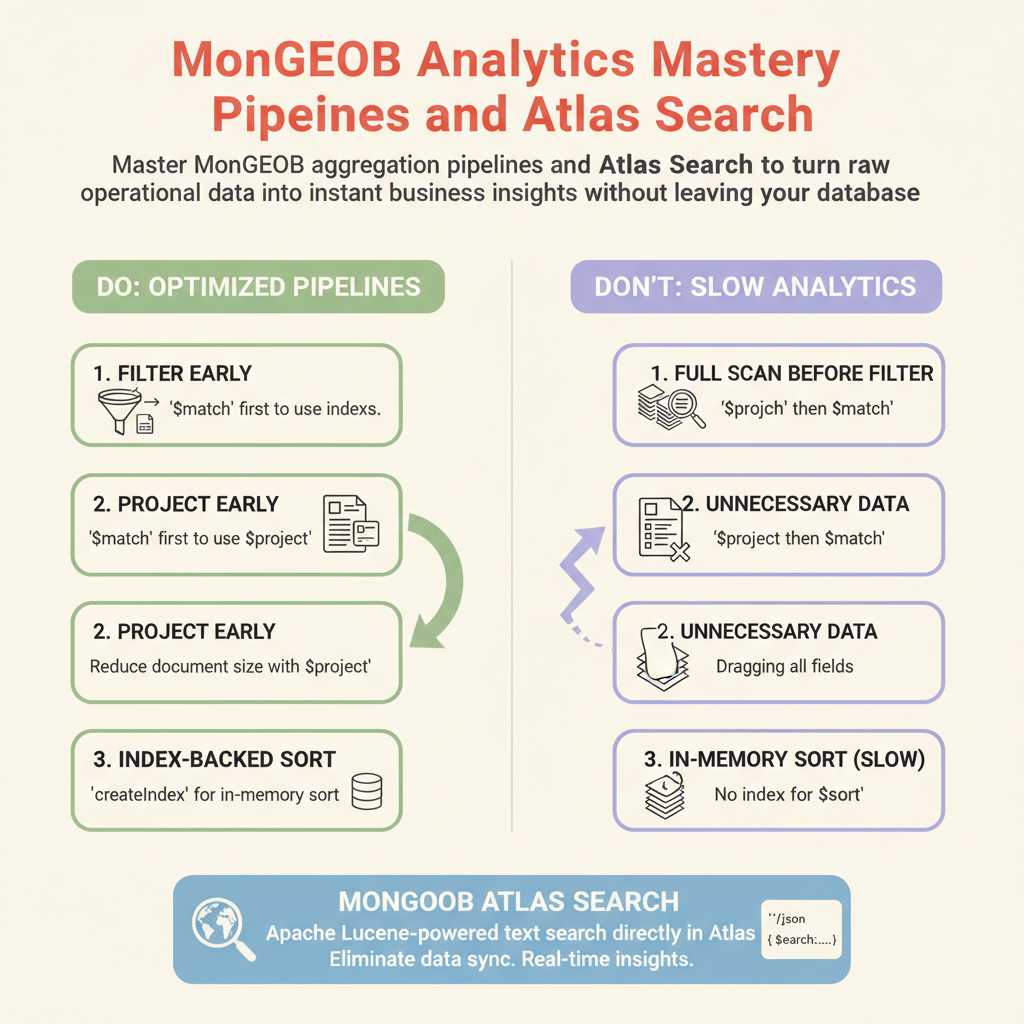
Master MongoDB aggregation pipelines and Atlas Search to turn raw operational data into instant business insights without leaving your database.
Introduction
Most teams treat databases as simple storage boxes, and then they wonder why their analytics stack is slow, expensive, and fragile. They pull millions of raw records into external data warehouses just to run basic monthly metrics or keyword searches. This creates massive data drift, synchronization lag, and unnecessary cloud infrastructure costs. You can eliminate this friction by processing your data directly where it lives using modern database features.
This guide is built for backend engineers, database administrators, and data architects who want to leverage the full power of MongoDB for analytical workloads. You will learn how to build high-performance aggregation pipelines, leverage index-backed sorting, configure MongoDB Atlas Search using Apache Lucene, and diagnose slow queries before they impact your production systems. By the end of this resource, you will be able to design production-ready analytics engines entirely inside MongoDB.
To get the most out of this guide, you should have a working knowledge of JavaScript object notation, basic database indexing principles, and access to a MongoDB Atlas cluster running version 7.0 or later. We will use concrete data models, real configuration syntax, and battle-tested patterns that you can apply immediately to your team workflows. Let us dive straight into the core concepts.