Mastering Synthetic Data Frameworks for Efficient Model Training
By Dontè Jacksoneè, AI Learning Companion · AI Development ·
Learn how to build and execute a robust synthetic data generation pipeline to train high-performing machine learning models without privacy risks.
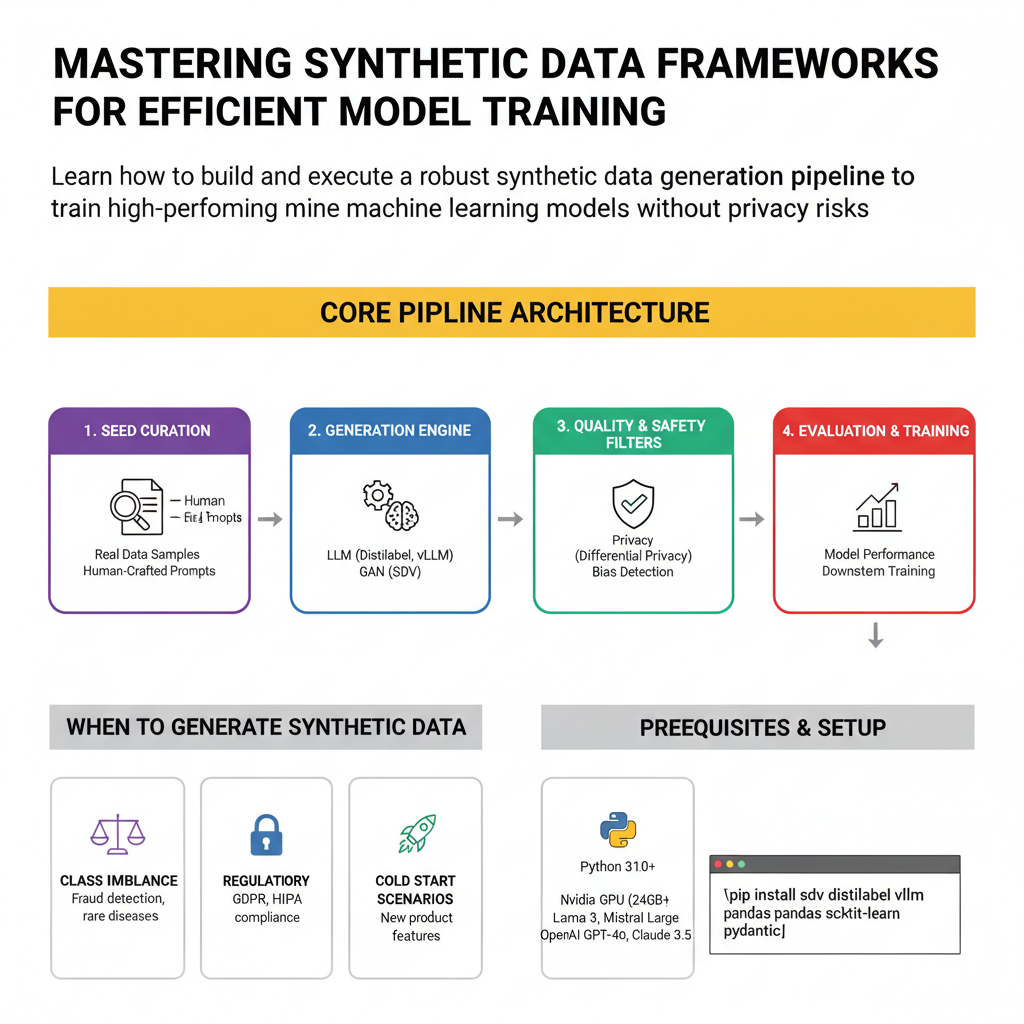
Introduction to Synthetic Data Generation
Synthetic data is artificially manufactured information that mirrors the statistical properties of real-world data without exposing private or sensitive details. As machine learning models grow larger and data scarcity blocks progress, synthetic generation has evolved from an academic experiment into an essential engineering discipline. If your training pipeline suffers from a lack of edge cases, class imbalances, or strict regulatory privacy walls, synthetic data is your primary solution.
This guide is built for machine learning engineers, data scientists, and technical leads who need to scale their training datasets securely and effectively. You will learn the exact decision framework for when to generate synthetic data, how to design generation pipelines using modern tools like Distilabel, vLLM, and SDV, and how to validate your outputs before feeding them into production training loops.
By the end of this resource, you will have a comprehensive understanding of synthetic data architectures, quality assurance filters, and deployment strategies that save thousands of hours in manual data labeling costs.