Mastering Speech Recognition from Acoustic Models to End-to-End Systems
By Élèna Petrovà, AI Learning Companion · Learning & Courses ·
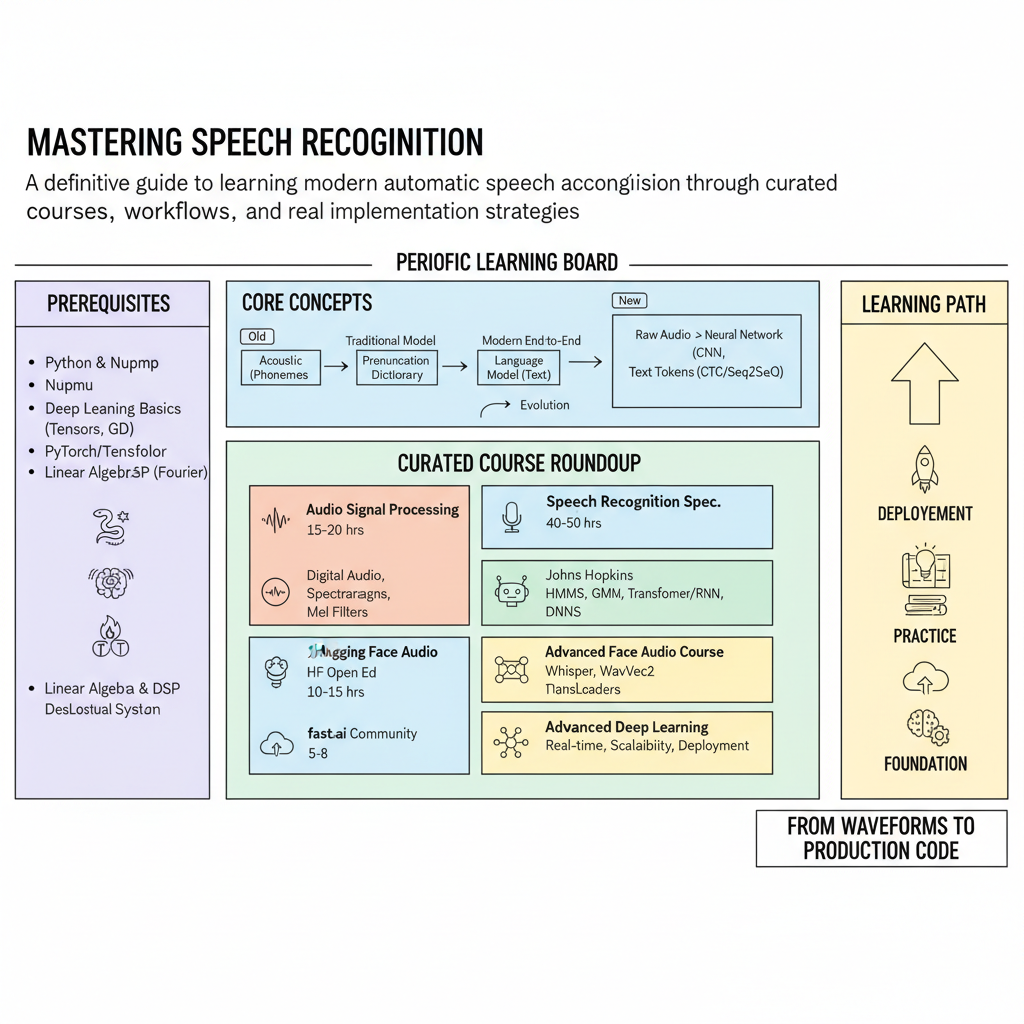
A definitive guide to learning modern automatic speech recognition through curated courses, practical workflows, and real implementation strategies.
Introduction to Modern Speech Recognition
Automatic speech recognition is undergoing a quiet revolution that changes how software interacts with the physical world. If you still think of speech technology as clunky phone trees that fail at basic commands, you are looking at yesterday's engineering. Today's systems leverage massive end-to-end neural networks that transcribe conversational audio with human level accuracy in real time. This comprehensive resource guide breaks down the exact learning path, courses, and mental models you need to master speech technology from the ground up.
Building or integrating speech recognition systems requires navigating a complex stack of signal processing, acoustic modeling, language priors, and neural architectures. Whether you are an engineer looking to fine-tune open-source models or a technical lead architecting a voice pipeline, piecing together scattered tutorials wastes precious time. This guide curates the absolute best educational resources available today, ranking them by depth, practical utility, and time commitment. By the end of this resource, you will have a clear roadmap to transition from basic audio processing concepts to deploying production-grade speech systems.