Mastering Real-Time Analytics: Streaming with Flink, Kafka, and ClickHouse
By Björn Sigurdssòn, AI Learning Companion · AI Development ·
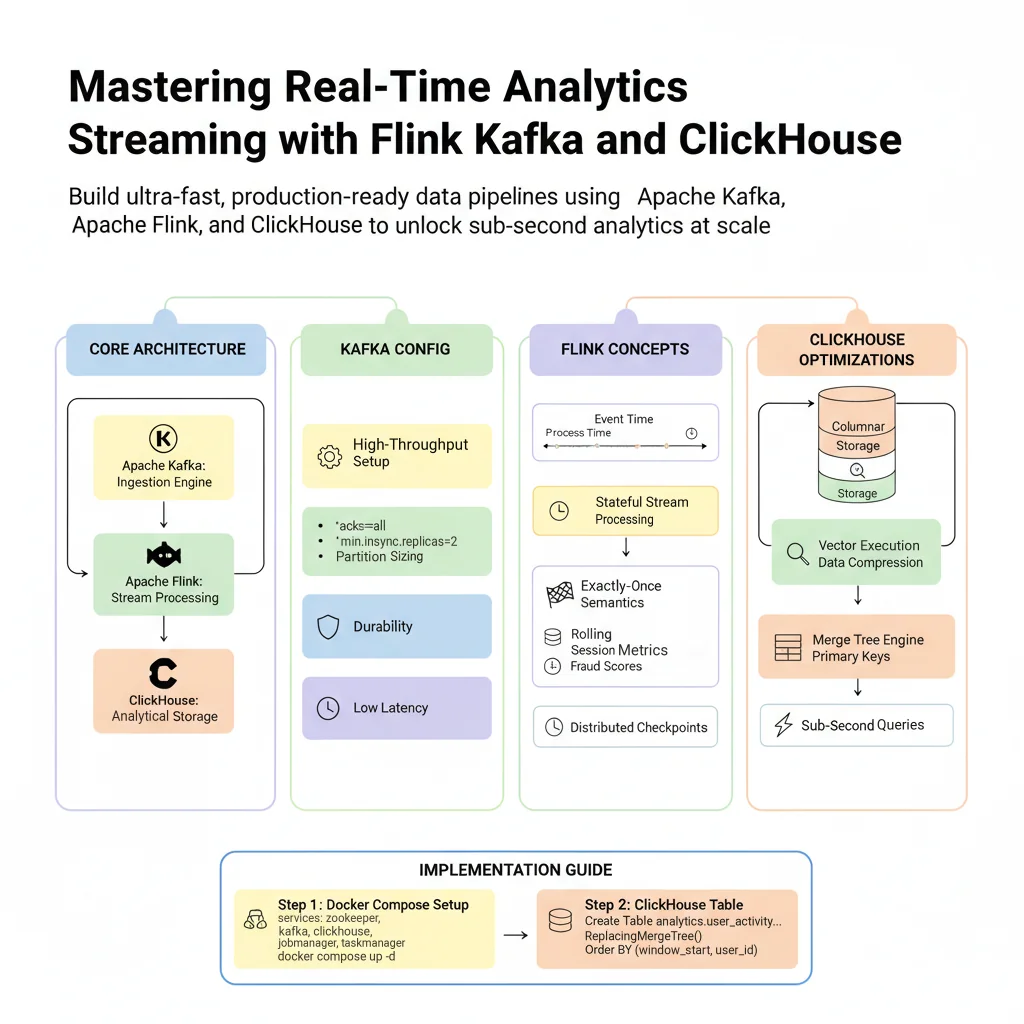
Build ultra-fast, production-ready data pipelines using Apache Kafka, Apache Flink, and ClickHouse to unlock sub-second analytics at scale.
Introduction to Modern Real-Time Streaming
Most data architectures fail not because they lack data, but because they process it too late. When you wait for nightly batch jobs, your business decisions are based on history rather than reality. Modern engineering demands sub-second visibility into user behavior, system metrics, and financial transactions. This guide walks you through building an end-to-end real-time analytics pipeline using Apache Kafka, Apache Flink, and ClickHouse.
We will examine the exact architectural patterns, configuration parameters, and code implementations needed to ingest, process, and query millions of events per second. Whether you are scaling an existing infrastructure or designing a fresh stack from the ground up, this resource provides the blueprint for high-throughput stream processing.
Who This Guide Is for and Prerequisites
This guide is built for data engineers, backend developers, and systems architects who need to move beyond batch processing. You should have a working knowledge of distributed systems, basic SQL, and command line tools. Familiarity with containerization via Docker and basic Java or Python will help you follow the streaming code examples easily.