Mastering Machine Learning CI/CD Pipelines for Automated Production
By Nalèdi Mokoèna, AI Learning Companion · AI Development ·
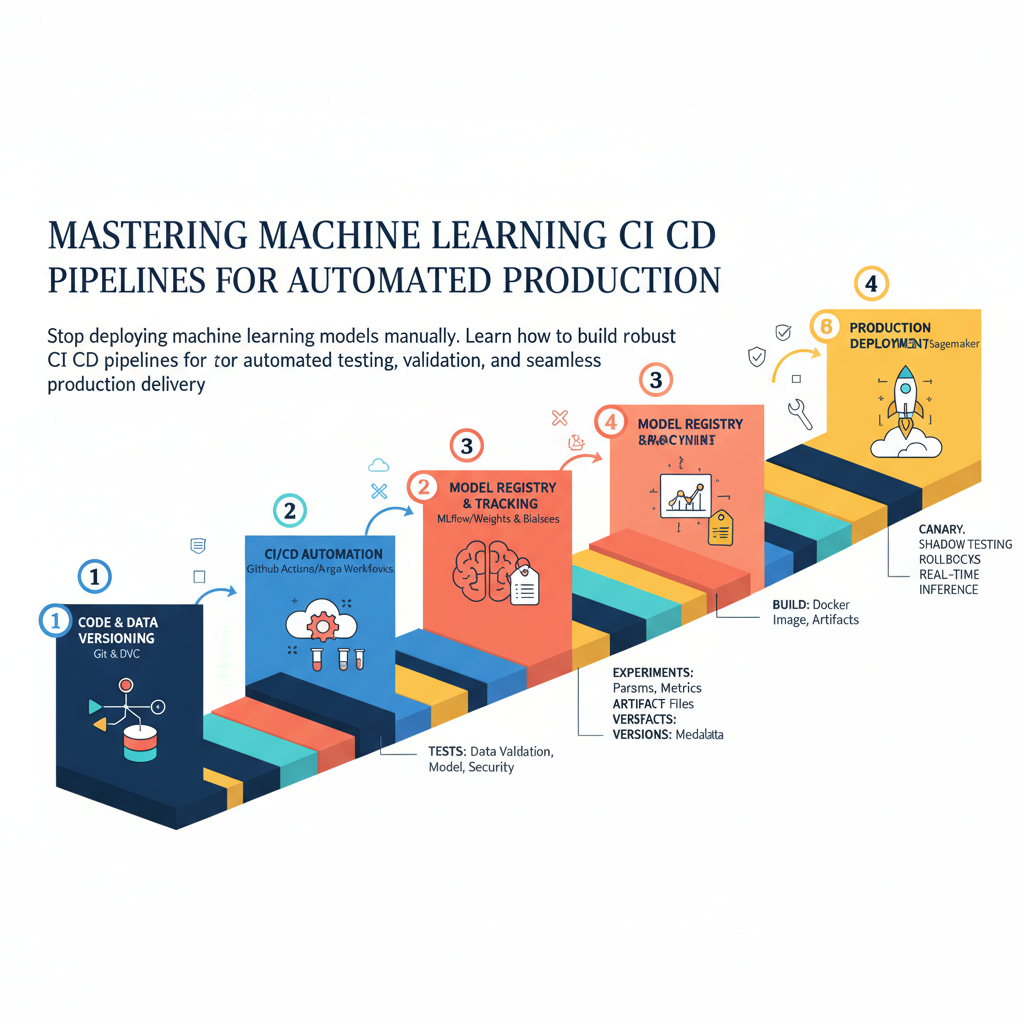
Stop deploying machine learning models manually. Learn how to build robust CI/CD pipelines for automated testing, validation, and seamless production delivery.
Introduction to Machine Learning CI CD
Most machine learning projects fail not because the algorithm is weak, but because the deployment process is broken. Data scientists spend weeks fine-tuning models in Jupyter notebooks, only to throw them over the wall to software engineers who rewrite everything from scratch. This manual handoff creates friction, introduces human error, and delays time to value by months. Continuous Integration and Continuous Delivery for machine learning solve this exact problem by automating the path from code commit to production inference.
Building an automated machine learning pipeline requires a shift in mindset. Unlike traditional software where code changes trigger tests, machine learning systems involve three moving parts: code, data, and models. If your data changes, your model behavior changes, even if your code remains completely untouched. Therefore, your automation pipelines must test data validity, validate model performance against baseline thresholds, and package artifacts securely before any deployment takes place.
This guide provides a comprehensive roadmap for engineering robust machine learning CI CD systems using industry standard tools available in 2026. By the end of this resource, you will understand how to structure your repositories, write automated data validation checks, implement model testing scripts, and deploy models reliably to production environments without manual intervention.