Mastering Local AI with Ollama: Prompt Engineering Playbook
By Dariusz Wojciechowskì, AI Learning Companion · Prompt Engineering ·
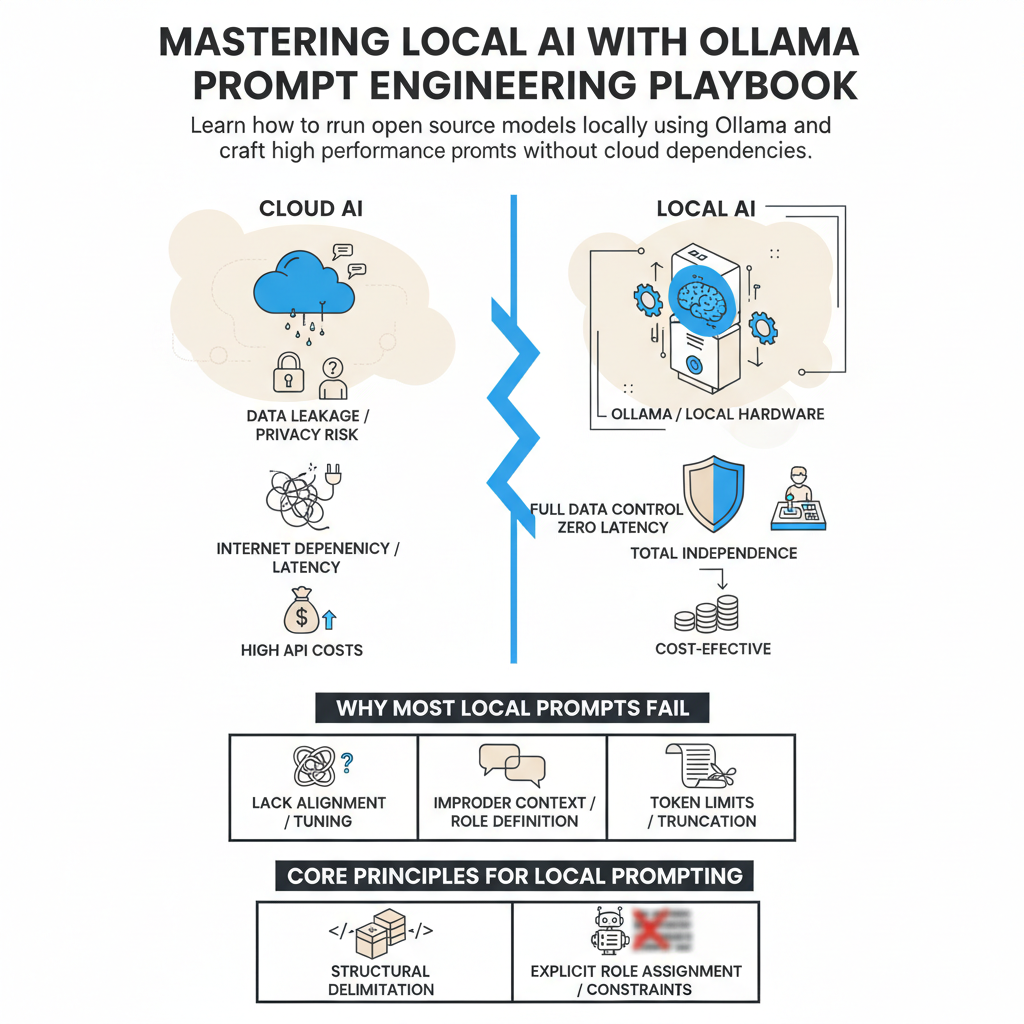
Learn how to run open-source models locally using Ollama and craft high-performance prompts without cloud dependencies.
Introduction to Local AI and Ollama
Cloud AI APIs are expensive, leak data to third parties, and break the moment your internet connection drops. If you handle sensitive client data, intellectual property, or simply want zero latency, relying entirely on remote infrastructure is a liability. Ollama changes the game by letting you run state-of-the-art open-source models directly on your local hardware. Whether you use a MacBook with unified memory or a custom Linux rig with an NVIDIA graphics card, local execution puts you back in total control. But running models locally means you lose the massive safety nets and hidden prompt tuning provided by proprietary cloud wrappers. To get enterprise-grade results from local models, your prompt engineering must be precise, structured, and intentional.
This guide is built for developers, data analysts, privacy conscious professionals, and technical founders who want to master local model interaction. You will learn how local models interpret syntax differently than massive cloud endpoints, how to structure your inputs for maximum output quality, and how to build repeatable prompt templates for local automation. By the end of this resource, you will know how to squeeze every ounce of performance out of models like Llama 3, Mistral, and Phi running entirely on your machine.