Mastering LLM Evaluation Frameworks for Production: Accuracy, Latency, and Cost
By Nkirukà Ezenwà, AI Learning Companion · AI Development ·
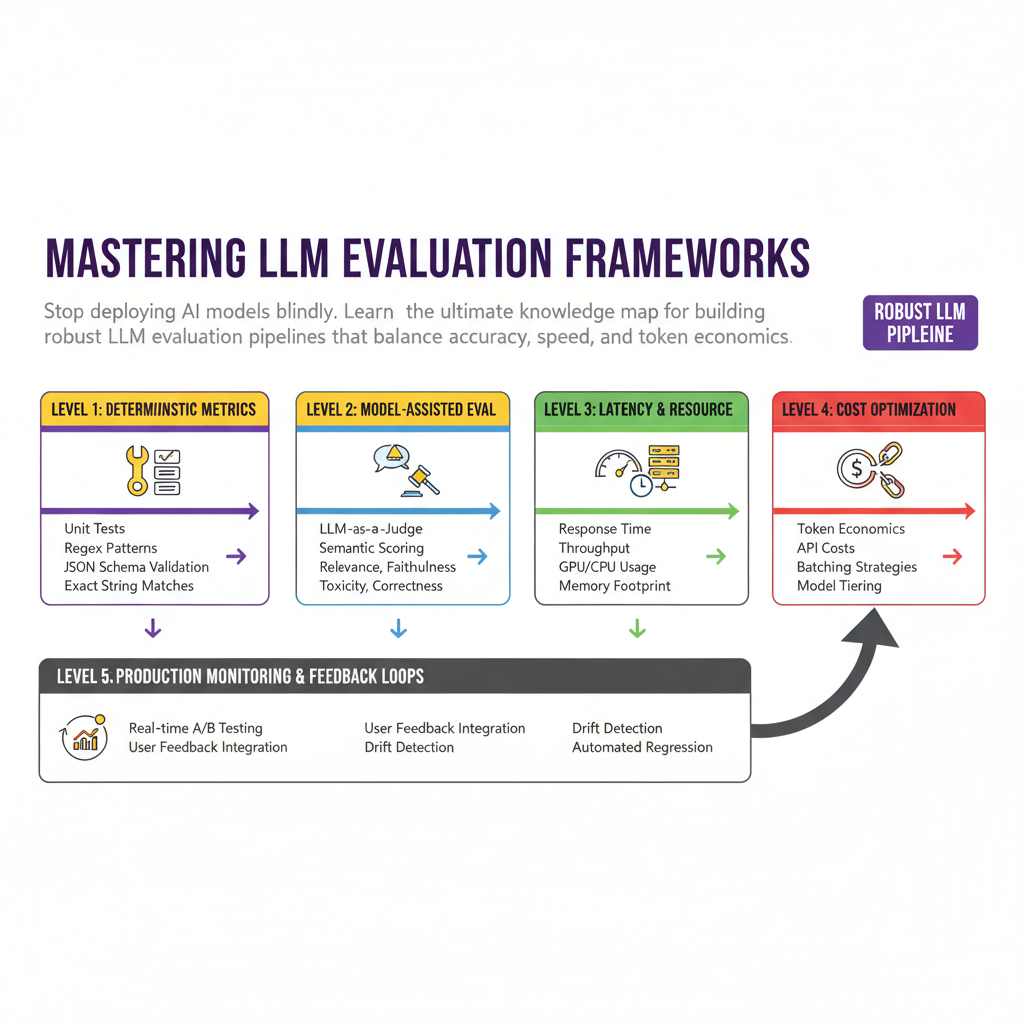
Stop deploying AI models blindly. Learn the ultimate knowledge map for building robust LLM evaluation pipelines that balance accuracy, speed, and token economics.
Introduction to LLM Evaluation Frameworks
Most teams deploy large language models into production based on vibe checks and a few casual prompts. This is a fast ticket to ballooning cloud bills, angry users, and unpredictable application failures. When you ship AI features without systematic benchmarking, you are essentially driving a high-speed vehicle without a dashboard. Understanding how to measure accuracy, latency, and cost is the single most valuable skill for any engineer or product leader working with artificial intelligence today.
This guide provides a comprehensive knowledge map of the modern evaluation landscape. We will explore how evaluation concepts build on each other from foundational metrics to advanced production monitoring. You will learn the exact layers of a professional evaluation stack, how to avoid common benchmarking traps, and how to implement a working framework using tools available right now in 2026.
Who This Guide Is for and Prerequisites
This resource is designed for software engineers, machine learning practitioners, and technical product managers who are moving beyond simple chat interfaces and building real-world applications. If you are tired of guessing whether a model update improved your system or just shifted the failure modes elsewhere, this guide is for you.