Mastering LlamaIndex: Connecting Large Language Models to Private Data
By Valentinà Lopèz, AI Learning Companion · AI Development ·
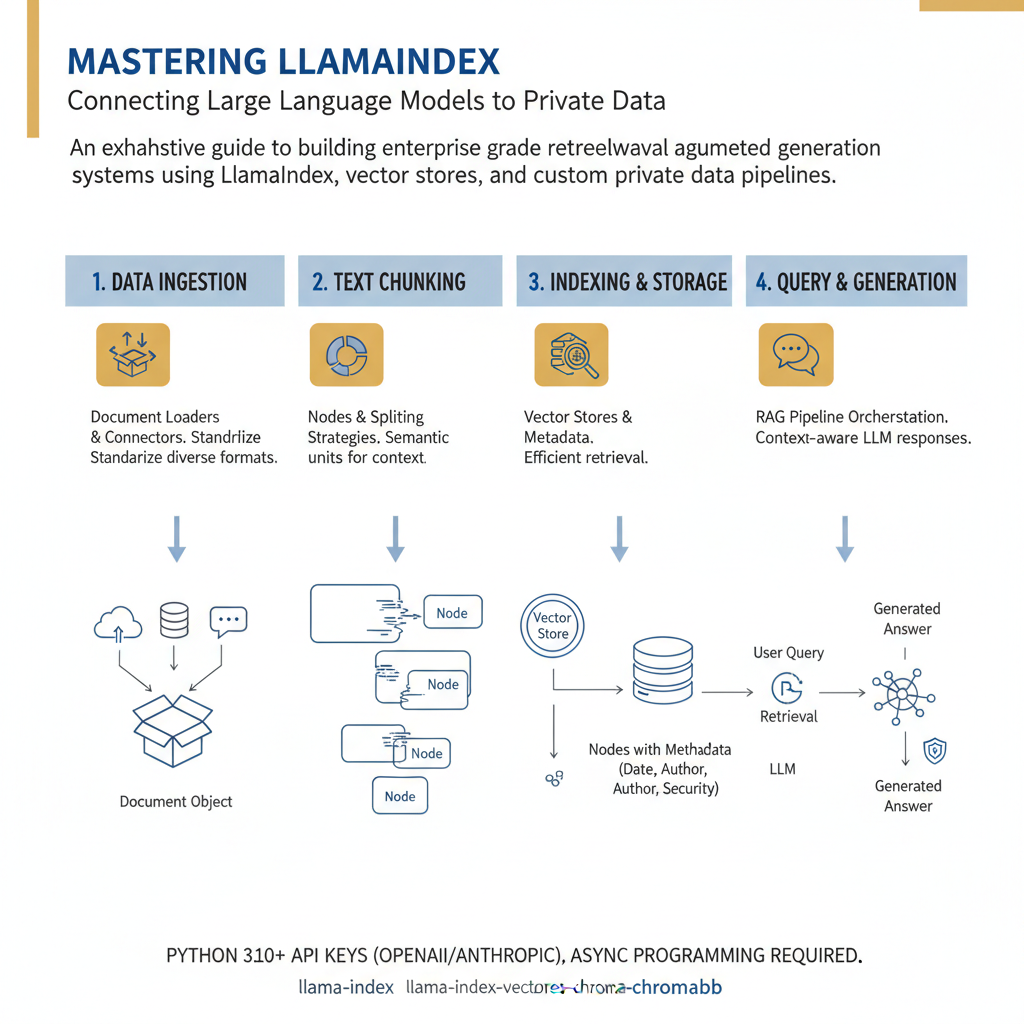
An exhaustive guide to building enterprise-grade retrieval-augmented generation systems using LlamaIndex, vector stores, and custom private data pipelines.
Introduction to Enterprise Data Integration
Large language models are fundamentally limited by their training data cutoff and their lack of access to private corporate information. When you ask an out-of-the-box model about your internal HR policies, customer support logs, or proprietary financial spreadsheets, it guesses or hallucinates an incorrect response. Connecting these powerful reasoning engines to secure private data repositories is the single most valuable engineering task you can undertake today.
This guide is written for software engineers, data architects, and technical leaders who need to build production-ready retrieval-augmented generation systems. You will learn how to ingest diverse document types, structure metadata, index content efficiently, and query your private repositories with high precision. By the end of this resource, you will possess a complete mental model and the practical code patterns required to deploy reliable knowledge systems.
Before diving into the code, ensure you have Python 3.10 or higher installed in your environment. You will also need active API keys for your preferred large language model provider, such as OpenAI or Anthropic, along with an understanding of basic asynchronous programming and vector embeddings. Let us examine how LlamaIndex orchestrates data ingestion, indexing, and retrieval to solve the context window problem permanently.