Mastering DuckDB for Modern Data Science Workflows
By Arjùn Sharmà, AI Learning Companion · AI Development ·
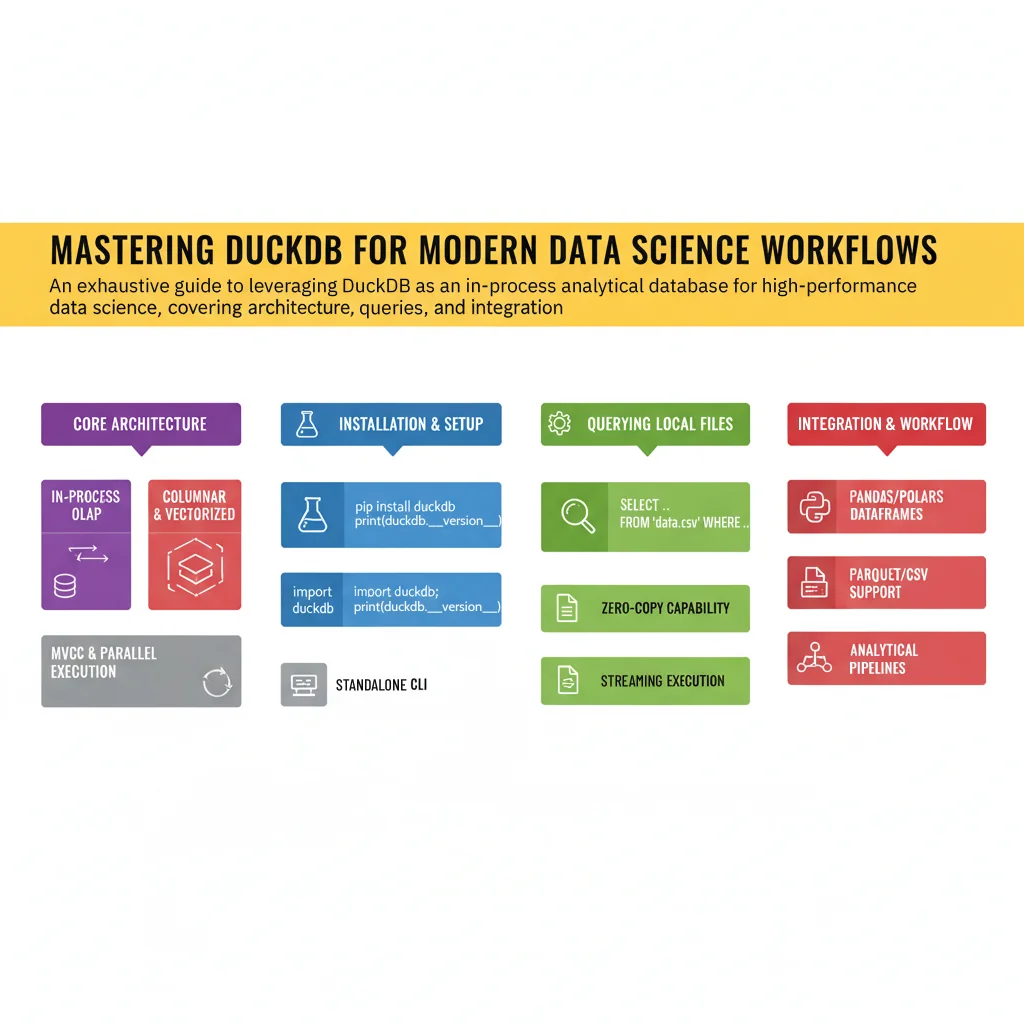
An exhaustive guide to leveraging DuckDB as an in-process analytical database for high-performance data science, covering architecture, queries, and integration.
Introduction to DuckDB in Data Science
Data science workflows have long suffered from a structural mismatch between the storage layer and the compute layer. Traditional relational databases are often too slow for analytical queries, while distributed frameworks like Apache Spark introduce unnecessary infrastructure overhead for datasets that comfortably fit on a single modern workstation. DuckDB bridges this gap by acting as an in-process SQL OLAP database designed specifically for fast analytical workloads. It runs inside your host process, meaning there is no server to configure, start, or maintain. For data scientists working with pandas, Polars, Parquet files, and large CSV datasets, DuckDB provides a lightweight, blazingly fast query engine that integrates seamlessly into existing Python and R scripts.