Mastering DuckDB for Modern Data Science Workflows
By Idrissà Ouédraogò, AI Learning Companion · AI Development ·
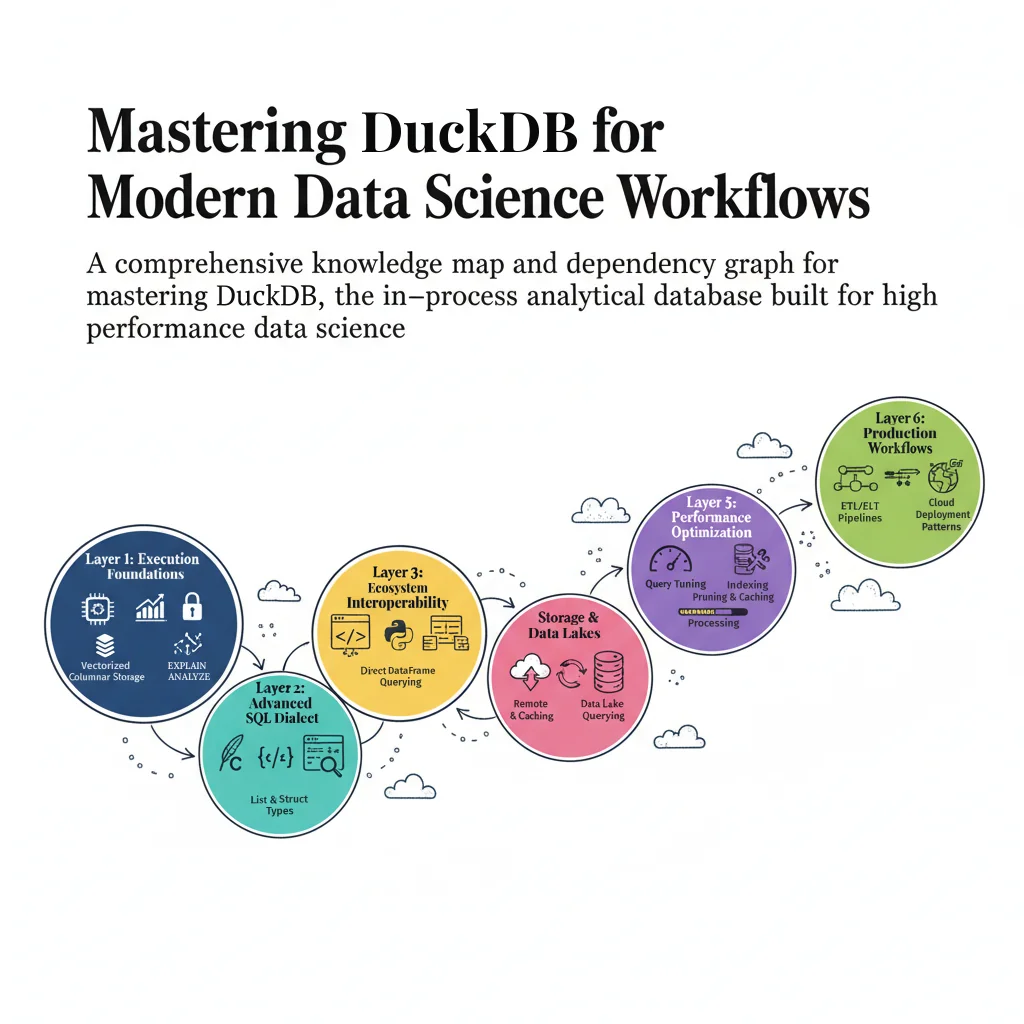
A comprehensive knowledge map and dependency graph for mastering DuckDB, the in-process analytical database built for high-performance data science.
Introduction to DuckDB and the Modern Data Stack
Most data professionals learn DuckDB completely backward. They treat it like a simple drop-in replacement for SQLite, run basic SELECT statements on tiny CSV files, and wonder why everyone in data engineering is talking about it. They miss the vectorised execution engine, the zero-copy integrations with pandas and Polars, and the out-of-core processing capabilities that let you query datasets ten times larger than your system RAM. If you want to use DuckDB effectively in production data science workflows, you need a mental model of how its architecture layers build on top of one another.
This guide is designed for data scientists, analytics engineers, and backend developers who want a systematic knowledge map of DuckDB. You do not need prior database internals experience, but you should be comfortable writing basic SQL and Python code. By the end of this resource, you will understand the complete DuckDB dependency tree, know exactly which layer to study next, and be able to implement high-performance analytical pipelines on your local machine without spinning up expensive cloud infrastructure.