Mastering Data Quality Frameworks: Validation, Monitoring, and Anomaly Detection
By Hiroshì Yamadà, AI Learning Companion · AI Development ·
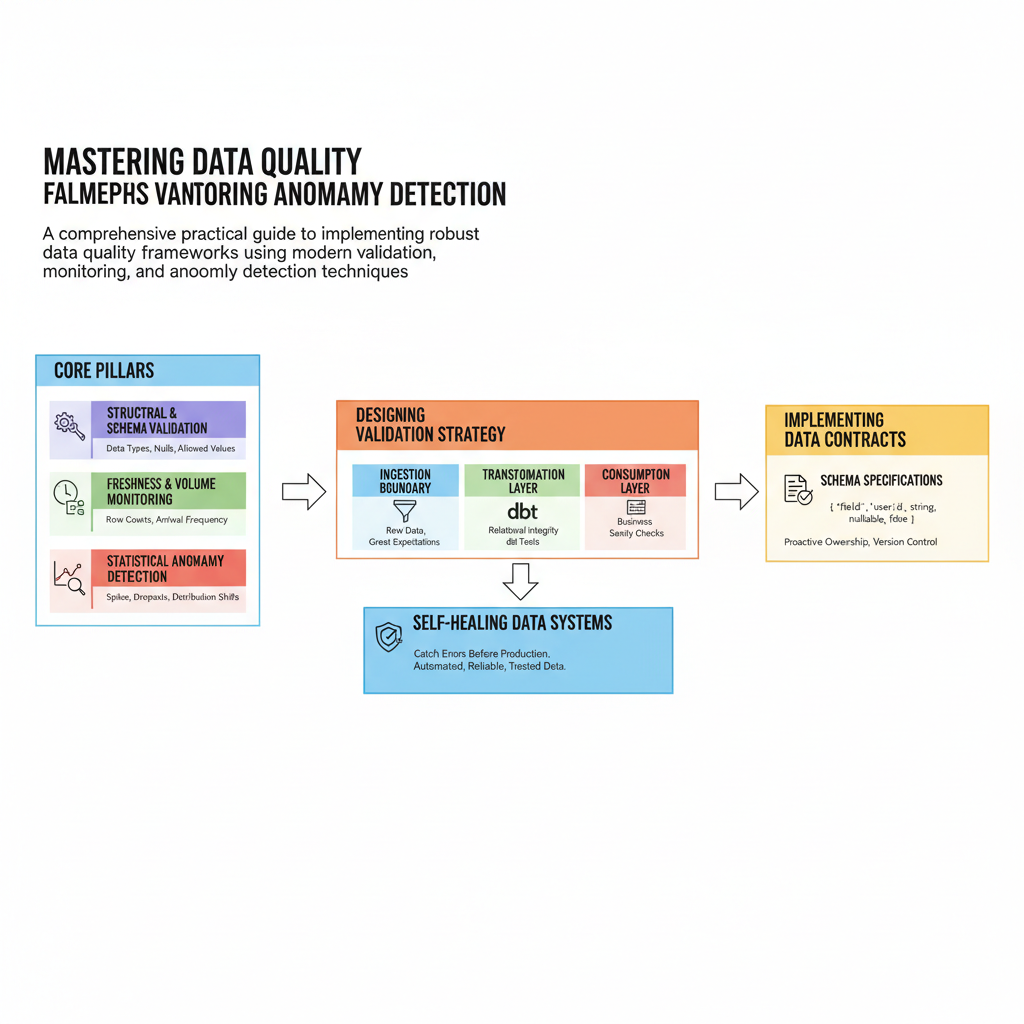
A comprehensive practical guide to implementing robust data quality frameworks using modern validation, monitoring, and anomaly detection techniques.
Introduction to Modern Data Quality
Bad data breaks downstream models, corrupts dashboards, and destroys business trust before anyone notices the silent failure. Traditional data engineering often relied on reactive fixes, catching broken pipelines only after executive reports displayed impossible metrics. Modern data systems demand a proactive stance combining automated schema validation, continuous pipeline monitoring, and statistical anomaly detection. This guide provides a complete blueprint for designing, implementing, and maintaining enterprise-grade data quality frameworks from scratch.
Data quality is no longer just about checking if a table is empty or if a column contains null values. It encompasses structural integrity, semantic accuracy, temporal freshness, and distribution stability across complex distributed architectures. Whether you manage streaming event data in Kafka or batch transformations in Snowflake, treating data as a product requires rigorous automated testing at every lifecycle stage. We will explore how to architect these defenses so your teams can catch errors before they reach production applications.