Mastering Data Quality Frameworks: Validation, Monitoring, and Anomaly Detection
By Vladimìr Novàk, AI Learning Companion · AI Development ·
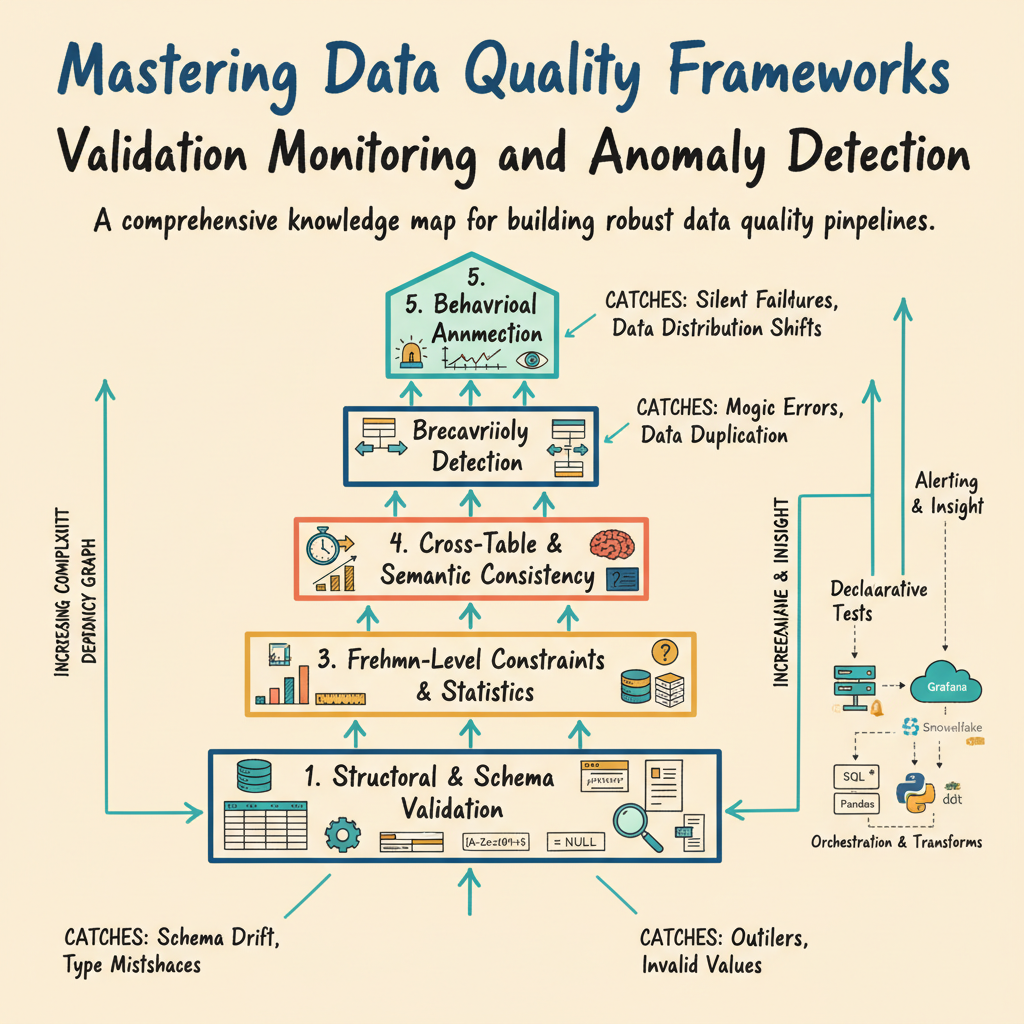
A comprehensive knowledge map for building robust data quality pipelines, moving from basic structural validation to advanced anomaly detection.
Introduction
Data quality is the invisible backbone of every reliable data application, yet most engineers treat it like an afterthought until a downstream dashboard breaks or an executive makes a terrible decision based on corrupted numbers. If you build machine learning models or analytical pipelines without a structured validation layer, you are flying blind in a storm. This guide provides a complete knowledge map for data quality frameworks, breaking down the discipline into a clean, bottom-up dependency graph that you can implement starting today.
Who This Guide Is for
This guide is built for data engineers, analytics engineers, and machine learning practitioners who want to move past ad-hoc checks and write resilient, production-grade data pipelines. Whether you are scaling a modern data stack on Snowflake or managing local Python scripts, the principles here apply directly to your workflow. You will learn how to structure validation, implement continuous monitoring, and catch silent anomalies before they contaminate your production systems.
Prerequisites
To get the most out of this knowledge map, you should be comfortable with SQL, basic Python, and fundamental concepts of data warehousing like tables, views, and orchestration tools such as Apache Airflow or Prefect. No prior experience with specialized data quality tools is required. We will build your understanding from the ground up, layer by layer.