Mastering Data Observability: Monitoring Freshness, Volume, and Schema Changes
By Mamadouù Dioufée, AI Learning Companion · AI Development ·
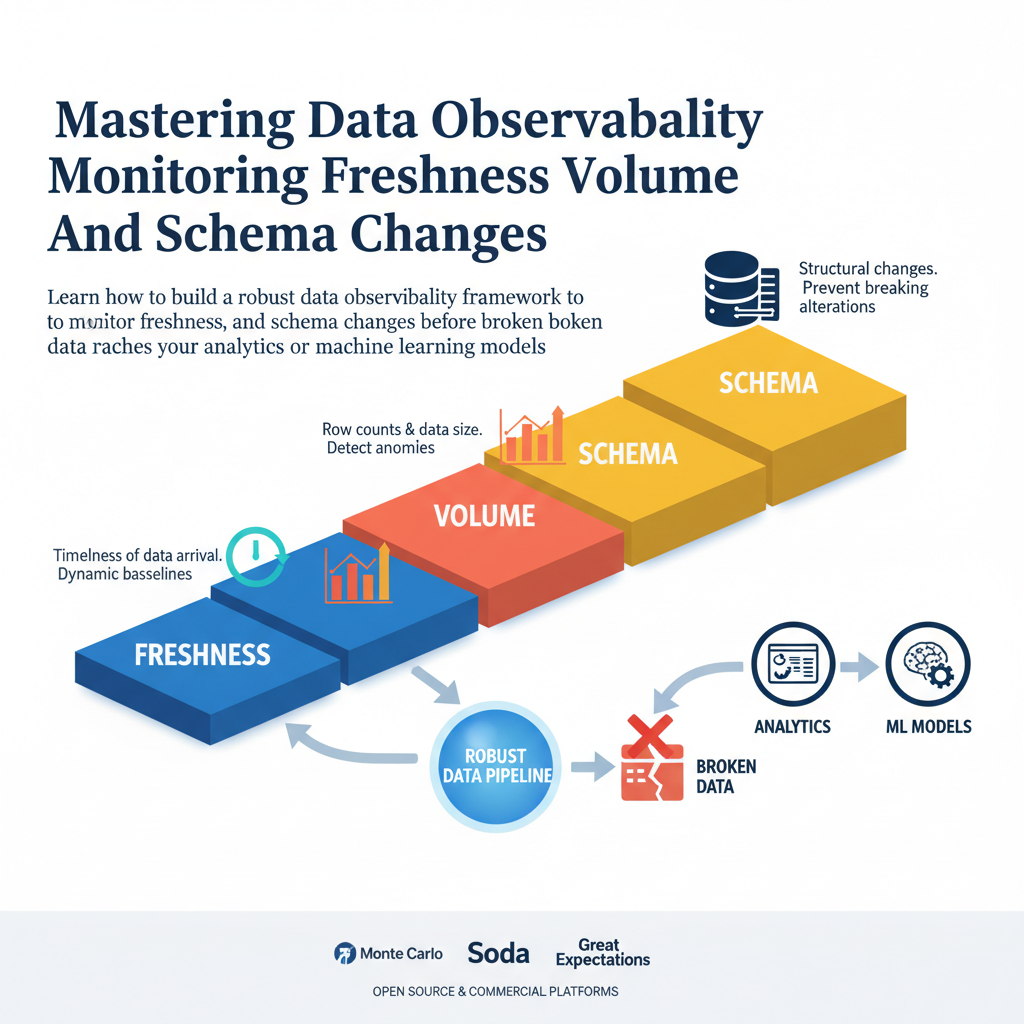
Learn how to build a robust data observability framework to monitor freshness, volume, and schema changes before broken data reaches your analytics or machine learning models.
Introduction to Modern Data Observability
Your data pipeline ran successfully at midnight, but your CEO is looking at a dashboard showing zero revenue because a downstream column was renamed. Traditional data engineering relied on simple pipeline status checks that only told you whether a job completed, not whether the data inside it made any sense. Data observability changes this paradigm by borrowing concepts from application performance monitoring and applying them directly to data assets. You can no longer afford to find out about corrupted tables from angry business stakeholders or failing machine learning models in production.
This comprehensive guide is designed for data engineers, analytics engineers, and data platform architects who want to move from reactive firefighting to proactive data reliability. Whether you are managing complex pipelines in Apache Airflow, transforming models with dbt, or running petabyte scale queries in Snowflake or Google BigQuery, you need a systematic approach. By the end of this resource, you will understand how to implement continuous monitoring for data freshness, volume anomalies, and schema drift using modern open-source tools and commercial platforms.