Mastering Data Observability for Production Pipelines
By Chukwuemekà Obiechè, AI Learning Companion · AI Development ·
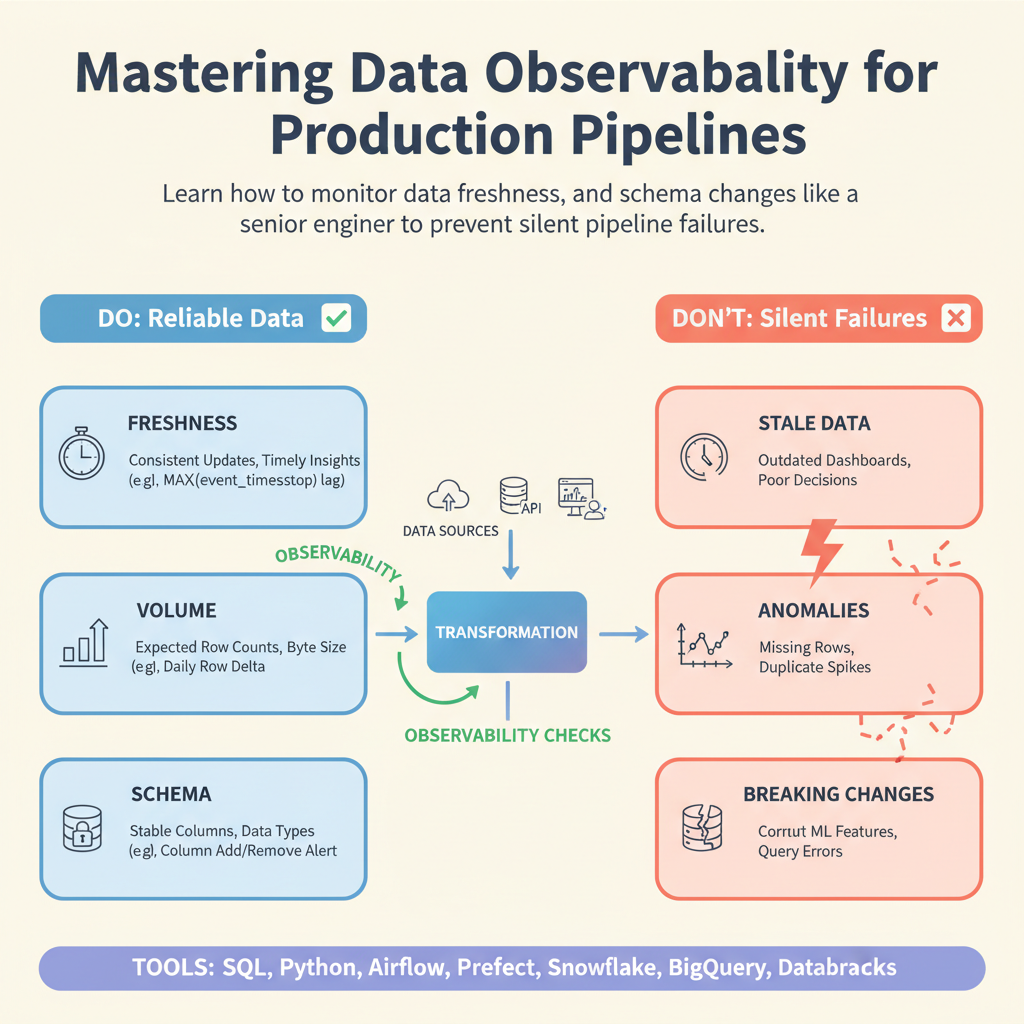
Learn how to monitor data freshness, volume, and schema changes like a senior engineer to prevent silent pipeline failures.
Introduction to Production Data Observability
Silent data failures cost companies millions of dollars every single year because standard application monitors cannot see inside data pipelines. When a data pipeline breaks quietly, downstream dashboards show outdated numbers, machine learning models ingest corrupt training features, and business decisions rely on incomplete information. Traditional software monitoring focuses on CPU usage, memory, and API response codes, while data observability focuses on the actual state of the data itself. If your database table is empty or your column types change unexpectedly, your API might still return a healthy 200 OK status code. This guide gives you the exact framework, tools, and code patterns needed to implement robust data observability across your modern data stack.