Mastering Data Governance: Metadata, Lineage, and Access Control
By Gbenga Akingbulere, AI Learning Companion · AI Frameworks & Strategy ·
A comprehensive reference guide for building robust data governance frameworks, managing metadata catalogs, mapping pipeline lineage, and enforcing granular access control.
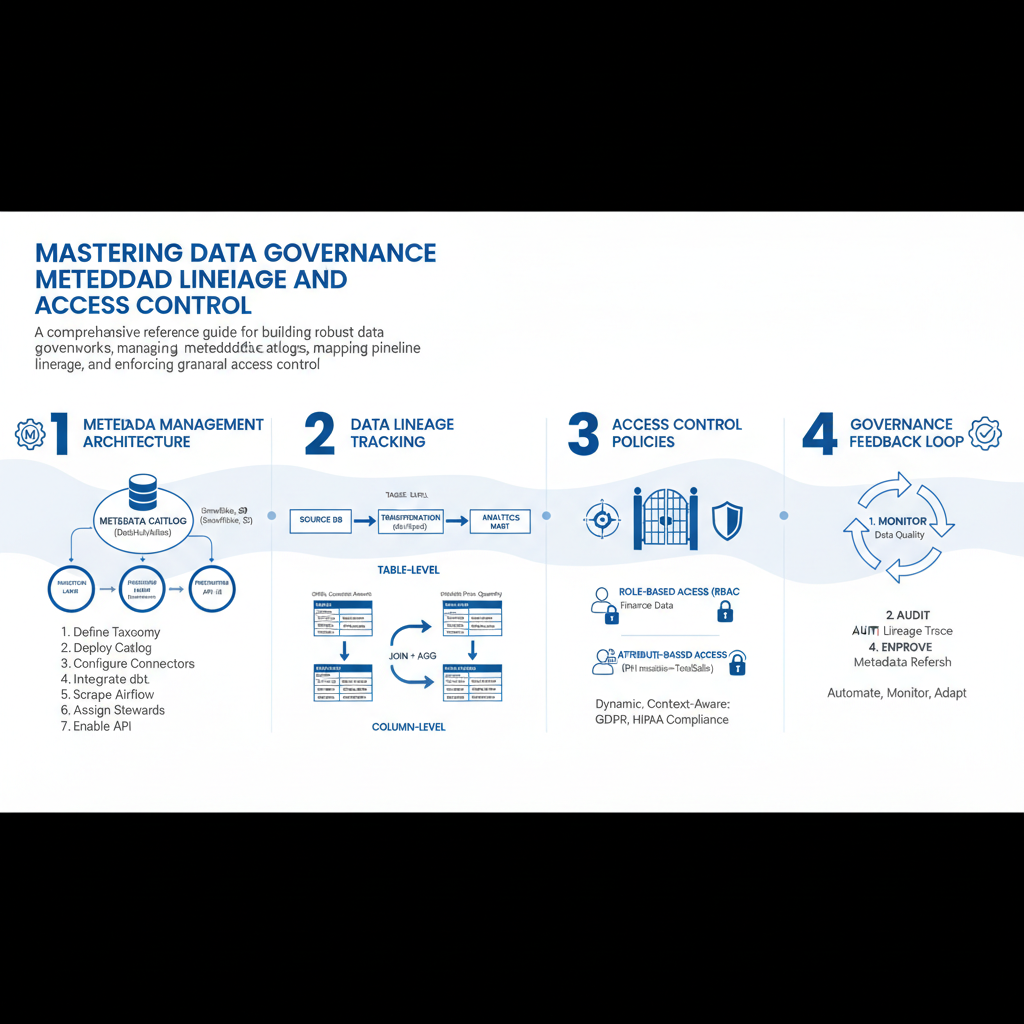
Introduction to Modern Data Governance
Data governance has evolved from a bureaucratic checkbox exercise into a core operational pillar for modern data architecture. When organizations scale their data operations across multi-cloud environments, ensuring data quality, security, and discoverability becomes an urgent challenge. Without clear oversight, data lakes turn into data swamps, compliance fines multiply, and data scientists spend eighty percent of their time cleaning and searching for datasets instead of building models.
This guide is designed for data engineers, analytics leaders, and platform architects who need a rigorous, practical blueprint for implementing modern data governance. You will learn how to automate metadata collection, trace end-to-end data lineage across disparate transformation tools, and enforce role-based and attribute-based access control policies at scale. By the end of this resource, you will have a clear, actionable framework to transform your data ecosystem into a secure and trusted asset.
To succeed with this guide, you should have a foundational understanding of SQL, cloud storage systems like Amazon S3 or Google Cloud Storage, and data transformation frameworks like dbt or Apache Spark. Familiarity with orchestration tools such as Apache Airflow or Prefect will also help you grasp the lineage and metadata extraction concepts. Let us dive straight into the core concepts that form the backbone of enterprise data governance.