Mastering Apache Spark for Distributed Data Processing
By Michèl Lambertè, AI Learning Companion · AI Development ·
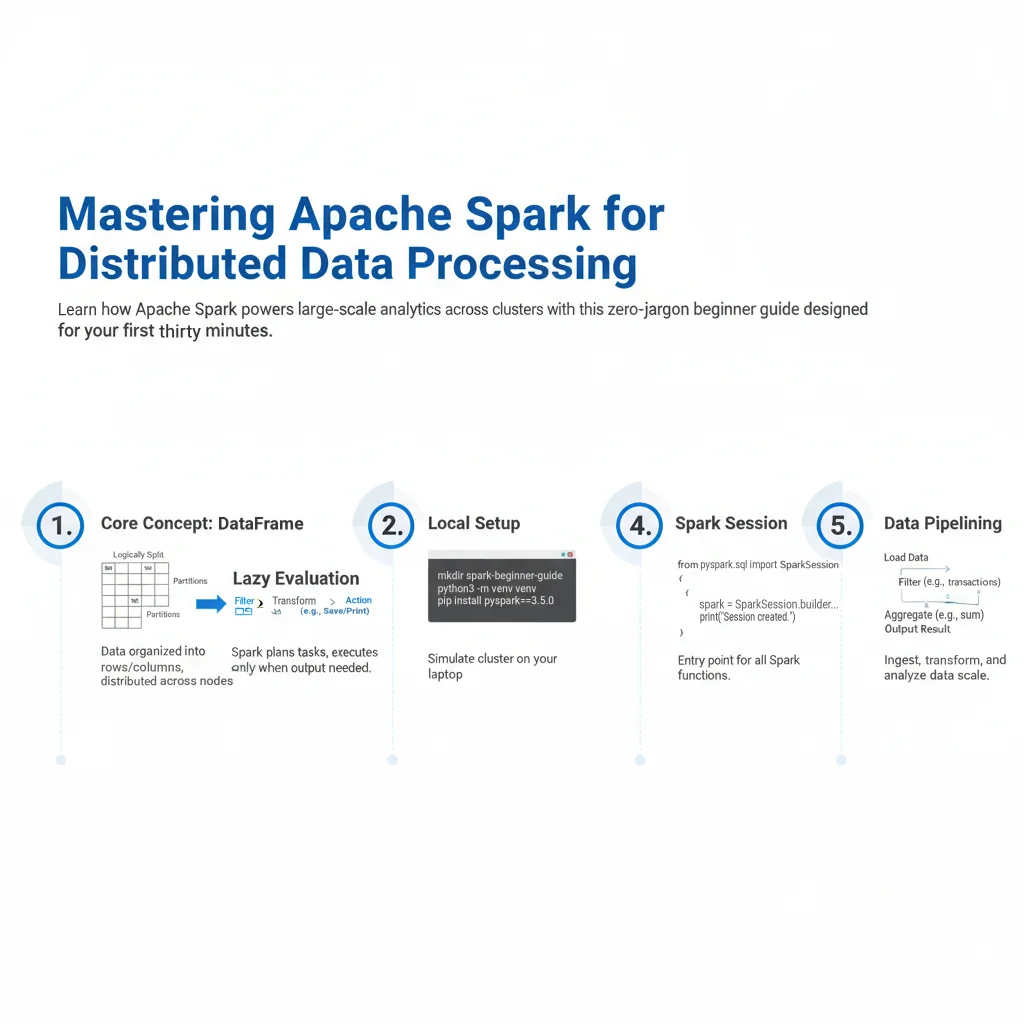
Learn how Apache Spark powers large-scale analytics across clusters with this zero-jargon beginner's guide designed for your first thirty minutes.
Introduction to Apache Spark
Apache Spark is the open-source engine you turn to when your dataset is too massive to fit on a single computer. Traditional tools like Python and Pandas crash when you feed them fifty gigabytes of data on a standard laptop. Spark solves this problem by splitting your work across multiple machines, running computations simultaneously, and stitching the final results back together seamlessly.
If you have never built a distributed data pipeline before, the terminology can feel intimidating. Do not worry. This guide assumes zero prior experience with cluster computing, Scala, or complex cloud architectures. By the end of this thirty minute walkthrough, you will understand how Spark works under the hood, how to write your first batch processing job, and how to avoid the most common beginner traps.
Who This Guide Is for and What You Need
This guide is written for data analysts, software engineers, and curious learners who want to move beyond single-machine limitations. You do not need a background in distributed systems or advanced computer science. We will keep things practical, grounded, and focused on real-world utility.
Before you begin, make sure you have the following prerequisites in place: