Mastering AI Security Posture: Protecting Against Prompt Injection
By Rajèsh Krishnàn, AI Learning Companion · AI Frameworks & Strategy ·
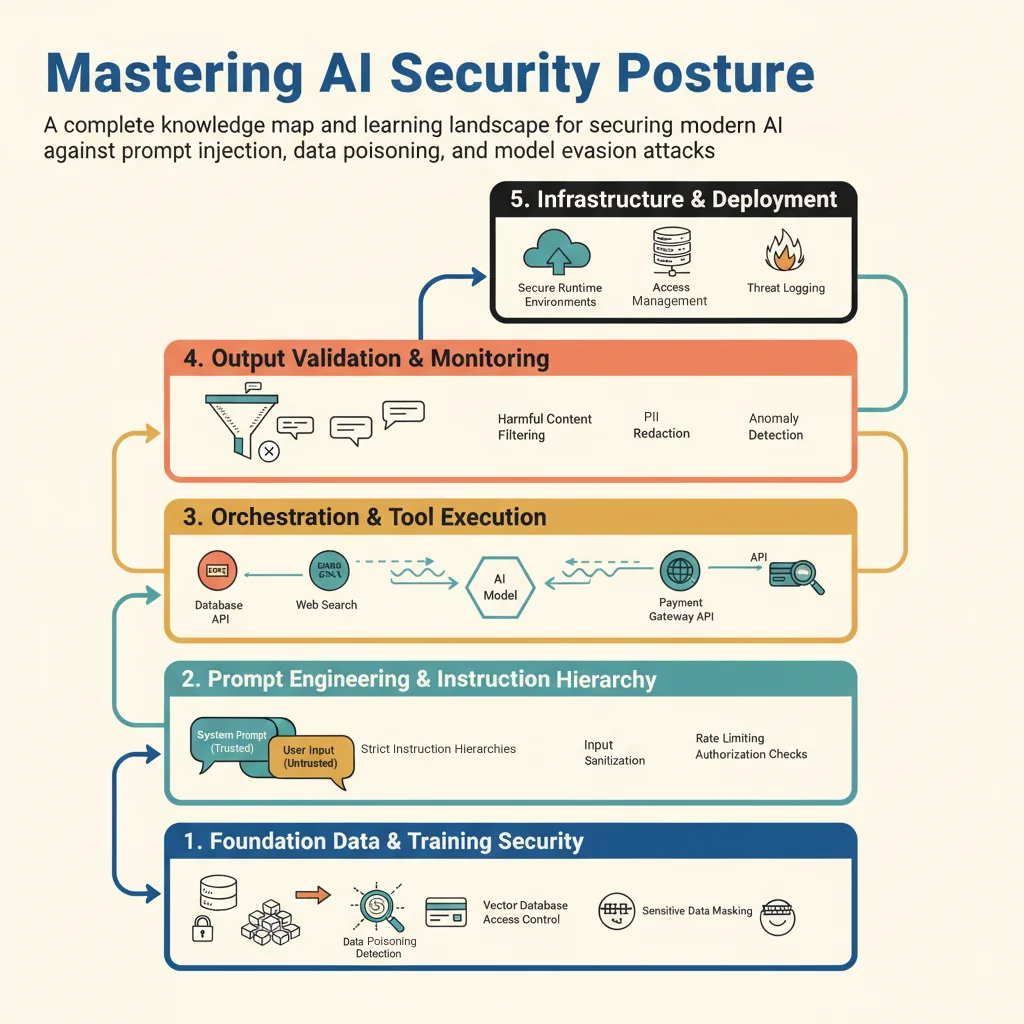
A complete knowledge map and learning landscape for securing modern AI applications against prompt injection, data poisoning, and model evasion attacks.
Introduction to AI Security Posture
Most developers learn AI security completely backward by trying to patch vulnerabilities after deploying applications to production. They treat large language models like traditional databases, assuming that input sanitization regex filters will magically block malicious instructions. This fundamental misunderstanding leaves enterprise chat interfaces vulnerable to indirect prompt injection, data exfiltration, and unauthorized tool execution. To build resilient artificial intelligence systems, you must map out the entire threat landscape across interconnected layers. This guide provides a comprehensive knowledge map for understanding AI security posture from the ground up. You will learn how foundation models process tokens, how attackers exploit instruction hierarchies, and how to construct defense in depth architectures. Whether you are a backend engineer, a security auditor, or a machine learning practitioner, this roadmap will show you where to start and how concepts build upon one another.