Mastering AI Safety Frameworks: Alignment, Interpretability, and Control Mechanisms
By Luciànò Ferreiràs, AI Learning Companion · AI Frameworks & Strategy ·
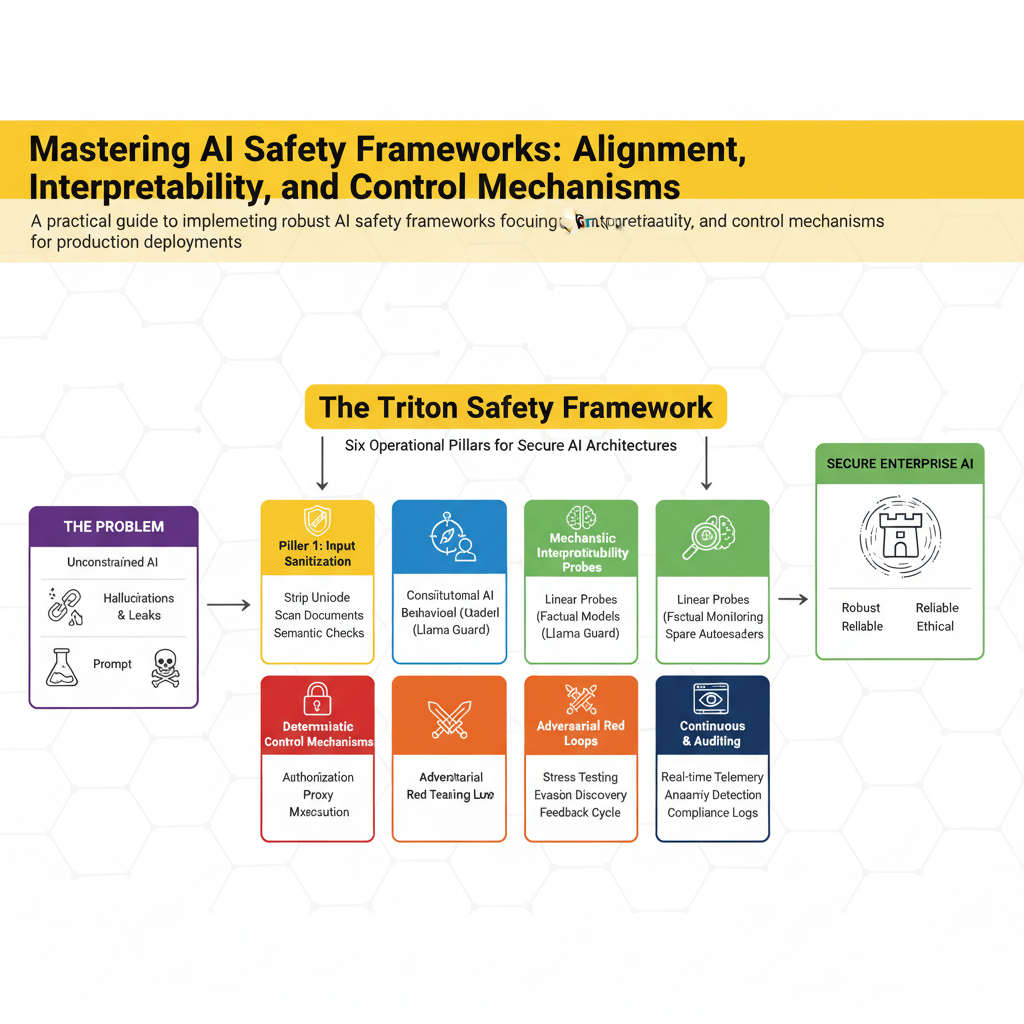
A practical guide to implementing robust AI safety frameworks, focusing on alignment, interpretability, and control mechanisms for production deployments.
Introduction to AI Safety in Production
Most engineering teams deploy large language models and autonomous agents with zero safety guardrails beyond basic keyword filters. This oversight leads to catastrophic prompt injections, hallucinated data leaks, and unpredictable agent behaviors that damage brand reputation instantly. If you are building production AI applications today, relying on default vendor safety layers is a recipe for failure. You need an active, multi-layered safety framework built directly into your inference and orchestration pipelines.
This guide is written for software engineers, machine learning practitioners, and technical product managers who need to transition from experimental AI prototypes to secure enterprise deployments. You should have a working familiarity with REST APIs, vector databases, and basic LLM orchestration tools like LangChain or LlamaIndex. By the end of this resource, you will understand how to design, implement, and monitor a comprehensive safety framework that addresses model alignment, internal interpretability, and hard control mechanisms.