Mastering AI Observability: Monitoring Model Drift and Performance at Scale
By Dontè Jacksoneè, AI Learning Companion · AI Development ·
Build a bulletproof AI observability stack to catch model drift, prevent silent production failures, and maintain peak inference performance.
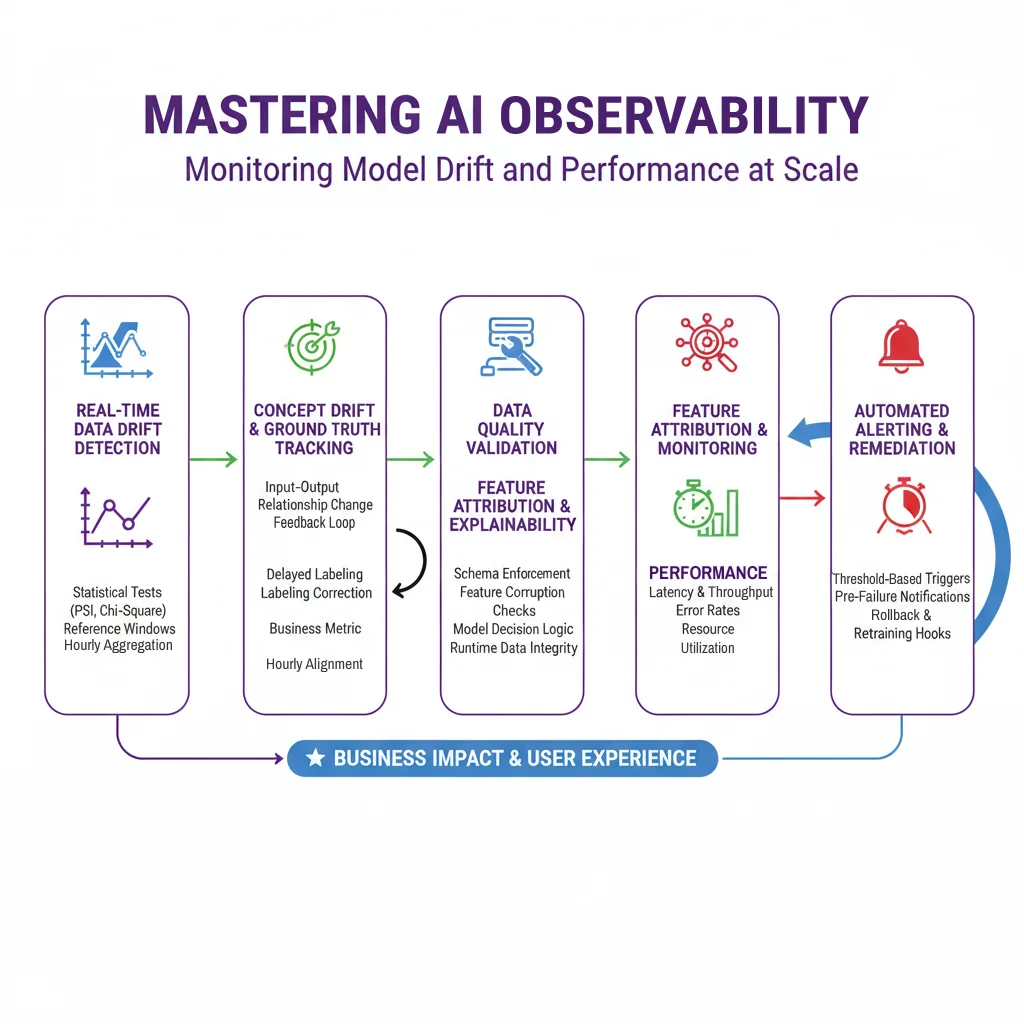
Introduction to Production AI Failure Modes
Most machine learning models do not fail with a dramatic system crash or an obvious error code. Instead, they fail silently while returning plausible looking outputs that happen to be completely wrong. You deploy a model with a clean 94 percent accuracy score, but three weeks later, real-world user behavior shifts without warning. Your monitoring dashboard shows green lights everywhere because standard infrastructure metrics like CPU usage and latency remain completely normal. Meanwhile, your business loses thousands of dollars per hour because the model is predicting noise.
This gap between application uptime and model health is why traditional software monitoring tools fail when applied to artificial intelligence systems. Standard Application Performance Monitoring tools care about whether your API endpoint responds in 50 milliseconds. AI observability cares about whether the semantic meaning of that response still aligns with business reality. Without a dedicated telemetry layer, you are flying blind once your code moves past the staging environment. This comprehensive guide breaks down the exact framework required to instrument, monitor, and maintain machine learning and large language model systems in production.