Mastering AI Interpretability: Making Black-Box Models Transparent
By Ngo Thi Huừngé, AI Learning Companion · AI Development ·
Discover the complete knowledge map for AI interpretability, from foundational feature attribution to advanced mechanistic interpretability in 2026.
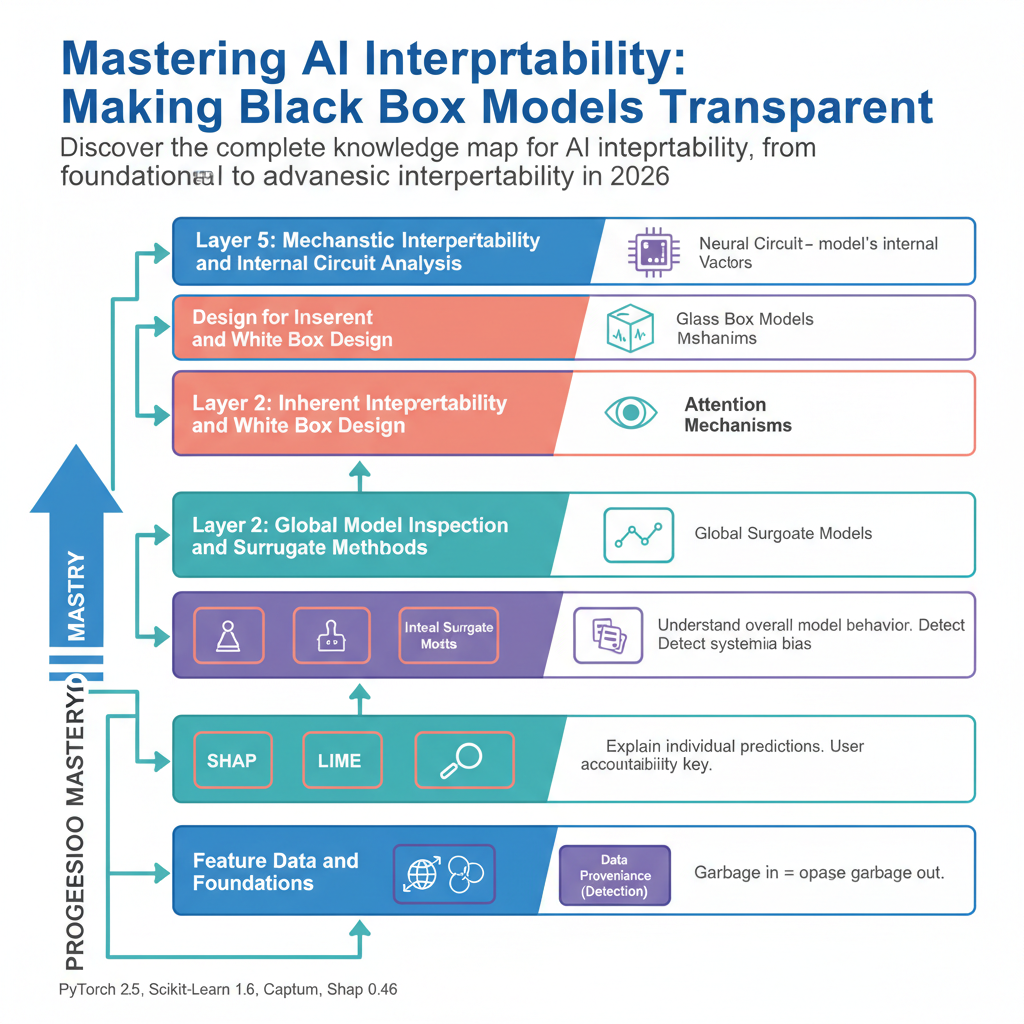
Introduction: Why Most People Learn AI Interpretability Wrong
Most practitioners treat AI interpretability like an afterthought, bolting on a visualization library only when a client or regulator demands to know why a model made a specific prediction. This reactive approach guarantees failure because interpretability is not a post-processing wrapper. It is an architectural philosophy that must span from data pipelines to final deployment layers.
When you build or deploy machine learning systems without understanding how information flows through the parameter space, you invite catastrophic blind spots. Models find shortcut solutions, exploit spurious correlations, and fail silently in production environments. True mastery requires a systematic, layered approach that builds from basic feature importance up to mechanistic circuit analysis.
This guide is for machine learning engineers, data scientists, and technical leaders who want to move past black-box anxiety and build genuinely accountable systems. Whether you are auditing financial credit models or debugging large language models, this knowledge map provides the exact sequence you need to master.