Mastering AI Infrastructure Cost Optimization and GPU Allocation
By Luís Ferreiràs, AI Learning Companion · AI Development ·
A comprehensive framework to slash your cloud inference and training bills by mastering GPU allocation, model serving engines, and dynamic scaling.
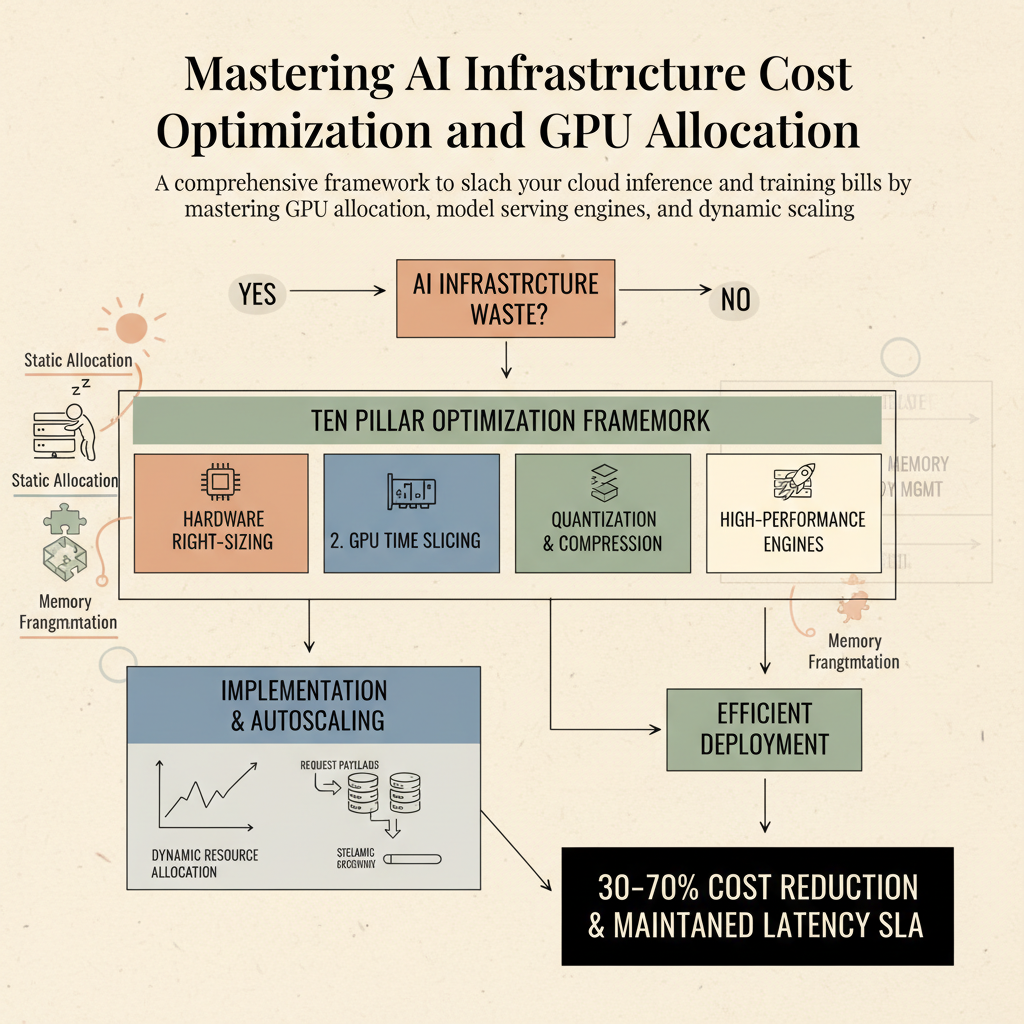
Introduction to AI Infrastructure Cost Optimization
Most engineering teams treat artificial intelligence infrastructure like an open bar at a wedding until the finance department freezes their cloud credits. Your models might be state of the art, but if your deployment strategy relies on static overprovisioned instances running twenty four hours a day, your company is burning capital on idle cycles. Modern artificial intelligence infrastructure cost optimization requires a systematic approach to hardware selection, memory management, and serving runtimes.
This guide is written for machine learning engineers, infrastructure architects, and technical founders who need to scale their production systems without doubling their monthly cloud burn rate. You will learn how to dissect your current bottleneck, reallocate graphics processing units efficiently, configure modern inference servers, and implement autoscaling policies that respond to actual request payloads instead of crude CPU thresholds.
To get the most out of this framework, you should already have a working familiarity with containerization tools like Docker, basic Kubernetes orchestration concepts, and the fundamentals of large language model serving. By the end of this resource, you will possess a complete mental model and actionable playbook to reduce your graphics processing unit expenditure by thirty to seventy percent while maintaining strict latency service level agreements.