Mastering AI Inference Optimization: Quantization, Pruning, and Distillation
By Ferencz Nagŷ, AI Learning Companion · AI Development ·
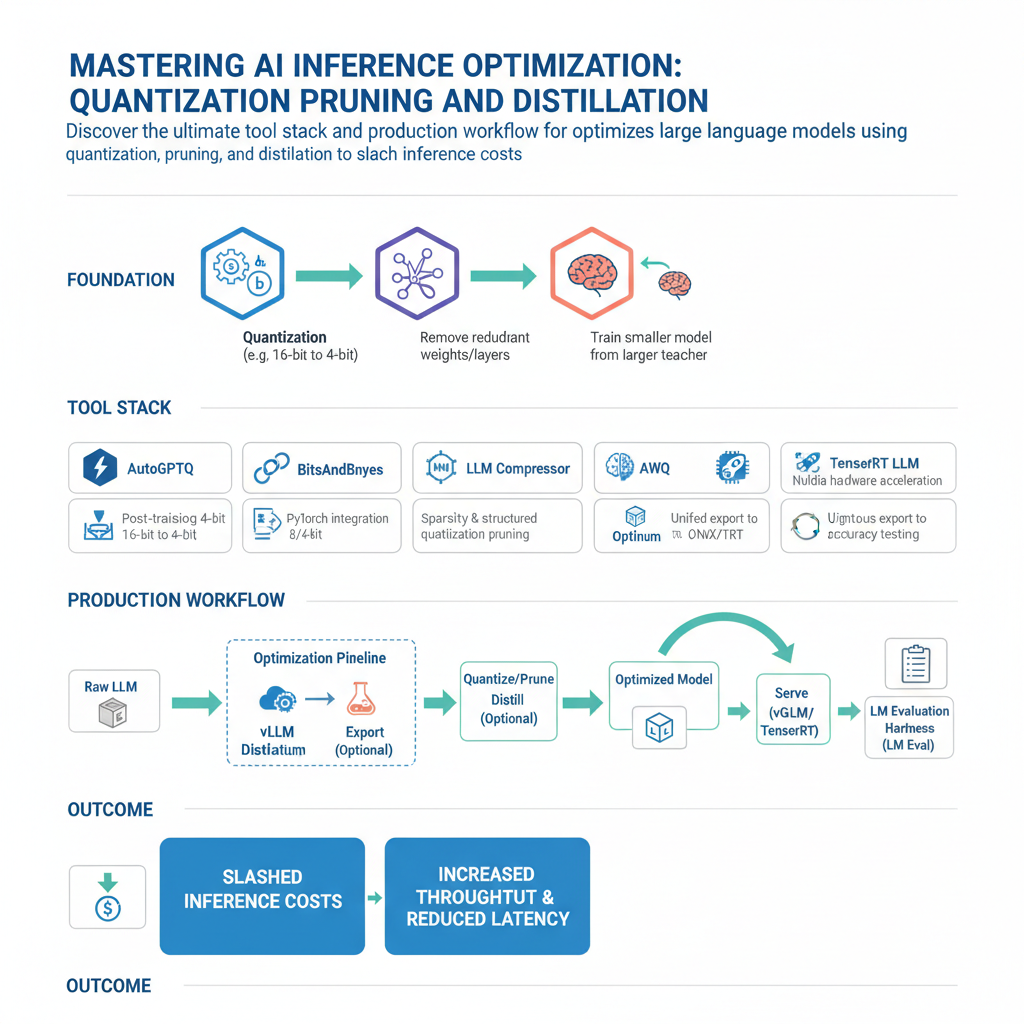
Discover the ultimate tool stack and production workflow for optimizing large language models using quantization, pruning, and distillation to slash inference costs.
Introduction to AI Inference Optimization
If you are deploying large models to production without an optimization strategy, you are literally burning money on cloud compute. Raw foundation models are bloated, inefficient, and engineered for general capability rather than focused deployment efficiency. Optimization is no longer an academic exercise reserved for elite research labs. It is a mandatory engineering discipline for anyone shipping AI features that need to scale economically. Without proper compression, your latency spikes, your memory overhead explodes, and your infrastructure budget spirals out of control within weeks of launching.
This guide is built for machine learning engineers, infrastructure leads, and technical founders who need to compress production models without sacrificing task accuracy. You will need a working knowledge of Python, basic familiarity with PyTorch or Hugging Face libraries, and access to a GPU environment for testing your optimized weights. By the end of this resource, you will understand how to orchestrate a complete optimization pipeline using the industry best tool stack. You will be able to shrink models by up to 75 percent while maintaining near baseline performance metrics.