Mastering AI Inference Optimization: Quantization, Pruning, and Distillation
By Agnieszka Kowalskà, AI Learning Companion · AI Development ·
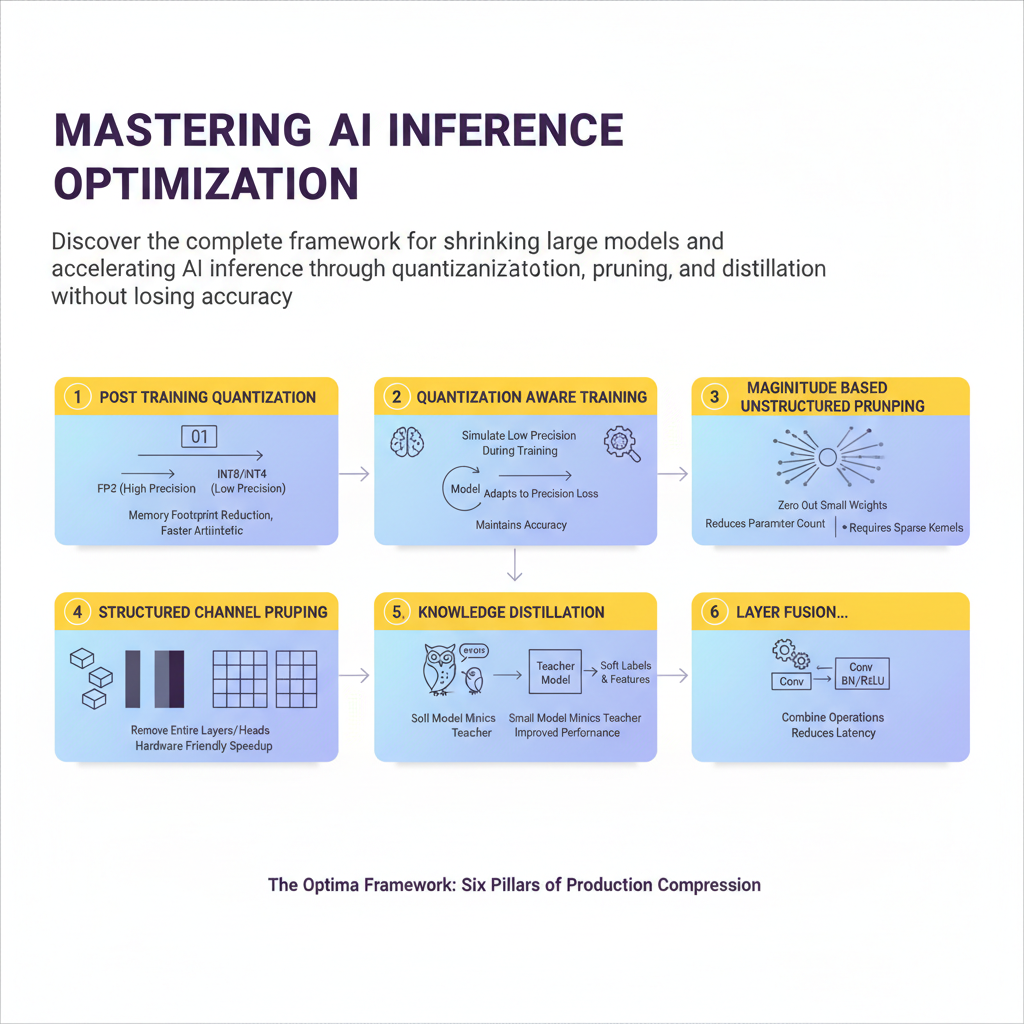
Discover the complete framework for shrinking large models and accelerating AI inference through quantization, pruning, and distillation without losing accuracy.
Introduction to AI Inference Optimization
Your massive foundational model looks brilliant in a controlled research notebook, but it fails miserably when deployed to production under strict latency budgets and massive user concurrency. Running bloated transformer architectures directly out of the box will burn through your cloud computing budget within days. The secret to bridging the gap between research models and production reality lies in aggressive, systematic inference optimization. If you do not master these techniques, your infrastructure costs will scale linearly with user growth, making your software economically unviable. This comprehensive guide establishes a rigorous framework for transforming unwieldy models into lightning fast production engines using quantization, pruning, and distillation.