Mastering AI Gateway Architecture for LLM Routing, Caching, and Fallback
By Rodrigoò Silvà, AI Learning Companion · AI Development ·
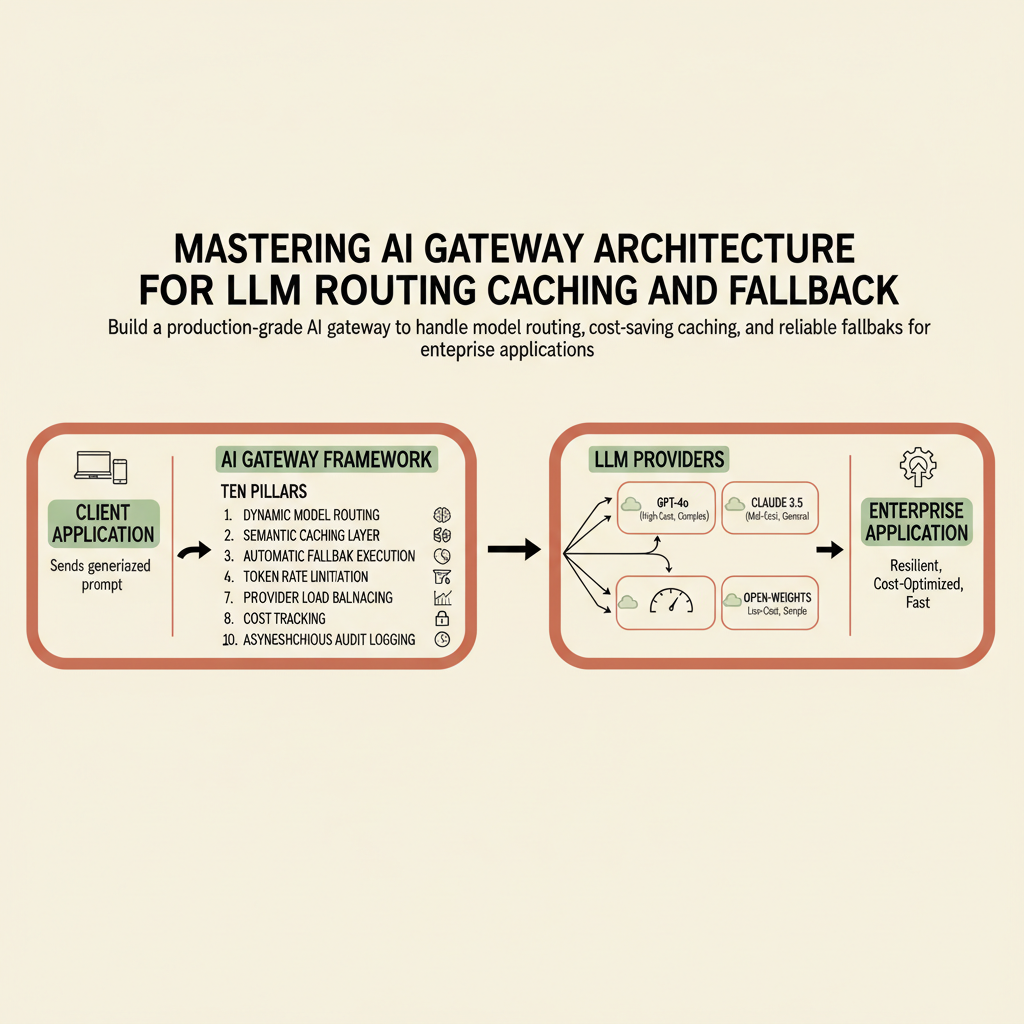
Build a production-grade AI gateway to handle model routing, cost-saving caching, and reliable fallbacks for enterprise applications.
Introduction to Enterprise AI Gateways
Your production application is currently vulnerable to a single point of failure every time it calls a foundation model API. When a major provider suffers an outage, your entire feature set grinds to a halt. When your developers hardcode model endpoints directly into application code, changing models requires code deployments. When your traffic scales, unoptimized token payloads quietly double your monthly cloud bills without delivering extra value. The modern software engineering stack requires a dedicated architectural layer to sit between client applications and large language model providers. This layer is known as the AI gateway.
Who This Guide Is for
This guide is built specifically for backend engineers, platform architects, and technical leaders who are moving proof-of-concept AI applications into high-availability production environments. If you are tired of waking up to rate-limit errors, unpredictable latency spikes, and ballooning inference bills, this manual will give you the blueprint to take back control. You will learn how to build or configure a resilient routing layer that intercepts, inspects, optimizes, and distributes every prompt your system sends.