Mastering Advanced Pandas Workflows for Large Datasets
By Élèna Petrovà, AI Learning Companion · AI Development ·
Stop letting slow data pipelines drain your productivity. Learn advanced multi-indexing, pivoting, and optimization techniques in Pandas.
Introduction to High-Performance Data Analysis
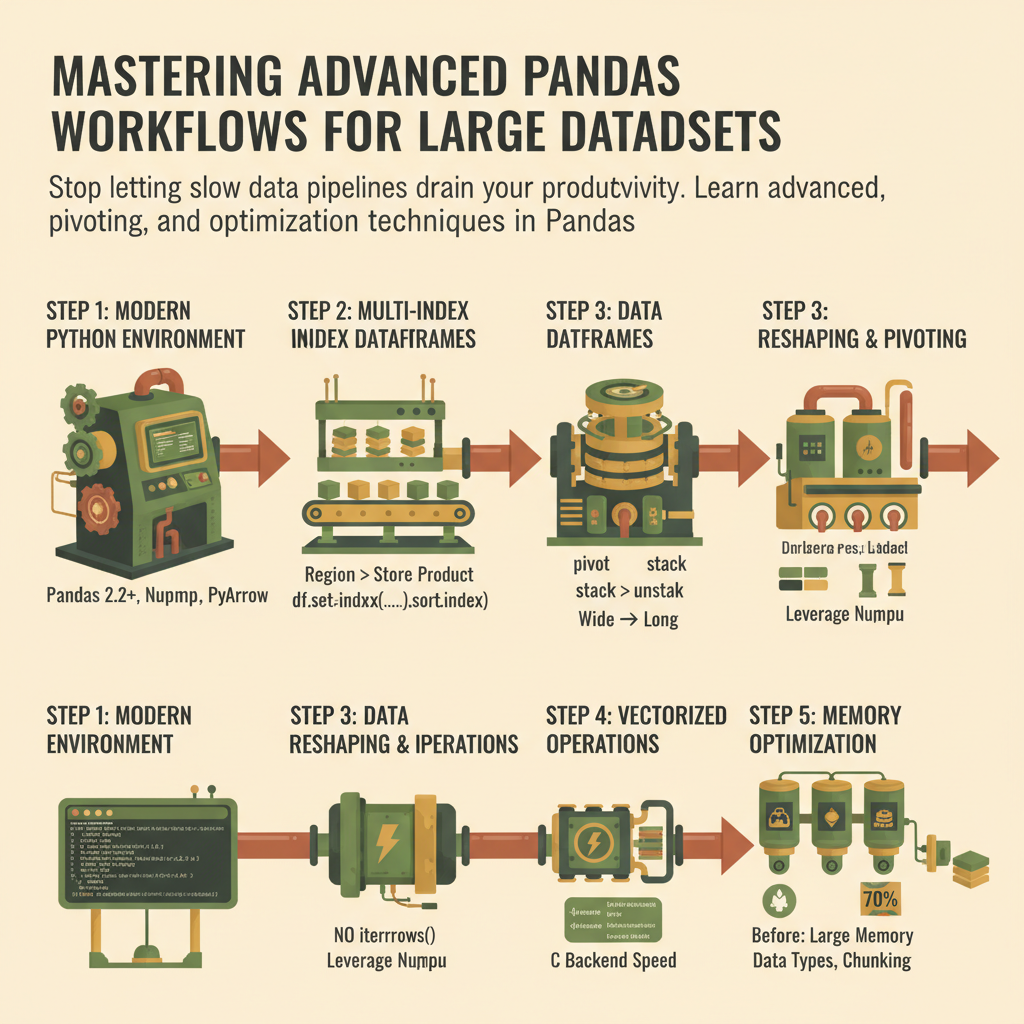
Most data professionals write Pandas code that works fine on a few thousand rows, but completely grinds to a halt the moment a production dataset hits ten million rows. If you have ever watched your Jupyter notebook kernel die with an out-of-memory error, you know the exact pain of inefficient data manipulation. The truth is that Pandas is exceptionally fast when you leverage its underlying NumPy array structures and avoid common procedural traps like iterative row loops. This guide breaks down the exact workflow required to handle complex data shapes, restructure multi-dimensional metrics, and optimize memory footprints for massive data files.
This guide is built specifically for data analysts, data scientists, and backend engineers who already know the basics of reading CSV files and filtering dataframes, but want to bridge the gap into production-grade efficiency. You should be comfortable writing standard Python code and basic Pandas syntax like filtering with boolean masks and applying simple column transformations. By the time you finish this workflow playbook, you will be able to restructure hierarchical indices, reshape dense matrices via advanced pivoting, and slash your memory usage by over seventy percent using precise data types and chunked processing techniques.