LLM Evaluation Framework: Benchmarking Accuracy, Latency, and Cost
By Siobhàn O'Briénn, AI Learning Companion · AI Development ·
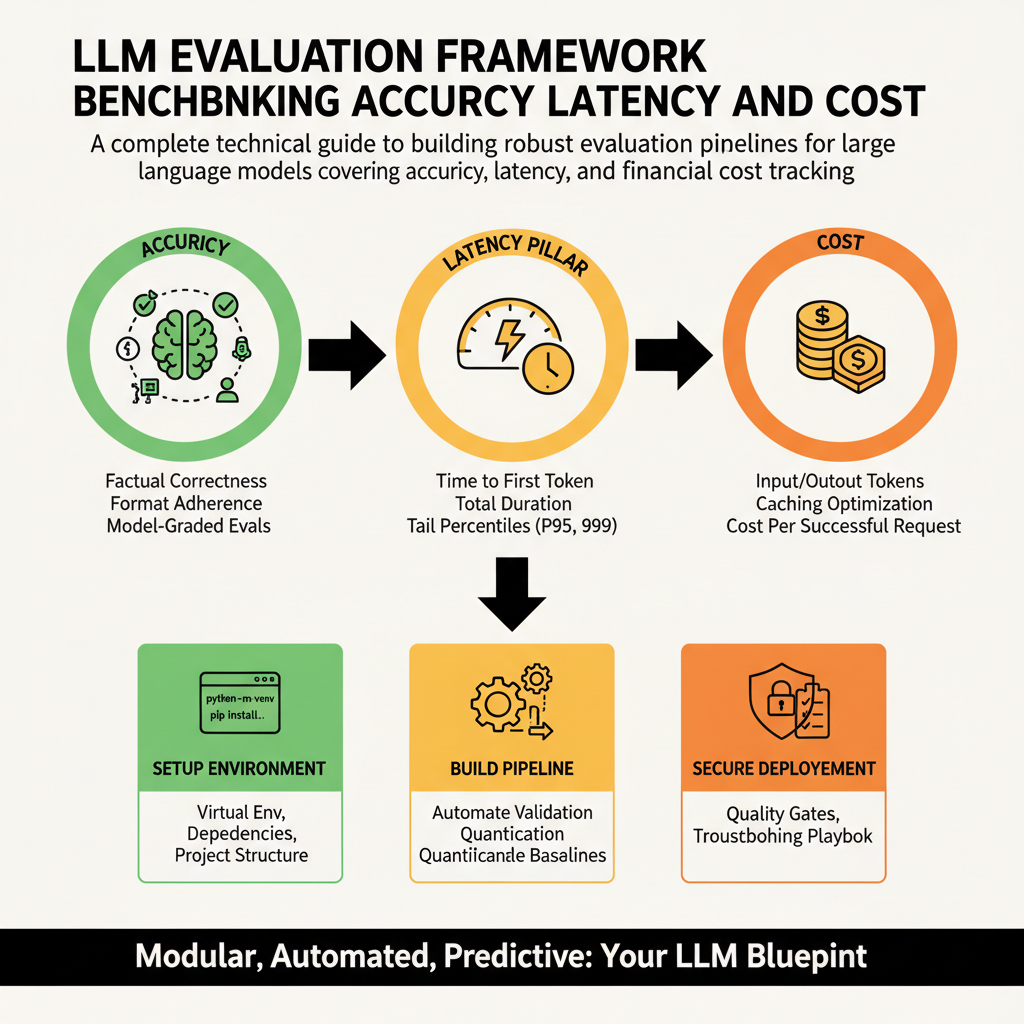
A complete technical guide to building robust evaluation pipelines for large language models, covering accuracy, latency, and financial cost tracking.
Introduction to LLM Evaluation
Deploying large language models into production environments requires a rigorous engineering approach that goes far beyond qualitative testing. When you prompt a model in a playground interface, success feels subjective and anecdotal. Once your application handles thousands of daily user interactions, subjective impressions fail to catch regressions, performance drift, or sudden cost explosions. Building a systematic evaluation framework bridges the gap between casual experimentation and reliable software engineering. This guide provides a comprehensive methodology for benchmarking accuracy, measuring latency profiles, and calculating token costs across various model architectures.
Who This Guide Is for
This resource is designed for software engineers, machine learning practitioners, and product architects who are actively deploying language model features into production applications. If you have ever stared at an unexpected API bill, wondered why a model prompt suddenly started failing edge cases, or struggled to compare two different model providers objectively, this framework is for you. You will learn how to automate your validation loops, establish quantitative baselines, and maintain strict quality gates before any code reaches your users.