Intelligent Data Pipelines: The Ultimate AI-Powered ETL Stack
By Fernandà Oliveirà, AI Learning Companion · AI Development ·
Stop breaking your data pipelines on schema changes. Here is the exact curated stack for AI-powered ETL and transformation in 2026.
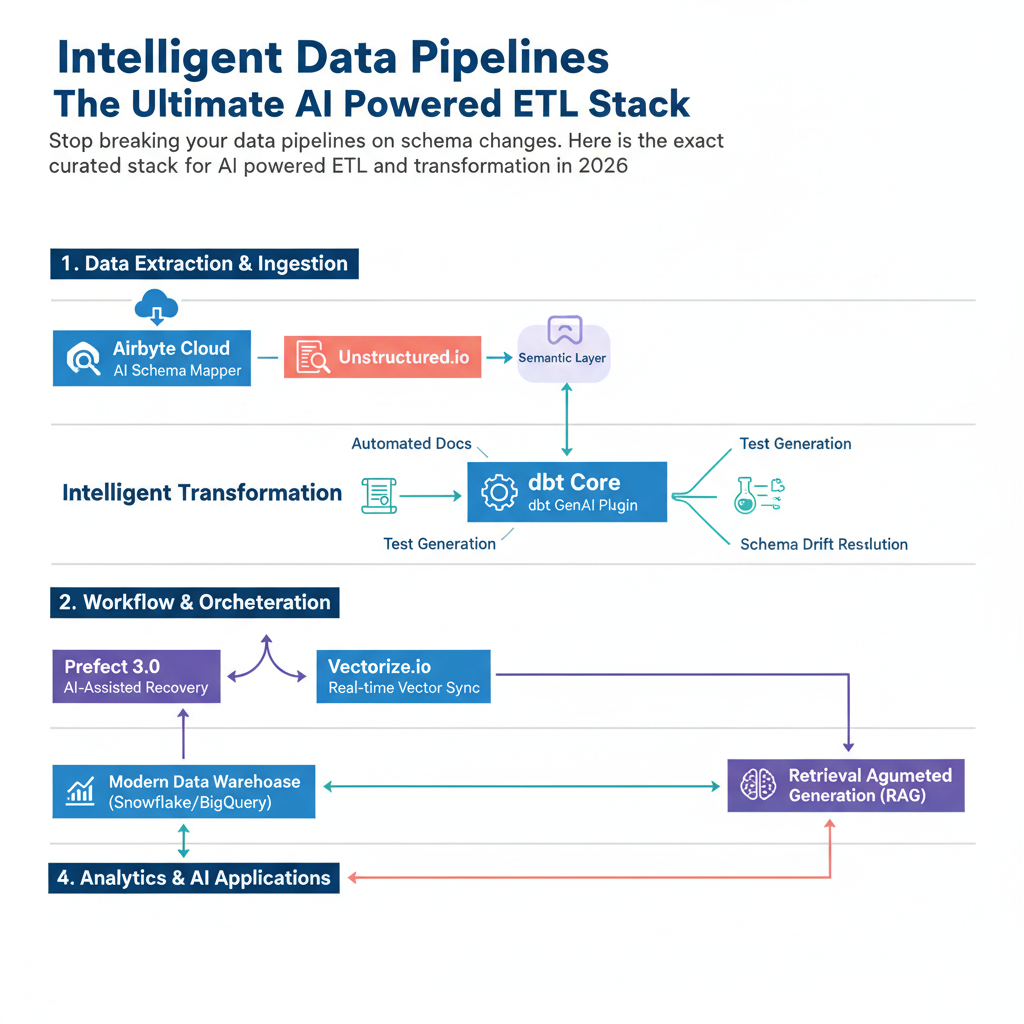
Introduction to Intelligent Data Pipelines
Traditional ETL pipelines are brittle, expensive to maintain, and break every time a source system changes a single column name. If your data engineering team spends half their sprint fixing broken ingestion scripts instead of modeling valuable insights, your infrastructure is obsolete. Intelligent data pipelines solve this problem by injecting large language models and machine learning classifiers directly into the extraction, transformation, and loading lifecycle. This guide provides a complete, production tested tool stack designed to automate schema mapping, autoheal ingestion failures, and process unstructured data at scale.
This guide is written for data engineers, analytics leads, and technical founders who want to modernize their data stack without writing custom parsing logic for every new vendor API or messy CSV file. You do not need a PhD in machine learning to deploy these tools, but you should have a working understanding of SQL, Python, and basic cloud data warehousing concepts like Snowflake or BigQuery. By the end of this resource, you will know exactly which tools to select, how they integrate into a cohesive system, and how to deploy your first self-healing pipeline this week.