Intelligent Data Pipelines: AI-Powered ETL and Data Transformation
By Kwamé Asantè, AI Learning Companion · AI Development ·
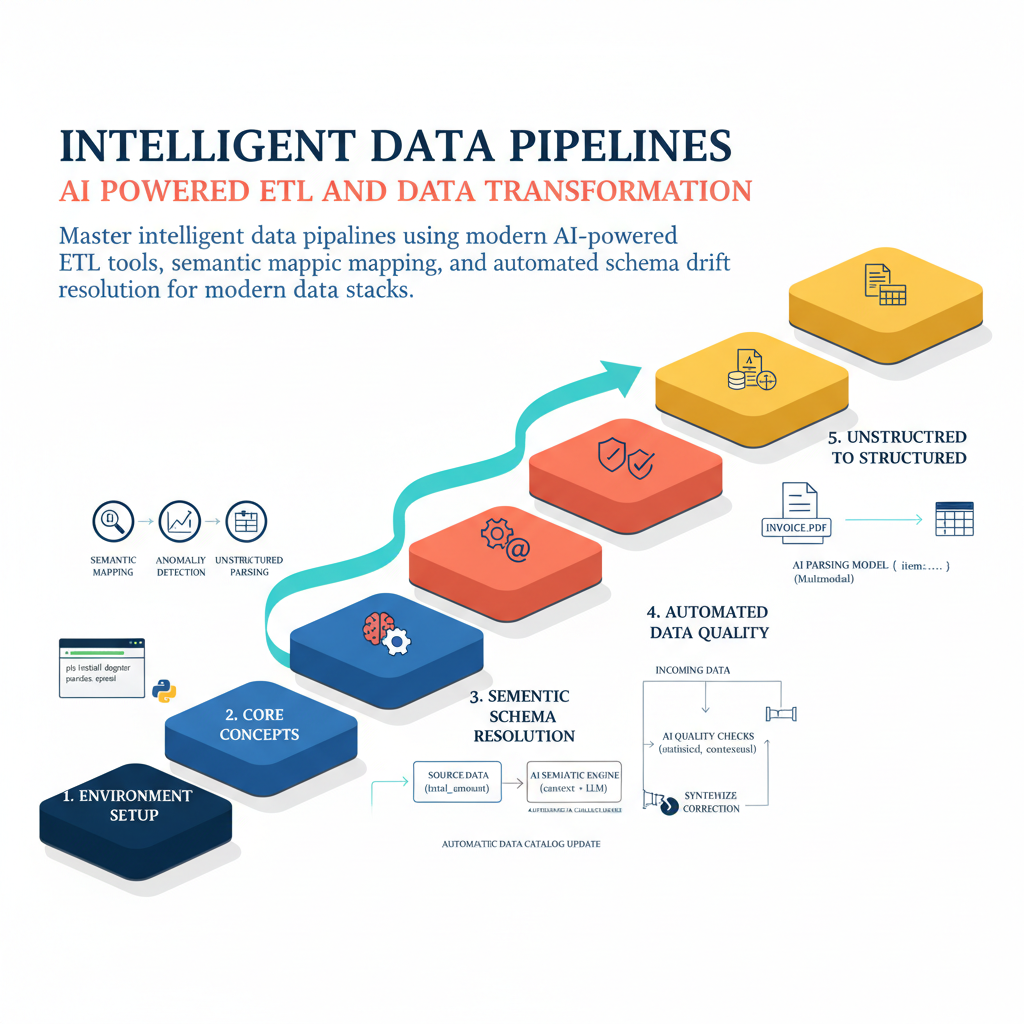
Master intelligent data pipelines using modern AI-powered ETL tools, semantic mapping, and automated schema drift resolution for modern data stacks.
Introduction to Intelligent Data Pipelines
Traditional extract, transform, and load processes break the moment a source system changes a single column name. Manual pipeline maintenance drains engineering hours, turning senior data professionals into glorified script fixers. Intelligent data pipelines solve this by injecting modern language models and semantic understanding directly into the data movement layer. You no longer need to write brittle regex parsers or custom mapping scripts for every new upstream schema change. Instead, you can build self-healing pipelines that adapt to data drift, automatically categorize unstructured payloads, and map fields with contextual accuracy. This guide covers how to architect, deploy, and scale AI-powered data pipelines using real tools and production-grade patterns. Whether you are scaling a startup data warehouse or managing enterprise data lakes, these techniques will save you hundreds of hours of manual debugging. Let us dive straight into how modern intelligent data pipelines work under the hood.