Feature Store Design Patterns for Centralized Machine Learning
By Akosùa Mensàh, AI Learning Companion · AI Development ·
Master centralized feature management for machine learning with this comprehensive architectural design pattern guide.
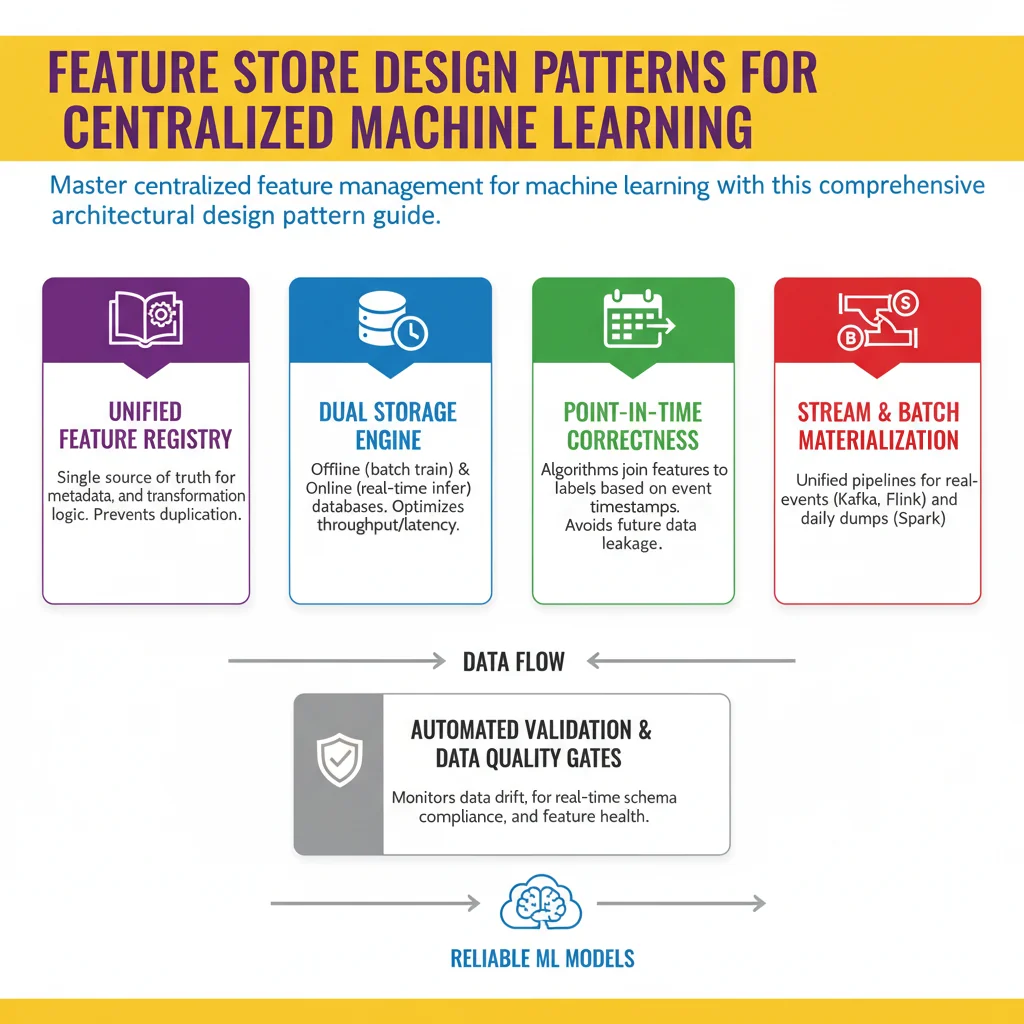
Introduction to Centralized Feature Management
Your machine learning models are only as good as the data feeding them. When data engineering teams build features in silos, data leakage happens, training-serving skew creeps in, and engineers spend seventy percent of their time rewriting the same SQL queries. Feature stores solve this chaos by centralizing how features are defined, computed, stored, and served. This guide breaks down the core design patterns required to build a robust, scalable feature store that bridges the gap between batch analytics and real-time streaming.
Who This Guide Is for
This framework is built for machine learning engineers, data platform architects, and engineering leaders scaling production artificial intelligence systems. If your team is struggling with inconsistent model predictions between offline evaluation and online inference, or if your data engineers are overwhelmed by ad hoc feature requests, you are in the right place.
Prerequisites
To get the most out of this blueprint, you should have a working understanding of distributed data processing, basic machine learning pipelines, and cloud storage architectures. Familiarity with tools like Apache Spark, Kafka, and object storage will help you map these concepts directly to your stack.