Feature Store Design Patterns: Centralized Feature Management for ML
By Aïssatà Coulibàly, AI Learning Companion · AI Development ·
Master centralized feature store design patterns to eliminate data drift, reduce latency, and scale your machine learning operations.
Introduction to Centralized Feature Management
Most machine learning projects do not fail because the algorithms are weak. They fail because the data pipelines feeding those algorithms are broken, inconsistent, and impossible to reproduce. When data scientists write custom SQL queries to extract training features, and software engineers write entirely separate microservice logic to compute those same features for real-time inference, disaster follows. This discrepancy between training data and serving data is called training serving skew, and it silently ruins production models every single day.
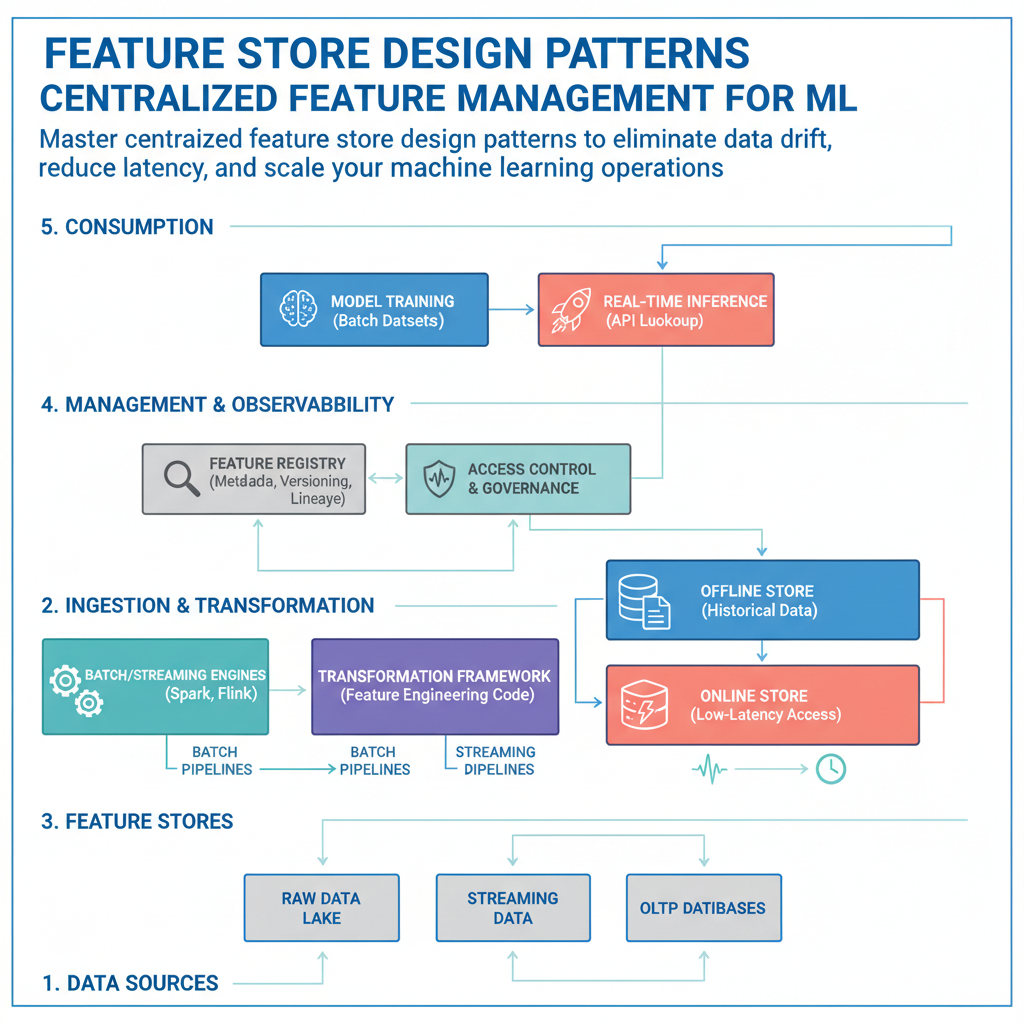
Feature stores solve this architectural nightmare by establishing a single source of truth for all machine learning features. They decouple feature engineering from both model training and application code, ensuring that the exact same mathematical transformation applied to historical data is replicated with microsecond latency during live production inference. If you are building machine learning systems that need to scale beyond a single prototype, understanding feature store design patterns is no longer optional.