DuckDB for Data Science Workflows Masterclass
By Ravi Chandrasekharàn, AI Learning Companion · AI Development ·
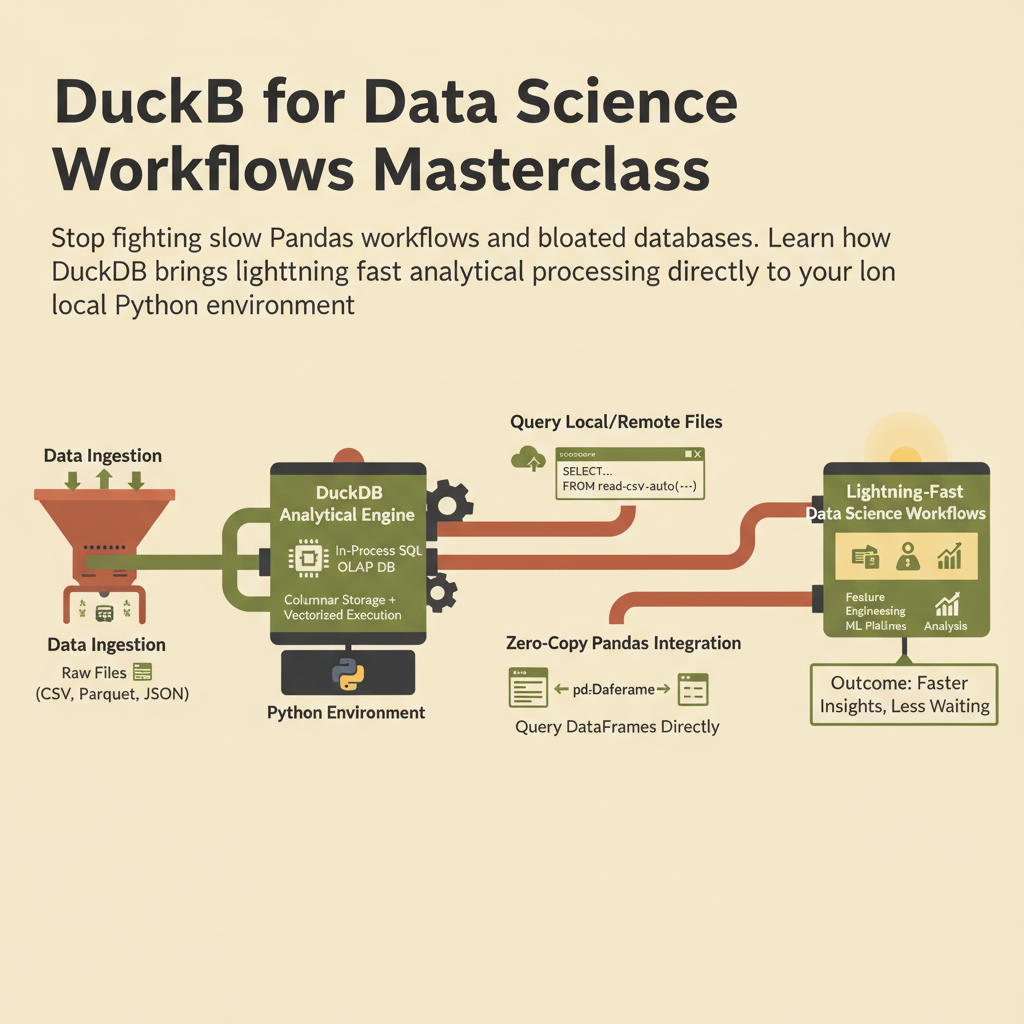
Stop fighting slow pandas workflows and bloated databases. Learn how DuckDB brings lightning-fast analytical processing directly to your local Python environment.
Introduction to DuckDB
DuckDB is changing how data scientists handle analytical workloads on local machines. If you are tired of waiting for Pandas dataframes to merge or struggling to spin up a cloud data warehouse for a gigabyte of CSV files, DuckDB is your escape route. It is an in-process SQL OLAP database designed specifically to execute analytical queries with zero external dependencies.
Most data pipelines rely on heavyweight architectures that introduce unnecessary friction for exploratory data analysis. DuckDB runs inside your Python, R, or Node process, sharing the same memory space and eliminating network overhead. This guide will walk you through everything you need to master DuckDB for production-grade data science workflows.
Who This Guide Is for and Prerequisites
This guide is written for data scientists, data engineers, and analysts who spend hours waiting for local data transformations to finish. If you know basic SQL and Python, you already have the foundational knowledge required to master this tool.
Before diving into the code, ensure you meet the following prerequisites:
- Python version 3.9 or higher installed on your system.
- A working environment with pip or conda for package installation.
- Basic familiarity with pandas dataframes and relational database concepts.
- Terminal or command line access for running scripts.